


Add architecture visualization and replace model-card tables with accessible SVG panels
8b2032c verified 

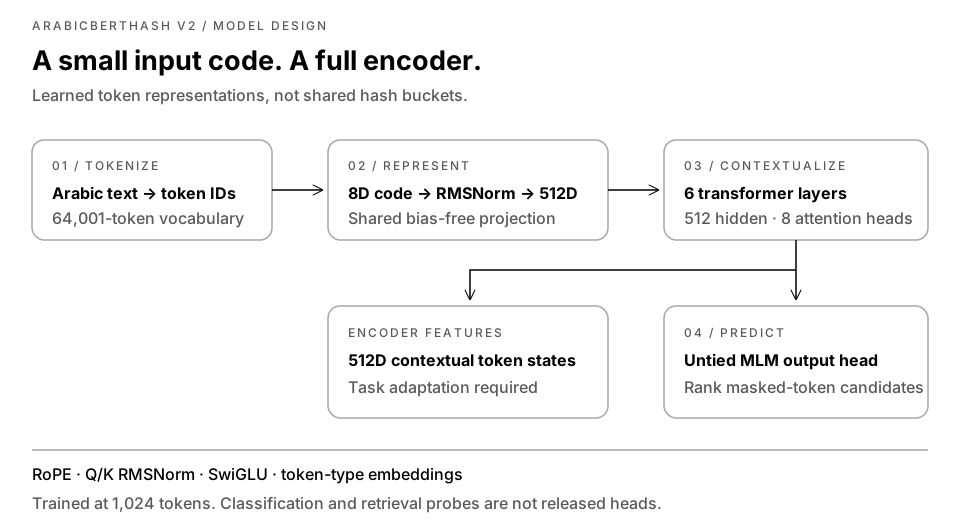


| <svg xmlns="http://www.w3.org/2000/svg" width="960" height="530" viewBox="0 0 960 530" role="img" aria-labelledby="title desc"> | |
| <title id="title">ArabicBertHash v2 — from compact codes to masked-token predictions</title> | |
| <desc id="desc">Arabic text is tokenized into a vocabulary of 64,001 tokens. Each token selects an eight-dimensional learned code, normalized and projected to 512 dimensions. Token-type embeddings are added. Six bidirectional transformer layers use RoPE, Q/K RMSNorm and SwiGLU. The untied MLM head predicts vocabulary tokens; encoder states are available for feature extraction.</desc> | |
| <style>text{font-family:Inter,Arial,sans-serif;fill:currentColor;font-size:16px}.title{font-size:27px;font-weight:700}.label{font-size:12px;letter-spacing:2px;opacity:.65}.strong{font-weight:700}.muted{opacity:.65}.box{fill:none;stroke:currentColor;stroke-opacity:.35;stroke-width:1.5}.wire{fill:none;stroke:currentColor;stroke-width:1.5}</style> | |
| <defs><marker id="arrow" viewBox="0 0 10 10" refX="9" refY="5" markerWidth="7" markerHeight="7" orient="auto-start-reverse"><path d="M0 0 10 5 0 10" fill="none" stroke="currentColor"/></marker></defs> | |
| <text x="32" y="30" class="label">ARABICBERTHASH V2 / MODEL DESIGN</text> | |
| <text x="32" y="70" class="title">A small input code. A full encoder.</text> | |
| <text x="32" y="101" class="muted">Learned token representations, not shared hash buckets.</text> | |
| <rect x="32" y="140" width="240" height="100" rx="12" class="box"/> | |
| <text x="52" y="170" class="label">01 / TOKENIZE</text><text x="52" y="199" class="strong">Arabic text → token IDs</text><text x="52" y="224" class="muted">64,001-token vocabulary</text> | |
| <path d="M272 190H322" class="wire" marker-end="url(#arrow)"/> | |
| <rect x="328" y="140" width="280" height="100" rx="12" class="box"/> | |
| <text x="348" y="170" class="label">02 / REPRESENT</text><text x="348" y="199" class="strong">8D code → RMSNorm → 512D</text><text x="348" y="224" class="muted">Shared bias-free projection</text> | |
| <path d="M608 190H658" class="wire" marker-end="url(#arrow)"/> | |
| <rect x="664" y="140" width="264" height="100" rx="12" class="box"/> | |
| <text x="684" y="170" class="label">03 / CONTEXTUALIZE</text><text x="684" y="199" class="strong">6 transformer layers</text><text x="684" y="224" class="muted">512 hidden · 8 attention heads</text> | |
| <path d="M796 240V299" class="wire" marker-end="url(#arrow)"/> | |
| <rect x="664" y="306" width="264" height="112" rx="12" class="box"/> | |
| <text x="684" y="337" class="label">04 / PREDICT</text><text x="684" y="366" class="strong">Untied MLM output head</text><text x="684" y="393" class="muted">Rank masked-token candidates</text> | |
| <path d="M796 270H470V299" class="wire" marker-end="url(#arrow)"/> | |
| <rect x="328" y="306" width="280" height="112" rx="12" class="box"/> | |
| <text x="348" y="337" class="label">ENCODER FEATURES</text><text x="348" y="366" class="strong">512D contextual token states</text><text x="348" y="393" class="muted">Task adaptation required</text> | |
| <path d="M32 450H928" class="box"/> | |
| <text x="32" y="480">RoPE · Q/K RMSNorm · SwiGLU · token-type embeddings</text> | |
| <text x="32" y="509" class="muted">Trained at 1,024 tokens. Classification and retrieval probes are not released heads.</text> | |
| </svg> | |