
Spaces:
Running on Zero

Running on Zero
Replace 2511 sheet with verified Qwen Image 2.1 turbo, mannequin guides and PNG-only export
Browse files- .gitattributes +8 -0
- .gitignore +2 -14
- LICENSE +202 -0
- NOTICE +13 -0
- README.md +178 -326
- angles_adapter.py +128 -0
- app.py +113 -683
- assets/cowboy_back.png +3 -0
- assets/cowboy_front.png +3 -0
- assets/face_front.png +0 -0
- assets/full_back.png +3 -0
- assets/full_front.png +3 -0
- assets/full_left.png +0 -0
- assets/full_right.png +0 -0
- assets/knees_back.png +3 -0
- assets/knees_front.png +3 -0
- assets/pose_preview.png +3 -0
- assets/prone_back.png +3 -0
- assets/upper_front.png +0 -0
- backend.py +92 -0
- bench/README.md +0 -102
- bench/app.py +0 -288
- bench/requirements.txt +0 -20
- benchmark_local.py +415 -0
- core.py +151 -0
- framing.py +0 -59
- optimization.py +0 -167
- pose_guides.py +330 -0
- qwenimage/__init__.py +0 -0
- qwenimage/qwen_fa3_processor.py +0 -142
- requirements.txt +4 -30
- tagging.py +0 -441
- tests/test_core.py +321 -0
- views.py +82 -436
.gitattributes
CHANGED
|
@@ -33,3 +33,11 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/cowboy_back.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
assets/cowboy_front.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
assets/full_back.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
assets/full_front.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
assets/knees_back.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
assets/knees_front.png filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
assets/pose_preview.png filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
assets/prone_back.png filter=lfs diff=lfs merge=lfs -text
|
.gitignore
CHANGED
|
@@ -1,16 +1,4 @@
|
|
| 1 |
__pycache__/
|
| 2 |
-
*.
|
| 3 |
.venv/
|
| 4 |
-
|
| 5 |
-
ref_test.png
|
| 6 |
-
verify.py
|
| 7 |
-
exp/
|
| 8 |
-
exp2/
|
| 9 |
-
exp3/
|
| 10 |
-
out2/
|
| 11 |
-
out3/
|
| 12 |
-
experiment*.py
|
| 13 |
-
test_cpu_quant.py
|
| 14 |
-
*.log
|
| 15 |
-
live/
|
| 16 |
-
live_dataset.zip
|
|
|
|
| 1 |
__pycache__/
|
| 2 |
+
*.py[cod]
|
| 3 |
.venv/
|
| 4 |
+
.env
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright [yyyy] [name of copyright owner]
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
NOTICE
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Character View Sheet - Turbo Trial
|
| 2 |
+
|
| 3 |
+
The eleven-view selection and feature requirements are based on:
|
| 4 |
+
https://huggingface.co/spaces/darask0/Qwen-Image-Edit-2511-Lora-Sheet
|
| 5 |
+
Upstream Space by darask0 and contributors (Apache-2.0).
|
| 6 |
+
|
| 7 |
+
This package contains a rewritten experimental application, a procedural
|
| 8 |
+
mannequin renderer, its rendered assets, and CPU-only behavioral tests.
|
| 9 |
+
It does not include model weights or generated character training data.
|
| 10 |
+
|
| 11 |
+
The application code and procedural mannequin assets are distributed under
|
| 12 |
+
Apache-2.0. Model weights remain subject to their respective upstream licenses.
|
| 13 |
+
Qwen-Image-2.1-Turbo uses the Qwen Research License, not Apache-2.0.
|
README.md
CHANGED
|
@@ -1,346 +1,198 @@
|
|
| 1 |
---
|
| 2 |
-
title: Character View Sheet (Qwen
|
| 3 |
emoji: 🎨
|
| 4 |
-
colorFrom:
|
| 5 |
-
colorTo:
|
| 6 |
sdk: gradio
|
| 7 |
sdk_version: 5.49.1
|
|
|
|
| 8 |
app_file: app.py
|
| 9 |
pinned: false
|
| 10 |
license: apache-2.0
|
| 11 |
-
short_description:
|
| 12 |
---
|
| 13 |
|
| 14 |
-
#
|
| 15 |
-
|
| 16 |
-
参照キャラクター画像を
|
| 17 |
-
**11
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
| 23 |
-
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
- 仰角 (4): `low-angle shot` / `eye-level shot` / `elevated shot` / `high-angle shot`
|
| 89 |
-
- 距離 (3): `close-up` / `medium shot` / `wide shot`
|
| 90 |
-
|
| 91 |
-
この語彙以外の文字列は効かない。「うつ伏せを後ろから見下ろす」構図が
|
| 92 |
-
`back view` + `high-angle shot` として厳密に指定できるのがこの方式の利点。
|
| 93 |
-
|
| 94 |
-
### 生成の流れ
|
| 95 |
-
|
| 96 |
-
1. ユーザーの参照画像から **立ちポーズの基準画像 (アンカー)** を作る。
|
| 97 |
-
2. 各視点は、そのポーズのアンカーを条件入力にして**カメラだけを動かして**生成する。
|
| 98 |
-
3. ポーズが違う視点 (膝抱え / うつ伏せ) は、立ちアンカーからそのポーズのアンカーを作り、
|
| 99 |
-
そこからカメラを動かす。
|
| 100 |
-
4. アンカーのカメラと一致する視点は、アンカー画像をそのまま流用して生成を 1 回省く。
|
| 101 |
-
|
| 102 |
-
全 11 視点を選んだ場合、生成回数はちょうど 11 回。一部だけ選んだ場合は必要なアンカーだけが
|
| 103 |
-
作られる (例: 「膝抱え 背面」だけを選ぶと 立ち → 膝抱え → 背面 の 3 回)。
|
| 104 |
-
|
| 105 |
-
## ZeroGPU クォータ設計
|
| 106 |
-
|
| 107 |
-
**要点: ZeroGPU のクォータは「実行時間」ではなく「要求した `duration`」ぶん消費される。**
|
| 108 |
-
10 秒で終わる処理でも 60 秒要求すれば 60 秒引かれる。入場判定も
|
| 109 |
-
`残りクォータ < 要求 duration` で即拒否される。
|
| 110 |
-
|
| 111 |
-
| アカウント | 1 日のクォータ |
|
| 112 |
-
|---|---|
|
| 113 |
-
| 未認証 | 120 秒 |
|
| 114 |
-
| 無料会員 | 300 秒 |
|
| 115 |
-
| PRO | 2400 秒 (延長可) |
|
| 116 |
-
|
| 117 |
-
さらに **`xlarge` は要求 duration の 2 倍が引かれる**。本モデルは 53.8GB あり
|
| 118 |
-
`large` (48GB) に載らないため `xlarge` 必須で、この 2 倍が常にかかる。
|
| 119 |
-
|
| 120 |
-
既定では**分割せず 1 回の GPU 呼び出しにまとめる** (`CHUNK_SIZE=12`)。
|
| 121 |
-
分割すると GPU 取得の固定費 (約 9 秒) を毎回払い、それも 2 倍されるため、
|
| 122 |
-
総消費がかえって増える。分割の利点 (残クォータが少なくても途中まで進める) より、
|
| 123 |
-
総量を抑えるほうが無料枠では効く。
|
| 124 |
-
|
| 125 |
-
| 選択 | 生成枚数 | 要求 | **実消費** | 無料 (300秒) | 未認証 (120秒) |
|
| 126 |
-
|---|:---:|:---:|:---:|:---:|:---:|
|
| 127 |
-
| 全 11 視点 | 11 | 67 秒 | **134 秒** | ✅ 1日2回 | ❌ |
|
| 128 |
-
| 全 11 視点 (高品質モード) | 11 | 83 秒 | 166 秒 | ✅ | ❌ |
|
| 129 |
-
| 三面図のみ (4視点) | 4 | 32 秒 | 64 秒 | ✅ | ✅ |
|
| 130 |
-
| 最小構成 (2視点) | 2 | 22 秒 | 44 秒 | ✅ | ✅ |
|
| 131 |
-
|
| 132 |
-
> 見積り式は `duration = 12 + 5 × 枚数`。係数は環境変数
|
| 133 |
-
> `CALL_OVERHEAD_SEC` / `PER_VIEW_SEC` / `CHUNK_SIZE` で調整できる。
|
| 134 |
-
|
| 135 |
-
**ZeroGPU 実測 (xlarge / MIG 4g.96gb / bf16)**
|
| 136 |
-
|
| 137 |
-
| 項目 | 実測 |
|
| 138 |
-
|---|---|
|
| 139 |
-
| GPU 取得 + モデル転送 | 約 9 秒 |
|
| 140 |
-
| 1 枚目 (ウォームアップ込) | 4.8 秒 |
|
| 141 |
-
| 2 枚目以降 | **2.9 秒/枚** (832×1216, 4 step) |
|
| 142 |
-
| 4 枚チャンクの GPU 時間 | 13.5 秒 |
|
| 143 |
-
| 全 11 視点の実行 (DL・タグ付け・ZIP 込み) | 約 255 秒 |
|
| 144 |
-
|
| 145 |
-
参考: ローカルの RTX PRO 6000 Blackwell (フル 96GB / fp8) では 4.4 秒/枚だった。
|
| 146 |
-
ZeroGPU の `xlarge` は MIG 4g.96gb で、実測ではこちらのほうが速い。
|
| 147 |
-
|
| 148 |
-
なお一部の視点は、寄りの切り出し元やポーズ基準として**中間生成**を必要とする。
|
| 149 |
-
例えば「カウボーイ背面」だけを選んだ場合は 立ち → 全身背面 → カウボーイ背面 の
|
| 150 |
-
3 回生成になる。UI のクォータ表示はこの中間生成も含めた実消費秒数を出す。
|
| 151 |
-
|
| 152 |
-
> **未達の目標**: 当初は未認証ユーザー (120 秒) でも全 11 視点を通すことを狙っていたが、
|
| 153 |
-
> `xlarge` 強制により 134 秒となり達成できていない。`large` (2 倍消費なし) に戻すには
|
| 154 |
-
> モデルを 42 GiB 未満に縮める必要がある (fp8 transformer の採用など)。
|
| 155 |
-
|
| 156 |
-
## 高速化 (fp8 + FlashAttention-3 + AoTI)
|
| 157 |
-
|
| 158 |
-
ZeroGPU は 2026/05 に **H200 (~70GB) から RTX Pro 6000 Blackwell** へ移行し、
|
| 159 |
-
既定の `large` サイズは **48GB** になった。Qwen-Image-Edit-2511 は bf16 で
|
| 160 |
-
|
| 161 |
-
- transformer: 40.9 GB
|
| 162 |
-
- text encoder (Qwen2.5-VL-7B): 16.6 GB
|
| 163 |
-
- 合計: **約 57 GB**
|
| 164 |
-
|
| 165 |
-
あり、余裕がない。そのため `optimization.py` で
|
| 166 |
-
|
| 167 |
-
1. FlashAttention-3 の attention processor を適用
|
| 168 |
-
2. torchao の fp8 動的量子化 (transformer を約半分に)
|
| 169 |
-
3. PyTorch ahead-of-time コンパイル (`spaces.aoti_compile`)
|
| 170 |
-
|
| 171 |
-
を行う。速度改善 (1.3-1.8×) 以上に **VRAM を削ること**が目的。
|
| 172 |
-
系列長を動的次元にしてあるので、視点ごとに解像度が変わっても再コンパイルは走らない。
|
| 173 |
-
|
| 174 |
-
### fp8 量子化を CPU 側でやってはいけない (デプロイして判明)
|
| 175 |
-
|
| 176 |
-
ローカル GPU では「CPU で量子化してから GPU へ転送」がロード時ピークを
|
| 177 |
-
**55.1GB → 34.8GB** に下げられて有利だった。しかし **ZeroGPU では動かない**。
|
| 178 |
-
|
| 179 |
-
ZeroGPU はモジュール階層の `.to("cuda")` を CUDA エミュレーション層
|
| 180 |
-
(`spaces/zero/torch/patching.py`) で横取りし、テンソルを `aten.empty_like` で
|
| 181 |
-
スナップショットする。torchao の `Float8Tensor` はこの演算を実装していないため、
|
| 182 |
-
起動時に `NotImplementedError` で落ちる。
|
| 183 |
-
|
| 184 |
-
```
|
| 185 |
-
NotImplementedError: Float8Tensor dispatch: attempting to run unimplemented
|
| 186 |
-
operator/function: func=<OpOverload(op='aten.empty_like', overload='default')>
|
| 187 |
```
|
| 188 |
|
| 189 |
-
|
| 190 |
-
|
| 191 |
-
|
| 192 |
-
|
| 193 |
-
|
| 194 |
-
|
| 195 |
-
|
| 196 |
-
|
| 197 |
-
|
| 198 |
-
|
| 199 |
-
で
|
| 200 |
-
|
| 201 |
-
|
| 202 |
-
|
| 203 |
-
|
| 204 |
-
|
| 205 |
-
|
| 206 |
-
|
| 207 |
-
|
| 208 |
-
|
| 209 |
-
|
| 210 |
-
|
| 211 |
-
|
|
| 212 |
-
|
|
| 213 |
-
|
|
| 214 |
-
|
|
| 215 |
-
|
| 216 |
-
|
| 217 |
-
|
| 218 |
-
|
| 219 |
-
|
| 220 |
-
|
| 221 |
-
|
| 222 |
-
|
| 223 |
-
|
| 224 |
-
|
| 225 |
-
|
| 226 |
-
|
| 227 |
-
|
| 228 |
-
`
|
| 229 |
-
|
| 230 |
-
|
| 231 |
-
|
| 232 |
-
|
| 233 |
-
|
| 234 |
-
使うのに、実際の割り当て要求には元の `gpu_size=None` をそのまま渡す**。
|
| 235 |
-
3. 結果、53.8GB のモデルが 48GB の `large` に転送されて worker が即死する。
|
| 236 |
-
4. `worker_init()` は `torch.move()` を**デコレート関数の実行前**に呼ぶため、
|
| 237 |
-
`wrappers.py` が `res is None` を受けて `"GPU task aborted"` を投げる。
|
| 238 |
-
|
| 239 |
-
このため **Python トレースバックが一切残らず**、引数を取らない自己診断関数まで
|
| 240 |
-
含めてあらゆる GPU 呼び出しが同じように落ちる。要求 duration を 212 秒まで
|
| 241 |
-
上げても変わらない (duration の問題ではない)。公式 `Qwen/Qwen-Image-Edit-2511`
|
| 242 |
-
Space が動くのは `spaces` 0.50.2 のままリビルドされていないから。
|
| 243 |
-
|
| 244 |
-
対策は `@spaces.GPU(..., size="xlarge")` の明示指定のみ。`spaces` を
|
| 245 |
-
`requirements.txt` でピンして回避することは**できない** —
|
| 246 |
-
HF Spaces がビルドコマンドで `spaces==0.51.1` を強制注入するため
|
| 247 |
-
`ResolutionImpossible` になる。
|
| 248 |
-
|
| 249 |
-
診断用に `gpu_selftest` / `gpu_pipe_selftest` を UI の「診断」に残してある。
|
| 250 |
-
GPU が取れているかを最小コストで確認できる。
|
| 251 |
-
|
| 252 |
-
### 依存について
|
| 253 |
-
|
| 254 |
-
- **torch は書かない。** ベースイメージのものを使う (現在 2.11.0+cu130)。
|
| 255 |
-
- **`spaces` と `gradio` も書かない。** ビルドコマンドで強制注入される。
|
| 256 |
-
- `kernels` は 0.15 以降 `get_kernel()` に `version=` / `revision=` が必須になり、
|
| 257 |
-
vendoring した FA3 processor の呼び出しが通らないため `kernels<0.15` に固定。
|
| 258 |
-
ただし現行 ZeroGPU には対応するカーネルビルドが無く
|
| 259 |
-
(`min() arg is an empty sequence`)、**FA3 は現状使えない**。フォールバックして
|
| 260 |
-
既定の attention で動作する。
|
| 261 |
-
|
| 262 |
-
> 角度 LoRA は AoTI コンパイル後に切り替えられないため、起動時に fuse して固定している
|
| 263 |
-
> (既定強度 0.9、`ANGLES_LORA_SCALE` で変更可)。
|
| 264 |
-
|
| 265 |
-
## キャプション生成 (WD Tagger v3 vs OppaiOracle)
|
| 266 |
-
|
| 267 |
-
**タグ付けは onnxruntime の CPU 実行**にしてあり、ZeroGPU のクォータを一切消費しない。
|
| 268 |
-
|
| 269 |
-
| | WD Tagger v3 | OppaiOracle V1.1 |
|
| 270 |
|---|---|---|
|
| 271 |
-
|
|
| 272 |
-
|
|
| 273 |
-
|
|
| 274 |
-
|
| 275 |
-
|
| 276 |
-
|
| 277 |
-
|
| 278 |
-
|
| 279 |
-
|
| 280 |
-
|
| 281 |
-
|
| 282 |
-
|
| 283 |
-
|
| 284 |
-
|
| 285 |
-
|
| 286 |
-
|
| 287 |
-
|
| 288 |
-
|
| 289 |
-
|
| 290 |
-
|
| 291 |
-
|
| 292 |
-
|
| 293 |
-
|
| 294 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 295 |
```
|
| 296 |
-
dataset/01_full_front.png
|
| 297 |
-
dataset/01_full_front.txt <- 主タガーのキャプション (kohya-ss 形式)
|
| 298 |
-
...
|
| 299 |
-
captions_alt/01_full_front.txt <- 比較用のもう一方のタガー
|
| 300 |
-
caption_comparison.md
|
| 301 |
-
```
|
| 302 |
-
|
| 303 |
-
`dataset/` をそのまま kohya-ss の学習フォルダに指定できる。
|
| 304 |
|
| 305 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 306 |
|
|
|
|
|
|
|
|
|
|
| 307 |
```
|
| 308 |
-
{トリガーワード}, {構図の確定タグ}, {タガーが推定したタグ}
|
| 309 |
-
```
|
| 310 |
-
|
| 311 |
-
除外タグ欄に髪色・目色などを入れておくと、その特徴をキャプションから外して
|
| 312 |
-
LoRA 側に焼き込める。背景を焼き付けたくない場合に備えて、`white background` /
|
| 313 |
-
`simple background` は確定タグとして**明示的に**入れてある (無名の前提にしない)。
|
| 314 |
-
|
| 315 |
-
## Krea 2 Turbo との比較
|
| 316 |
-
|
| 317 |
-
「Krea 2 turbo に置き換えるべきか」を検討した結果、**Qwen-Image-Edit-2511 を継続**する。
|
| 318 |
-
|
| 319 |
-
| 項目 | Qwen-Image-Edit-2511 | Krea 2 Turbo |
|
| 320 |
-
|---|---|---|
|
| 321 |
-
| タスク | **画像編集がネイティブ** (多画像入力可) | stock diffusers では **text-to-image 専用** |
|
| 322 |
-
| パラメータ | 20B MMDiT + Qwen2.5-VL-7B | 12B MMDiT + Qwen3-VL-4B |
|
| 323 |
-
| 重み (bf16) | 40.9GB + 16.6GB ≈ 57GB | ~24GB + ~8GB ≈ **32GB** |
|
| 324 |
-
| ステップ | 4 (Lightning LoRA), true_cfg 1.0 | 8 (TDM 蒸留), guidance 0.0 |
|
| 325 |
-
| diffusers | `QwenImageEditPlusPipeline` | `Krea2Pipeline` (0.39.0+, t2i のみ) |
|
| 326 |
-
| Hub | 非 gated / **Apache-2.0** | `krea/Krea-2-Turbo` は **gated** / Krea 2 Community License |
|
| 327 |
-
| 編集手段 | ネイティブ | 非公式 LoRA + ComfyUI 専用ノード、または非公式 diffusers 移植 |
|
| 328 |
-
| カメラ角度制御 | **専用 LoRA が存在 (96 カメラ位置)** | 同等物なし |
|
| 329 |
-
| 公開ホスト時の義務 | なし | **入出力セーフティ分類器の実装が必須** |
|
| 330 |
-
|
| 331 |
-
VRAM が軽いのは Krea 2 の明確な利点。しかし「参照画像 1 枚から同一キャラの多視点を派生させる」
|
| 332 |
-
という本 Space の中核機能が公式に存在せず、角度制御 LoRA のエコシステムも無い。
|
| 333 |
-
|
| 334 |
-
実測比較は別 Space [`Krea2-vs-Qwen-Edit-Bench`](./bench) で行う (同リポジトリの `bench/` を参照)。
|
| 335 |
|
| 336 |
-
|
|
|
|
|
|
|
|
|
|
| 337 |
|
| 338 |
-
|
| 339 |
-
|
| 340 |
-
|
| 341 |
|
| 342 |
-
##
|
| 343 |
|
| 344 |
-
|
| 345 |
-
|
| 346 |
-
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
+
title: Character View Sheet (Qwen Image 2.1 turbo)
|
| 3 |
emoji: 🎨
|
| 4 |
+
colorFrom: blue
|
| 5 |
+
colorTo: gray
|
| 6 |
sdk: gradio
|
| 7 |
sdk_version: 5.49.1
|
| 8 |
+
python_version: "3.12"
|
| 9 |
app_file: app.py
|
| 10 |
pinned: false
|
| 11 |
license: apache-2.0
|
| 12 |
+
short_description: ポーズ人形による11視点生成の速度・同一性・追従精度を評価する研究デモ
|
| 13 |
---
|
| 14 |
|
| 15 |
+
# Character View Sheet (Qwen Image 2.1 turbo)
|
| 16 |
+
|
| 17 |
+
参照キャラクター画像と、付属する11種類のポーズ人形を使い、各視点を1枚ずつ生成する
|
| 18 |
+
Hugging Face Gradio Space用の研究試作版です。**ローカル実機で11視点生成を検証済み**です。
|
| 19 |
+
公開Space: [Character View Sheet (Qwen Image 2.1 turbo)](https://huggingface.co/spaces/darask0/Qwen-Image-Edit-2511-Lora-Sheet)
|
| 20 |
+
|
| 21 |
+
**HF ZeroGPU largeでも、認証情報を送らないAPI接続から標準サイズ11視点の完走を確認しました。**
|
| 22 |
+
2026-10-12、GPU内処理68.0秒、割当・転送込み68.5秒、
|
| 23 |
+
ピーク割当33.01GiB。角度LoRAあり・人形あり・白背景全身の切り出しあり・Seed0です。
|
| 24 |
+
確認GPUは`NVIDIA RTX PRO 6000 Blackwell Server Edition MIG 2g.48gb`。110秒予約でPNG11枚を取得しました。
|
| 25 |
+
1例・1回の匿名API試験で、ブラウザ操作や他の入力・混雑時の完走を保証するものではありません。
|
| 26 |
+
上記は別の検証用Spaceで取得した計測です。この検証済みTurbo版で既存の2511 Spaceを置き換えました。
|
| 27 |
+
URLは従来のものを継続し、表示名・使用モデル・アプリ内容を更新しています。
|
| 28 |
+
|
| 29 |
+
RTX PRO 6000 Blackwell(96GB、PyTorchの割当を48GiBに制限)では、標準サイズ・速度優先設定で
|
| 30 |
+
11枚を推論36.1秒、PNG保存込み39.3秒、ピーク割当33.01GiBで生成しました。
|
| 31 |
+
これは全GPUの演算能力を使用した値です。ZeroGPU largeの半GPU性能、転送、待ち時間は再現していません。
|
| 32 |
+
高速設定は11枚を推論17.7秒・保存込み19.0秒で完走しました。
|
| 33 |
+
人物1例の評価で、構図や衣装の細部に誤りが残るため、学習用画像は選別してください。
|
| 34 |
+
|
| 35 |
+
同じ人物では、標準・速度優先+参照切り出し+2.1角度LoRA(強度0.8)が最も良い結果でした。
|
| 36 |
+
この条件は11枚を推論37.3秒・保存込み40.2秒、ピーク割当33.02GiBで完走しました。
|
| 37 |
+
短パン化と背中への胸模様の転写が解消し、顔・上半身の寄り構図も改善しましたが、
|
| 38 |
+
左右非対称の袖模様、背景色、細かな関節位置は一致しません。
|
| 39 |
+
|
| 40 |
+
用途は研究・評価です。未ログイン利用者も参加できる研究用デモとして、
|
| 41 |
+
生成速度、キャラクター同一性、ポーズ人形への追従精度を検証する想定です。
|
| 42 |
+
|
| 43 |
+
対象モデルは `Qwen/Qwen-Image-2.1-Turbo`。未ログイン利用者の120秒枠で11視点を
|
| 44 |
+
生成できるよう、最大110秒のGPU予約、低解像度設定、実行時間の記録を用意しています。
|
| 45 |
+
110秒は処理の上限であり、11枚の完成所要時間を測った値ではありません。
|
| 46 |
+
|
| 47 |
+
## 変更内容
|
| 48 |
+
|
| 49 |
+
- 元Spaceと同じ11視点を選択可能。
|
| 50 |
+
- キャプション生成、タガー、比較レポート、トリガーワード/除外タグ設定を削除。
|
| 51 |
+
- 出力ZIPは `dataset/NN_view.png` のみ。TXT、キャプション、ポーズ人形は混入しません。
|
| 52 |
+
- 全視点でユーザーの元画像を参照。生成画像を次の視点に回す中間アンカー生成はありません。
|
| 53 |
+
- 白背景の直立全身画像に限り、寄り4視点の参照切り出しを選べます(既定は無効)。
|
| 54 |
+
- 11枚のグレーのポーズ人形PNGを同梱。人形参照のオン・オフを比較可能。
|
| 55 |
+
- Turboの保存済み8ステップsigmaを使用。CFG=1、KV cache有効。
|
| 56 |
+
- GPUサイズは明示的に `large`。1ジョブずつ処理し、VAE tilingを有効化。
|
| 57 |
+
- 時間が不足しそうなら次の視点を開始せず、完成済みの画像を返します。
|
| 58 |
+
- モデル内のステップ境界でも期限を確認。通常の後続視点エラーでも完成画像を保持します。
|
| 59 |
+
ただしプロセス強制終了・GPU割当失敗・ステップ途中の長時間停止は救済できません��
|
| 60 |
+
|
| 61 |
+
## ポーズ人形
|
| 62 |
+
|
| 63 |
+

|
| 64 |
+
|
| 65 |
+
`pose_guides.py` が同じ立体モデルを異なるカメラから投影して作ります。
|
| 66 |
+
画像生成AIや外部の人形画像は使用していません。個別PNGには文字が入りません。
|
| 67 |
+
一覧だけに確認用ラベルがあります。
|
| 68 |
+
|
| 69 |
+
1. 全身の正面・左側面・右側面・背面
|
| 70 |
+
2. 腿上の正面・背面
|
| 71 |
+
3. 上半身正面・顔正面
|
| 72 |
+
4. 膝を抱えた座り姿の正面・背面
|
| 73 |
+
5. うつ伏せの後方俯瞰
|
| 74 |
+
|
| 75 |
+
条件画像は `[元のキャラ画像, その視点の人形画像]` の2枚です。
|
| 76 |
+
「白背景の直立全身画像」の切り出しを有効にすると、腿上・上半身・顔用に元画像から
|
| 77 |
+
それぞれ前景高さの72%・45%・20%を切り出します。縦横比を保ち、白い余白を付けます。
|
| 78 |
+
背景付き画像、座り姿、既に寄った画像には使わないでください。寄り構図は改善しましたが、
|
| 79 |
+
切断面を衣装の裾と解釈し長ズボンを短パンに変える例もあり、実験オプションです。
|
| 80 |
+
指示文でも「Image 1から外見、Image 2からポーズと構図」を区別します。
|
| 81 |
+
これは画像編集の参照機能であり、ControlNetや骨格座標による強制制御ではありません。
|
| 82 |
+
顔や衣装の保持、背面の補完、関節配置への追従は生成結果で確認する必要があります。
|
| 83 |
+
人形は標準体型のため、デフォルメ体型では余白や手足の配置を調整する余地があります。
|
| 84 |
+
|
| 85 |
+
再生成:
|
| 86 |
+
|
| 87 |
+
```bash
|
| 88 |
+
python pose_guides.py --regenerate
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 89 |
```
|
| 90 |
|
| 91 |
+
## HF Spaceでの検証手順
|
| 92 |
+
|
| 93 |
+
1. このディレクトリの内容をGradio Spaceのルートに置きます。
|
| 94 |
+
2. HardwareをZeroGPUに設定します。アプリの閲覧者にHFログインを要求する設定はありません。
|
| 95 |
+
3. 既定の `GPU_SIZE=large`、標準・速度優先、人形参照ありで起動します。公開Spaceは `ENABLE_ANGLES_LORA=1` で、検証済みの2.1角度LoRAを使用します。
|
| 96 |
+
4. 所有者の利用枠で、正面・側面・背面をまず比較し、続いて11視点を生成します。
|
| 97 |
+
5. 「実行時間の記録」からJSONを保存し、全11視点の完成、ピークVRAM、1枚ごとの時間を確認します。
|
| 98 |
+
6. 同じ参照画像・Seed・出力サイズで人形参照のオン/オフを比較します。
|
| 99 |
+
7. 未ログイン状態では、その日の残り利用枠がある状態で11視点を検証します。
|
| 100 |
+
|
| 101 |
+
HF上で依存インストール・起動・ZeroGPU推論・画像ZIP取得を確認済みです。
|
| 102 |
+
HFのビルドが供給したTorch2.13.0を維持し、Torchvision0.28.0へ解決されました。
|
| 103 |
+
Spaces0.51.3、Gradio5.49.1、Python3.12.12、Transformers5.19.0、PEFT0.21.2、Accelerate1.15.0で動作しました。
|
| 104 |
+
`requirements.txt` はQwen公式案内に沿い、Turboを扱える上流Diffusersコミットを固定しました。
|
| 105 |
+
ZeroGPUが供給するtorch/spaces/Gradioはrequirementsで重ねて固定しません。
|
| 106 |
+
|
| 107 |
+
旧 `tagging.py` / `optimization.py` / `qwenimage/` / `bench/` は削除しました。
|
| 108 |
+
旧requirementsを追加せず、本版のものを使用します。
|
| 109 |
+
|
| 110 |
+
## 解像度と時間枠
|
| 111 |
+
|
| 112 |
+
| 設定 | 縦長 | 正方形 | 横長 | 条件画像の面積設定 |
|
| 113 |
+
|---|---|---|---|---|
|
| 114 |
+
| 高速 | 512×768 | 640×640 | 768×512 | `output_resolution=640` |
|
| 115 |
+
| 標準・速度優先(既定) | 832×1216 | 1024×1024 | 1216×832 | `output_resolution=640` |
|
| 116 |
+
| 標準・細部優先 | 832×1216 | 1024×1024 | 1216×832 | `output_resolution=1024` |
|
| 117 |
+
|
| 118 |
+
条件画像をPILで縮小するだけではモデル内部で拡大されるため、`output_resolution`も明示しています。
|
| 119 |
+
高速モードの画像は標準より小さく、学習用細部の情報量も減ります。
|
| 120 |
+
標準・速度優先は出力サイズを保ち、参照画像の処理面積を減らします。
|
| 121 |
+
細かい模様の再現は別途比較が必要です。元2511版との同一条件の速度比較は未実施です。
|
| 122 |
+
|
| 123 |
+
GPU時間枠は `min(MAX_GPU_SECONDS, max(45, 15 + 10 × 視点数))` 秒。
|
| 124 |
+
この式は測定結果からの推定ではなく、試作の予約上限です。
|
| 125 |
+
初期転送に15秒、生成終了処理に6秒の余裕を取り、残り時間で生成します。
|
| 126 |
+
11視点は110秒予約、`large`では120秒の匿名日次枠内に予約できますが、他のSpaceでの利用や
|
| 127 |
+
残り枠、混雑、実行速度によって利用・完成を保証するものではありません。
|
| 128 |
+
|
| 129 |
+
公式の現行仕様では `large`は48GB・1倍消費、`xlarge`は96GB・2倍消費です。
|
| 130 |
+
`xlarge`へ変更すると11視点の予約が220秒相当になり、未ログイン枠を超えます。
|
| 131 |
+
Turboのsafetensorsファイル合計は約32.44GBで、演算時のVRAMはこれより増えます。
|
| 132 |
+
ローカル実測で標準解像度・2参照画像のピーク割当は36.10GiB、標準・速度優先では33.01GiBでした。
|
| 133 |
+
HF largeでも標準・速度優先のピーク割当は33.01GiBでした。
|
| 134 |
+
|
| 135 |
+
| Space Variable | 既定値 | 意味 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 136 |
|---|---|---|
|
| 137 |
+
| `GPU_SIZE` | `large` | `large` / `xlarge`。明示指定 |
|
| 138 |
+
| `MAX_GPU_SECONDS` | `110` | 45〜110。実行時間枠の上限 |
|
| 139 |
+
| `ENABLE_ANGLES_LORA` | `0` | `1`で2.1用Multiple-Angles v2を追加する比較実験 |
|
| 140 |
+
|
| 141 |
+
## 角度LoRA
|
| 142 |
+
|
| 143 |
+
旧2511用のLightning/Multiple-Anglesは使用しません。
|
| 144 |
+
2.1は異なるモデル構造です。必要なら `akhaliq/Qwen-Image-2.1-Multiple-Angles-LoRA` の
|
| 145 |
+
v2、強度0.8を起動時に適用できます。`<mva>`語彙を使います。
|
| 146 |
+
作者の学習実装とDiffusersではMLPの層名と構造が異なるため、`angles_adapter.py`が
|
| 147 |
+
結合されたgate/upのLoRAを分割変換し、全224モジュール・448テンソルの読込を確認します。
|
| 148 |
+
未対応層を黙って無視しません。変換後のモデルで11視点の実GPU推論を完走しました。
|
| 149 |
+
本検証の人物1例では衣装と寄り構図が改善しました。品質比較用オプションで、既定では無効です。
|
| 150 |
+
この比較を再現するには `ENABLE_ANGLES_LORA=1`、標準・速度優先、白背景全身用の切り出しを選びます。
|
| 151 |
+
|
| 152 |
+
## 利用条件
|
| 153 |
+
|
| 154 |
+
アプリのコードと手続き的に作成した人形はApache-2.0です。
|
| 155 |
+
**モデル重みのライセンスは別**で、TurboはQwen Research Licenseです。
|
| 156 |
+
公開本文では非商用を研究・評価目的と定義し、商用利用には別許諾を求めています。
|
| 157 |
+
無料公開であることだけから利用可能とは判断できません。
|
| 158 |
+
出力を用いて学習・改善したAIモデルを配布・提供する場合、関連文書への
|
| 159 |
+
`Built with Qwen` または `Improved using Qwen` 表示条件があります。
|
| 160 |
+
本試作版は、上記の研究・評価用途を前提とします。
|
| 161 |
+
|
| 162 |
+
## ローカルで検証した範囲
|
| 163 |
+
|
| 164 |
+
PillowとPython標準ライブラリで、CPU側のデータ処理テストを実行できます。
|
| 165 |
+
モデル重みをダウンロードすることはありません。
|
| 166 |
+
|
| 167 |
+
```bash
|
| 168 |
+
python -m unittest discover -s tests -v
|
| 169 |
```
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 170 |
|
| 171 |
+
画像だけのZIP、11視点の選択、各視点の参照画像、途中失敗時の保存、時間枠の中断、
|
| 172 |
+
入力画像の透過処理・縮小、選択順に依存しないSeedを確認します。
|
| 173 |
+
人形画像は目視および寸法・RGBモードを確認しました。
|
| 174 |
+
CPUテストは生成品質を評価しません。GPUベンチマークは次のコマンドで別途実行できます。
|
| 175 |
+
モデルのダウンロードには約33GB、実行にはCUDA環境が必要です。
|
| 176 |
|
| 177 |
+
```bash
|
| 178 |
+
python benchmark_local.py --image character.png --output-dir results \
|
| 179 |
+
--resolution balanced --pose-guides on --reference-crop on --memory-limit-gib 48
|
| 180 |
```
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 181 |
|
| 182 |
+
`--reference-crop on` は白背景・直立全身の場合だけ指定します。
|
| 183 |
+
`--resolution fast/standard/balanced`、`--angles-lora on/off`、`--repeat 2`で比較できます。
|
| 184 |
+
`--create-sample`は検証用の成人キャラクターを先に生成し、その時間を11枚の計測から分離します。
|
| 185 |
+
`--image`と`--create-sample`を省略すると人形の速度試験となり、人物同一性の評価には使えません。
|
| 186 |
|
| 187 |
+
計測JSONは各視点の同期済み推論時間、PNG保存込み時間、ロード時間、ピークVRAM、
|
| 188 |
+
モデルrevision、プロンプト、Seedを記録します。48GiB制限はPyTorch allocatorだけを制限し、
|
| 189 |
+
半GPUの演算性能やZeroGPU環境を再現しません。
|
| 190 |
|
| 191 |
+
## 一次資料(2026-10-12確認)
|
| 192 |
|
| 193 |
+
- [置き換え前の11視点Spaceのソース](https://huggingface.co/spaces/darask0/Qwen-Image-Edit-2511-Lora-Sheet/tree/0e9ee21fcd738c71b4ccd0606e854b79521fbbd3)
|
| 194 |
+
- [Turbo公式モデルカード](https://huggingface.co/Qwen/Qwen-Image-2.1-Turbo)
|
| 195 |
+
- [使用するDiffusers実装](https://github.com/huggingface/diffusers/blob/85c9fa4caee33d1c5b473395784471d2d7957c1b/src/diffusers/pipelines/qwenimage21/pipeline_qwenimage21.py)
|
| 196 |
+
- [2.1用角度LoRAの作者資料](https://huggingface.co/akhaliq/Qwen-Image-2.1-Multiple-Angles-LoRA)
|
| 197 |
+
- [HF ZeroGPU仕様・利用枠](https://huggingface.co/docs/hub/en/spaces-zerogpu)
|
| 198 |
+
- [Turboライセンス](https://huggingface.co/Qwen/Qwen-Image-2.1-Turbo/blob/main/LICENSE)
|
angles_adapter.py
ADDED
|
@@ -0,0 +1,128 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Lossless ai-toolkit Qwen Image 2.1 fused-MLP LoRA conversion.
|
| 2 |
+
|
| 3 |
+
ai-toolkit's Qwen Image 2.1 transformer stores ``gate_up = [gate; up]``;
|
| 4 |
+
Diffusers stores ``gate_layer`` and ``proj`` separately. For a fused update
|
| 5 |
+
``B @ A``, duplicate A and split B's output rows. Rank and scale do not change.
|
| 6 |
+
|
| 7 |
+
Sources:
|
| 8 |
+
https://github.com/ostris/ai-toolkit/blob/main/extensions_built_in/diffusion_models/qwen_image_2/src/transformer.py
|
| 9 |
+
https://github.com/huggingface/diffusers/blob/85c9fa4caee33d1c5b473395784471d2d7957c1b/src/diffusers/models/transformers/transformer_qwenimage21.py
|
| 10 |
+
|
| 11 |
+
This deliberately rejects unknown tensors or unmatched modules instead of
|
| 12 |
+
silently loading only the attention part of a checkpoint.
|
| 13 |
+
"""
|
| 14 |
+
|
| 15 |
+
from __future__ import annotations
|
| 16 |
+
|
| 17 |
+
import math
|
| 18 |
+
from collections.abc import Mapping
|
| 19 |
+
from typing import Any
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
def convert_angles_state_dict(state_dict: Mapping[str, Any], transformer: Any) -> dict[str, Any]:
|
| 23 |
+
"""Convert A/B-only weights and validate every target against the model.
|
| 24 |
+
|
| 25 |
+
The published v2 checkpoint uses PEFT A/B weights without alpha tensors.
|
| 26 |
+
Its rank/alpha are both 64, hence the effective update is B @ A. An alpha
|
| 27 |
+
tensor is rejected here so a differently scaled format cannot be mistaken
|
| 28 |
+
for this one. No adapter tensors are discarded or rescaled.
|
| 29 |
+
"""
|
| 30 |
+
pairs: dict[str, dict[str, Any]] = {}
|
| 31 |
+
for key, tensor in state_dict.items():
|
| 32 |
+
name = key
|
| 33 |
+
for prefix in ("diffusion_model.", "transformer."):
|
| 34 |
+
if name.startswith(prefix):
|
| 35 |
+
name = name[len(prefix):]
|
| 36 |
+
break
|
| 37 |
+
suffix = next((s for s in (".lora_A.weight", ".lora_B.weight") if name.endswith(s)), None)
|
| 38 |
+
if suffix is None or tensor.ndim != 2:
|
| 39 |
+
raise ValueError(f"Unsupported LoRA tensor: {key}")
|
| 40 |
+
module_name = name[:-len(suffix)]
|
| 41 |
+
kind = suffix[6]
|
| 42 |
+
pair = pairs.setdefault(module_name, {})
|
| 43 |
+
if kind in pair:
|
| 44 |
+
raise ValueError(f"Duplicate LoRA tensor: {key}")
|
| 45 |
+
pair[kind] = tensor
|
| 46 |
+
if not pairs:
|
| 47 |
+
raise ValueError("The LoRA checkpoint has no adapter tensors.")
|
| 48 |
+
|
| 49 |
+
converted: dict[str, Any] = {}
|
| 50 |
+
|
| 51 |
+
def add_pair(module_name: str, a: Any, b: Any) -> None:
|
| 52 |
+
try:
|
| 53 |
+
module = transformer.get_submodule(module_name)
|
| 54 |
+
# Also works when another adapter has already wrapped this Linear.
|
| 55 |
+
base = module.get_base_layer() if hasattr(module, "get_base_layer") else module
|
| 56 |
+
expected = tuple(base.weight.shape)
|
| 57 |
+
except (AttributeError, KeyError) as exc:
|
| 58 |
+
raise ValueError(f"LoRA targets a missing model module: {module_name}") from exc
|
| 59 |
+
if len(expected) != 2 or tuple((b.shape[0], a.shape[1])) != expected or b.shape[1] != a.shape[0]:
|
| 60 |
+
raise ValueError(f"LoRA shape mismatch for {module_name}: A={tuple(a.shape)}, B={tuple(b.shape)}, base={expected}")
|
| 61 |
+
for kind, tensor in (("A", a), ("B", b)):
|
| 62 |
+
key = f"transformer.{module_name}.lora_{kind}.weight"
|
| 63 |
+
if key in converted:
|
| 64 |
+
raise ValueError(f"Overlapping fused and split LoRA tensors: {key}")
|
| 65 |
+
converted[key] = tensor
|
| 66 |
+
|
| 67 |
+
for name, pair in pairs.items():
|
| 68 |
+
if set(pair) != {"A", "B"}:
|
| 69 |
+
raise ValueError(f"Incomplete A/B pair: {name}")
|
| 70 |
+
a, b = pair["A"], pair["B"]
|
| 71 |
+
if name.endswith(".img_mlp.gate_up"):
|
| 72 |
+
if b.shape[0] % 2:
|
| 73 |
+
raise ValueError(f"Fused gate/up output width must be even: {name}")
|
| 74 |
+
halfway = b.shape[0] // 2
|
| 75 |
+
prefix = name[:-len("gate_up")]
|
| 76 |
+
add_pair(prefix + "gate_layer", a, b[:halfway].contiguous())
|
| 77 |
+
add_pair(prefix + "proj", a, b[halfway:].contiguous())
|
| 78 |
+
else:
|
| 79 |
+
add_pair(name, a, b)
|
| 80 |
+
return converted
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
def load_angles_adapter(pipe: Any, checkpoint_path: str, *, adapter_name: str = "angles", strength: float = 1.0) -> dict[str, Any]:
|
| 84 |
+
"""Load the complete adapter and verify that every A/B pair was installed.
|
| 85 |
+
|
| 86 |
+
Use a fresh adapter name. Conversion and shape checks happen before model
|
| 87 |
+
mutation. If installation validation fails, remove this adapter and raise.
|
| 88 |
+
``strength`` is the sole additional multiplier; rank is never halved when
|
| 89 |
+
splitting gate/up and no sqrt-rank scaling is introduced.
|
| 90 |
+
"""
|
| 91 |
+
from safetensors.torch import load_file
|
| 92 |
+
|
| 93 |
+
if not math.isfinite(strength) or strength < 0:
|
| 94 |
+
raise ValueError("Adapter strength must be finite and nonnegative.")
|
| 95 |
+
if adapter_name in getattr(pipe.transformer, "peft_config", {}):
|
| 96 |
+
raise ValueError(f"Adapter already exists: {adapter_name}")
|
| 97 |
+
source = load_file(str(checkpoint_path), device="cpu")
|
| 98 |
+
weights = convert_angles_state_dict(source, pipe.transformer)
|
| 99 |
+
expected = {
|
| 100 |
+
key.removeprefix("transformer.").removesuffix(".lora_A.weight"): tuple(tensor.shape)
|
| 101 |
+
for key, tensor in weights.items() if key.endswith(".lora_A.weight")
|
| 102 |
+
}
|
| 103 |
+
fused_count = sum(key.endswith(".img_mlp.gate_up.lora_A.weight") for key in source)
|
| 104 |
+
try:
|
| 105 |
+
pipe.load_lora_weights(weights, adapter_name=adapter_name)
|
| 106 |
+
for name, a_shape in expected.items():
|
| 107 |
+
module = pipe.transformer.get_submodule(name)
|
| 108 |
+
for kind in ("A", "B"):
|
| 109 |
+
bank = getattr(module, f"lora_{kind}", {})
|
| 110 |
+
wanted = weights[f"transformer.{name}.lora_{kind}.weight"]
|
| 111 |
+
if adapter_name not in bank or tuple(bank[adapter_name].weight.shape) != tuple(wanted.shape):
|
| 112 |
+
raise RuntimeError(f"Adapter weight was not installed completely: {name}.lora_{kind}")
|
| 113 |
+
# PEFT must use alpha/rank = 1 before the requested user strength.
|
| 114 |
+
if module.r[adapter_name] != a_shape[0] or not math.isclose(float(module.scaling[adapter_name]), 1.0):
|
| 115 |
+
raise RuntimeError(f"Unexpected rank or alpha scaling: {name}")
|
| 116 |
+
pipe.set_adapters([adapter_name], adapter_weights=[strength])
|
| 117 |
+
except Exception:
|
| 118 |
+
if adapter_name in getattr(pipe.transformer, "peft_config", {}):
|
| 119 |
+
pipe.delete_adapters(adapter_name)
|
| 120 |
+
raise
|
| 121 |
+
return {
|
| 122 |
+
"input_tensors": len(source),
|
| 123 |
+
"loaded_tensors": len(weights),
|
| 124 |
+
"fused_mlp_blocks": fused_count,
|
| 125 |
+
"loaded_modules": len(expected),
|
| 126 |
+
"ranks": sorted({shape[0] for shape in expected.values()}),
|
| 127 |
+
"strength": strength,
|
| 128 |
+
}
|
app.py
CHANGED
|
@@ -1,697 +1,127 @@
|
|
| 1 |
-
"""
|
| 2 |
-
|
| 3 |
-
設計の要点:
|
| 4 |
-
|
| 5 |
-
1. カメラは fal/Qwen-Image-Edit-2511-Multiple-Angles-LoRA の構造化トリガで指定する。
|
| 6 |
-
散文で "Move the camera to a back-facing position..." と書くより再現性が高い。
|
| 7 |
-
|
| 8 |
-
2. `@spaces.GPU` には **必ず size を明示する**。自動選択には spaces 0.51.1 の
|
| 9 |
-
バグがあり、48GB の large にモデルが載らず GPU タスクが黙って落ちる (下記 GPU_SIZE)。
|
| 10 |
-
|
| 11 |
-
3. ZeroGPU のクォータは **要求した duration ぶんそのまま** 消費される
|
| 12 |
-
(実行時間ではない)。さらに xlarge はその 2 倍が引かれる。そのため
|
| 13 |
-
- duration を実際の生成枚数から見積もる
|
| 14 |
-
- 選択内容に応じた推定消費秒数を UI に常時出す
|
| 15 |
-
- GPU 取得の固定費を何度も払わないよう既定では分割しない
|
| 16 |
-
という 3 点で無料枠 (300 秒/日) に収める。
|
| 17 |
-
|
| 18 |
-
4. タグ付けは onnxruntime の CPU 実行にして、クォータを一切消費しない。
|
| 19 |
-
"""
|
| 20 |
-
|
| 21 |
-
import io
|
| 22 |
-
import os
|
| 23 |
import random
|
| 24 |
import tempfile
|
| 25 |
-
import
|
| 26 |
-
from
|
| 27 |
|
| 28 |
import gradio as gr
|
| 29 |
-
import numpy as np
|
| 30 |
-
import spaces
|
| 31 |
-
import torch
|
| 32 |
-
from diffusers import QwenImageEditPlusPipeline
|
| 33 |
-
from PIL import Image
|
| 34 |
-
|
| 35 |
-
import tagging
|
| 36 |
-
import views as V
|
| 37 |
-
from framing import crop_framing
|
| 38 |
-
from optimization import apply_fa3_, optimize_pipeline_
|
| 39 |
-
|
| 40 |
-
# --- モデル読み込み ---------------------------------------------------------
|
| 41 |
-
|
| 42 |
-
DTYPE = torch.bfloat16
|
| 43 |
-
DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
|
| 44 |
-
|
| 45 |
-
BASE_MODEL = "Qwen/Qwen-Image-Edit-2511"
|
| 46 |
-
LIGHTNING_REPO = "lightx2v/Qwen-Image-Edit-2511-Lightning"
|
| 47 |
-
LIGHTNING_WEIGHT = "Qwen-Image-Edit-2511-Lightning-4steps-V1.0-bf16.safetensors"
|
| 48 |
-
ANGLES_REPO = "fal/Qwen-Image-Edit-2511-Multiple-Angles-LoRA"
|
| 49 |
-
ANGLES_WEIGHT = "qwen-image-edit-2511-multiple-angles-lora.safetensors"
|
| 50 |
-
|
| 51 |
-
#: 角度 LoRA の推奨強度は 0.8-1.0。AoTI コンパイル後は実行時に切り替えられないため
|
| 52 |
-
#: 起動時に fuse して固定する。`<sks>` トリガの無いプロンプト (ポーズ生成) への
|
| 53 |
-
#: 副作用が出る場合はこの値を下げる。
|
| 54 |
-
ANGLES_LORA_SCALE = float(os.environ.get("ANGLES_LORA_SCALE", "0.9"))
|
| 55 |
-
|
| 56 |
-
# LoRA は CPU 上で fuse してから GPU に載せる。
|
| 57 |
-
# (fp8 量子化を CPU 側でやるのは不可。torchao の Float8Tensor が ZeroGPU の
|
| 58 |
-
# エミュレーション層が使う `aten.empty_like` を実装しておらず、起動時に落ちる。)
|
| 59 |
-
pipe = QwenImageEditPlusPipeline.from_pretrained(BASE_MODEL, torch_dtype=DTYPE)
|
| 60 |
-
|
| 61 |
-
pipe.load_lora_weights(LIGHTNING_REPO, weight_name=LIGHTNING_WEIGHT, adapter_name="fast")
|
| 62 |
-
pipe.load_lora_weights(ANGLES_REPO, weight_name=ANGLES_WEIGHT, adapter_name="angles")
|
| 63 |
-
pipe.set_adapters(["fast", "angles"], adapter_weights=[1.0, ANGLES_LORA_SCALE])
|
| 64 |
-
pipe.fuse_lora(adapter_names=["fast", "angles"], lora_scale=1.0)
|
| 65 |
-
pipe.unload_lora_weights()
|
| 66 |
-
|
| 67 |
-
pipe.to(DEVICE)
|
| 68 |
-
|
| 69 |
-
apply_fa3_(pipe)
|
| 70 |
-
|
| 71 |
-
# --- AoTI + fp8 は既定で無効 (ENABLE_AOTI=1 で有効化) -----------------------
|
| 72 |
-
#
|
| 73 |
-
# 起動時の AoTI コンパイルは、以前 NVML アサートで失敗していた。原因は後述の
|
| 74 |
-
# GPU_SIZE のバグ (48GB の large にモデルが載らない) と同一で、`optimize_pipeline_`
|
| 75 |
-
# 内の `@spaces.GPU` に size を渡していなかったため。現在は理屈のうえでは
|
| 76 |
-
# size を指定すれば通るはずだが未検証。
|
| 77 |
-
#
|
| 78 |
-
# また現行 ZeroGPU では FA3 のカーネルビルドが無く (kernels が
|
| 79 |
-
# "min() arg is an empty sequence" で失敗)、AoTI 込みの高速化は未確認。
|
| 80 |
-
# 既定は素の bf16。試す場合は Space の Variables に ENABLE_AOTI=1 を設定する。
|
| 81 |
-
if os.environ.get("ENABLE_AOTI", "").strip() in ("1", "true", "True"):
|
| 82 |
-
# AoTI のグラフ捕捉は **実際の推論と同じ経路** で行う必要がある。
|
| 83 |
-
# true_cfg_scale を既定 (4.0) のままにすると classifier-free guidance が有効になり、
|
| 84 |
-
# transformer が cond/uncond の 2 バッチで呼ばれる。バッチ次元は動的次元に
|
| 85 |
-
# 含めていないため、推論時 (1 バッチ) と形が合わずコンパイル結果が使えなくなる。
|
| 86 |
-
optimize_pipeline_(
|
| 87 |
-
pipe,
|
| 88 |
-
image=[Image.new("RGB", (832, 1216))],
|
| 89 |
-
prompt="warmup",
|
| 90 |
-
negative_prompt=" ",
|
| 91 |
-
height=1216,
|
| 92 |
-
width=832,
|
| 93 |
-
num_inference_steps=1,
|
| 94 |
-
true_cfg_scale=1.0,
|
| 95 |
-
)
|
| 96 |
-
else:
|
| 97 |
-
print("[app] AoTI/fp8 は無効 (ENABLE_AOTI=1 で有効化)")
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
MAX_SEED = np.iinfo(np.int32).max
|
| 101 |
-
|
| 102 |
-
# --- ZeroGPU の duration 見積り ---------------------------------------------
|
| 103 |
-
#
|
| 104 |
-
# ZeroGPU 実測値 (xlarge / MIG 4g.96gb / bf16, 2026-08):
|
| 105 |
-
# GPU 取得 + モデル転送 : 約 9 秒 (引数なしの selftest が 8.9 秒で完了)
|
| 106 |
-
# 1 枚目 (ウォームアップ込): 4.8 秒
|
| 107 |
-
# 2 枚目以降 : 2.9 秒/枚 (832x1216, 4 step)
|
| 108 |
-
# 4 枚のチャンク合計 : 13.5 秒
|
| 109 |
-
CALL_OVERHEAD_SEC = int(os.environ.get("CALL_OVERHEAD_SEC", "12"))
|
| 110 |
-
PER_VIEW_SEC = int(os.environ.get("PER_VIEW_SEC", "5"))
|
| 111 |
-
|
| 112 |
-
# 分割は既定で無効 (11 視点なら 1 回の呼び出しに収める)。
|
| 113 |
-
# xlarge はクォータを 2 倍消費するうえ、GPU 取得の固定費が呼び出しごとに
|
| 114 |
-
# かかるため、分割するほど総消費が増える。分割の利点 (残クォータが少なくても
|
| 115 |
-
# 途中まで進める) より、総量を抑えるほうが無料枠では効く。
|
| 116 |
-
# 視点をさらに増やして 1 回では長くなりすぎる場合はここを下げる。
|
| 117 |
-
CHUNK_SIZE = int(os.environ.get("CHUNK_SIZE", "12"))
|
| 118 |
-
|
| 119 |
-
FREE_QUOTA_SEC = 300 # 無料会員 (ログイン済み)
|
| 120 |
-
ANON_QUOTA_SEC = 120 # 未認証
|
| 121 |
-
|
| 122 |
-
# --- GPU サイズは明示指定が必須 ---------------------------------------------
|
| 123 |
-
#
|
| 124 |
-
# spaces 0.51.1 のバグ回避。ZeroGPU は起動時に登録テンソル量を測り、
|
| 125 |
-
# Blackwell の閾値 45097156608 (42.0GiB, zero/configs.json) を超えると
|
| 126 |
-
# zero/__init__.py の startup() で _default_gpu_size='xlarge' を立てる。
|
| 127 |
-
# ところが zero/client.py の schedule() は、その既定値を duration の計算には
|
| 128 |
-
# 使うのに、実際の割り当て要求には元の gpu_size=None をそのまま渡してしまう。
|
| 129 |
-
# 結果、本モデル (57.7GB) が 48GB の `large` に転送されて worker が即死し、
|
| 130 |
-
# wrappers.py が res=None を受けて "GPU task aborted" を投げる
|
| 131 |
-
# (デコレート関数に入る前なので Python トレースバックは残らない)。
|
| 132 |
-
#
|
| 133 |
-
# したがって size は自動選択に任せず、必ず明示的に渡すこと。
|
| 134 |
-
# xlarge はクォータを 2 倍消費する。モデルを 42GiB 未満に縮められたら
|
| 135 |
-
# 環境変数 GPU_SIZE=large に戻せる。
|
| 136 |
-
GPU_SIZE = os.environ.get("GPU_SIZE", "xlarge").strip() or "xlarge"
|
| 137 |
-
#: xlarge は要求 duration が内部で 2 倍されてクォータから引かれる
|
| 138 |
-
QUOTA_MULTIPLIER = 2 if GPU_SIZE == "xlarge" else 1
|
| 139 |
-
|
| 140 |
-
|
| 141 |
-
def _chunks(items: List, size: int) -> List[List]:
|
| 142 |
-
return [items[i : i + size] for i in range(0, len(items), size)]
|
| 143 |
-
|
| 144 |
-
|
| 145 |
-
def _chunk_duration(payload, *args, **kwargs) -> int:
|
| 146 |
-
"""@spaces.GPU の動的 duration。実際の生成コストぶんだけを要求する。
|
| 147 |
-
|
| 148 |
-
寄り視点を「クロップ + 全身」の 2 枚で条件付けすると条件系列が倍になり、
|
| 149 |
-
実測で 4.6 秒 -> 8.2 秒になる。その分は units に反映されている。
|
| 150 |
-
"""
|
| 151 |
-
units = sum(item.get("units", 1.0) for item in payload) or 1.0
|
| 152 |
-
return int(CALL_OVERHEAD_SEC + PER_VIEW_SEC * units)
|
| 153 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 154 |
|
| 155 |
-
|
| 156 |
-
selected_keys: List[str], two_stage_prone: bool = False, hq_framing: bool = False
|
| 157 |
-
) -> Tuple[int, int, int]:
|
| 158 |
-
"""(要求秒数の合計, 生成枚数, チャンク数) を返す。"""
|
| 159 |
-
plan = V.build_plan(selected_keys, two_stage_prone)
|
| 160 |
-
if not plan:
|
| 161 |
-
return 0, 0, 0
|
| 162 |
-
chunks = _chunks(plan, CHUNK_SIZE)
|
| 163 |
-
total = sum(_chunk_duration([_build_payload(s, "", hq_framing) for s in c]) for c in chunks)
|
| 164 |
-
return total, len(plan), len(chunks)
|
| 165 |
|
| 166 |
|
| 167 |
-
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
|
| 171 |
-
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
import time as _time
|
| 178 |
-
|
| 179 |
-
t_enter = _time.perf_counter()
|
| 180 |
-
print(f"[gpu] chunk start: {len(payload)} 枚 / 要求 {_chunk_duration(payload)}秒", flush=True)
|
| 181 |
-
|
| 182 |
-
produced: Dict[str, Image.Image] = {}
|
| 183 |
-
pool = dict(sources)
|
| 184 |
-
|
| 185 |
-
for item in payload:
|
| 186 |
-
src = pool.get(item["source"])
|
| 187 |
-
if src is None:
|
| 188 |
-
# GPU 子プロセス側なので gr.Error ではなく素の例外を投げる
|
| 189 |
-
raise RuntimeError(f"条件画像 {item['source']} が見つかりません")
|
| 190 |
-
|
| 191 |
-
# 寄り視点は、条件画像をあらかじめ目的の構図に切り出しておく。
|
| 192 |
-
# プロンプトだけでは Qwen-Image-Edit が入力のフレーミングを保とうとして
|
| 193 |
-
# 寄りが効かない (特にカウボーイショット) ことが実測で分かっている。
|
| 194 |
-
if item.get("crop"):
|
| 195 |
-
cropped = crop_framing(src, item["crop"], item["width"], item["height"])
|
| 196 |
-
cond = [cropped, src] if item.get("hq") else [cropped]
|
| 197 |
-
else:
|
| 198 |
-
cond = [src]
|
| 199 |
-
|
| 200 |
-
t0 = _time.perf_counter()
|
| 201 |
-
generator = torch.Generator(device=DEVICE).manual_seed(int(seed))
|
| 202 |
-
image = pipe(
|
| 203 |
-
image=cond,
|
| 204 |
-
prompt=item["prompt"],
|
| 205 |
-
negative_prompt=" ",
|
| 206 |
-
height=item["height"],
|
| 207 |
-
width=item["width"],
|
| 208 |
-
num_inference_steps=steps,
|
| 209 |
-
generator=generator,
|
| 210 |
-
true_cfg_scale=cfg,
|
| 211 |
-
num_images_per_prompt=1,
|
| 212 |
-
).images[0]
|
| 213 |
-
produced[item["key"]] = image
|
| 214 |
-
pool[item["key"]] = image
|
| 215 |
-
# アンカー生成がそのまま視点の出力を兼ねている場合、同じチャンク内の
|
| 216 |
-
# 後続ステップがその視点 key を条件画像として参照することがある
|
| 217 |
-
# (例: cowboy_front は full_front を切り出す)。ここで別名を張っておかないと
|
| 218 |
-
# 単一チャンク実行時に条件画像が見つからない。
|
| 219 |
-
if item.get("alias"):
|
| 220 |
-
pool[item["alias"]] = image
|
| 221 |
-
print(
|
| 222 |
-
f"[gpu] {item['key']}: {_time.perf_counter() - t0:.1f}秒 "
|
| 223 |
-
f"({item['width']}x{item['height']}, cond={len(cond)})",
|
| 224 |
-
flush=True,
|
| 225 |
-
)
|
| 226 |
-
|
| 227 |
-
# 最初の 1 枚までの時間には、ZeroGPU がモデル (57.7GB) を GPU へ転送する
|
| 228 |
-
# コストが含まれる。チャンクごとに毎回発生するため、duration 見積りの
|
| 229 |
-
# 固定費 (CALL_OVERHEAD_SEC) はこれを吸収できる値でなければならない。
|
| 230 |
-
print(f"[gpu] chunk done: {_time.perf_counter() - t_enter:.1f}秒", flush=True)
|
| 231 |
-
return produced
|
| 232 |
-
|
| 233 |
-
|
| 234 |
-
# --- 診断用 -----------------------------------------------------------------
|
| 235 |
-
# "GPU task aborted" が本体コードに到達する前に起きるため、どの段階で壊れているかを
|
| 236 |
-
# 切り分けるための最小テスト。UI の「診断」から実行できる。
|
| 237 |
-
|
| 238 |
-
|
| 239 |
-
@spaces.GPU(duration=60, size=GPU_SIZE)
|
| 240 |
-
def gpu_selftest() -> str:
|
| 241 |
-
"""GPU が取得できるか (= 57.7GB のモデル転送が通るか) だけを見る。"""
|
| 242 |
-
lines = [
|
| 243 |
-
f"torch={torch.__version__}",
|
| 244 |
-
f"cuda_available={torch.cuda.is_available()}",
|
| 245 |
-
]
|
| 246 |
-
if torch.cuda.is_available():
|
| 247 |
-
free, total = torch.cuda.mem_get_info()
|
| 248 |
-
lines += [
|
| 249 |
-
f"device={torch.cuda.get_device_name(0)}",
|
| 250 |
-
f"total={total / 1024**3:.1f}GB",
|
| 251 |
-
f"free={free / 1024**3:.1f}GB",
|
| 252 |
-
f"allocated={torch.cuda.memory_allocated() / 1024**3:.1f}GB",
|
| 253 |
-
]
|
| 254 |
-
x = torch.randn(64, 64, device="cuda", dtype=torch.bfloat16)
|
| 255 |
-
lines.append(f"matmul_ok={bool(torch.isfinite((x @ x).sum()))}")
|
| 256 |
-
return " | ".join(lines)
|
| 257 |
-
|
| 258 |
-
|
| 259 |
-
@spaces.GPU(duration=120, size=GPU_SIZE)
|
| 260 |
-
def gpu_pipe_selftest() -> str:
|
| 261 |
-
"""単純な引数だけで pipe() を 1 回呼ぶ。本体との差は引数の型と呼び出し元だけ。"""
|
| 262 |
-
t0 = __import__("time").perf_counter()
|
| 263 |
-
img = pipe(
|
| 264 |
-
image=[Image.new("RGB", (832, 1216), "white")],
|
| 265 |
-
prompt="<sks> front view eye-level shot wide shot The background is plain white.",
|
| 266 |
-
negative_prompt=" ",
|
| 267 |
-
height=1216,
|
| 268 |
-
width=832,
|
| 269 |
-
num_inference_steps=4,
|
| 270 |
-
generator=torch.Generator(device=DEVICE).manual_seed(0),
|
| 271 |
-
true_cfg_scale=1.0,
|
| 272 |
-
).images[0]
|
| 273 |
-
dt = __import__("time").perf_counter() - t0
|
| 274 |
-
return f"ok size={img.size} elapsed={dt:.1f}s peak={torch.cuda.max_memory_allocated() / 1024**3:.1f}GB"
|
| 275 |
-
|
| 276 |
-
|
| 277 |
-
def _build_payload(step: V.Step, user_extra: str, hq_framing: bool = False) -> dict:
|
| 278 |
-
if step.kind == "anchor":
|
| 279 |
-
prompt = V.anchor_prompt(step.prompt_of, user_extra)
|
| 280 |
-
else:
|
| 281 |
-
prompt = V.view_prompt(step.prompt_of, user_extra)
|
| 282 |
-
hq = bool(step.crop_kind and hq_framing)
|
| 283 |
-
return {
|
| 284 |
-
"key": step.key,
|
| 285 |
-
# アンカーが視点を兼ねる場合の別名。同一チャンク内の後続ステップが
|
| 286 |
-
# この key で条件画像を引くため、GPU 関数側にも渡す必要がある。
|
| 287 |
-
"alias": step.view_key if step.kind == "anchor" else "",
|
| 288 |
-
"prompt": prompt,
|
| 289 |
-
"source": step.source,
|
| 290 |
-
"width": step.size[0],
|
| 291 |
-
"height": step.size[1],
|
| 292 |
-
"crop": step.crop_kind,
|
| 293 |
-
"hq": hq,
|
| 294 |
-
# 2 枚条件付けは実測で約 1.8 倍の時間がかかる
|
| 295 |
-
"units": 1.8 if hq else 1.0,
|
| 296 |
-
}
|
| 297 |
-
|
| 298 |
-
|
| 299 |
-
def _gallery_items(images: Dict[str, Image.Image], selected: List[str]) -> List[Tuple[Image.Image, str]]:
|
| 300 |
-
items = []
|
| 301 |
-
for key in selected:
|
| 302 |
-
img = images.get(key)
|
| 303 |
-
if img is not None:
|
| 304 |
-
items.append((img, V.VIEW_BY_KEY[key].label_ja))
|
| 305 |
-
return items
|
| 306 |
-
|
| 307 |
-
|
| 308 |
-
def generate(
|
| 309 |
-
image,
|
| 310 |
-
selected_keys: List[str],
|
| 311 |
-
extra_prompt: str,
|
| 312 |
-
trigger_word: str,
|
| 313 |
-
exclude_tags: str,
|
| 314 |
-
tagger_choice: str,
|
| 315 |
-
wd_threshold: float,
|
| 316 |
-
oppai_threshold: float,
|
| 317 |
-
seed: int,
|
| 318 |
-
randomize_seed: bool,
|
| 319 |
-
true_guidance_scale: float,
|
| 320 |
-
num_inference_steps: int,
|
| 321 |
-
two_stage_prone: bool,
|
| 322 |
-
hq_framing: bool,
|
| 323 |
-
):
|
| 324 |
-
"""チャンクごとに GPU を取り直しながら生成し、途中経過��随時 yield する。
|
| 325 |
-
|
| 326 |
-
ジェネレータ自体は GPU 関数ではない。GPU を掴むのは `_run_chunk` だけで、
|
| 327 |
-
1 回あたりの要求 duration を小さく保つことでクォータ不足による門前払いを避ける。
|
| 328 |
-
"""
|
| 329 |
-
if image is None:
|
| 330 |
-
raise gr.Error("入力画像をアップロードしてください")
|
| 331 |
-
if not selected_keys:
|
| 332 |
-
raise gr.Error("視点を 1 つ以上選択してください")
|
| 333 |
-
|
| 334 |
-
if randomize_seed:
|
| 335 |
-
seed = random.randint(0, MAX_SEED)
|
| 336 |
-
|
| 337 |
-
reference = image.convert("RGB") if isinstance(image, Image.Image) else Image.open(image).convert("RGB")
|
| 338 |
-
|
| 339 |
-
plan = V.build_plan(selected_keys, two_stage_prone)
|
| 340 |
-
chunks = _chunks(plan, CHUNK_SIZE)
|
| 341 |
-
total_req, n_gen, n_chunks = estimate_quota(selected_keys, two_stage_prone, hq_framing)
|
| 342 |
-
|
| 343 |
-
images: Dict[str, Image.Image] = {"reference": reference}
|
| 344 |
-
done = 0
|
| 345 |
-
|
| 346 |
-
yield (
|
| 347 |
-
[],
|
| 348 |
-
gr.DownloadButton(value=None, interactive=False),
|
| 349 |
-
seed,
|
| 350 |
-
f"生成開始: {n_gen} 枚 / {n_chunks} 回に分割 / 要求 {total_req} 秒",
|
| 351 |
-
"",
|
| 352 |
)
|
| 353 |
-
|
| 354 |
-
|
| 355 |
-
|
| 356 |
-
|
| 357 |
-
|
| 358 |
-
|
| 359 |
-
|
| 360 |
-
|
| 361 |
-
|
| 362 |
-
|
| 363 |
-
|
| 364 |
-
|
| 365 |
-
|
| 366 |
-
)
|
| 367 |
-
|
| 368 |
-
|
| 369 |
-
|
| 370 |
-
|
| 371 |
-
|
| 372 |
-
|
| 373 |
-
|
| 374 |
-
|
| 375 |
-
|
| 376 |
-
|
| 377 |
-
|
| 378 |
-
|
| 379 |
-
|
| 380 |
-
|
| 381 |
-
|
| 382 |
-
|
| 383 |
-
)
|
| 384 |
-
|
| 385 |
-
|
| 386 |
-
|
| 387 |
-
|
| 388 |
-
|
| 389 |
-
|
| 390 |
-
|
| 391 |
-
|
| 392 |
-
|
| 393 |
-
|
| 394 |
-
|
| 395 |
-
|
| 396 |
-
|
| 397 |
-
|
| 398 |
-
|
| 399 |
-
|
| 400 |
-
|
| 401 |
-
|
| 402 |
-
|
| 403 |
-
|
| 404 |
-
|
| 405 |
-
try:
|
| 406 |
-
per_view[key][name] = tagging.TAGGERS[name].predict(img, thresholds[name])
|
| 407 |
-
except Exception as exc: # noqa: BLE001 - タグ付け失敗で生成物を捨てない
|
| 408 |
-
print(f"[app] タガー {name} が失敗: {exc}")
|
| 409 |
-
|
| 410 |
-
primary = active[0] if active else None
|
| 411 |
-
alt = active[1] if len(active) > 1 else None
|
| 412 |
-
|
| 413 |
-
zip_path = _build_zip(images, selected_keys, per_view, primary, alt, trigger_word, exclude_tags)
|
| 414 |
-
report = tagging.comparison_markdown(per_view) if (per_view and alt) else ""
|
| 415 |
-
|
| 416 |
-
yield (
|
| 417 |
-
_gallery_items(images, selected_keys),
|
| 418 |
-
gr.DownloadButton(value=zip_path, interactive=True),
|
| 419 |
-
seed,
|
| 420 |
-
f"完了: {len(per_view)} 視点 / 要求クォータ 合計 {total_req} 秒 (seed {seed})",
|
| 421 |
-
report,
|
| 422 |
-
)
|
| 423 |
-
|
| 424 |
-
|
| 425 |
-
def _build_zip(
|
| 426 |
-
images: Dict[str, Image.Image],
|
| 427 |
-
selected_keys: List[str],
|
| 428 |
-
per_view: Dict[str, Dict[str, tagging.TagResult]],
|
| 429 |
-
primary: str,
|
| 430 |
-
alt: str,
|
| 431 |
-
trigger_word: str,
|
| 432 |
-
exclude_tags: str,
|
| 433 |
-
) -> str:
|
| 434 |
-
"""kohya-ss にそのまま食わせられる構成で ZIP を作る。
|
| 435 |
-
|
| 436 |
-
dataset/NN_key.png + NN_key.txt <- 主タガーのキャプション
|
| 437 |
-
captions_alt/NN_key.txt <- 比較用のもう一方
|
| 438 |
-
caption_comparison.md
|
| 439 |
-
"""
|
| 440 |
-
exclude = tagging.parse_exclude(exclude_tags)
|
| 441 |
-
tmp_dir = tempfile.mkdtemp()
|
| 442 |
-
zip_path = os.path.join(tmp_dir, "character_views.zip")
|
| 443 |
-
|
| 444 |
-
with zipfile.ZipFile(zip_path, "w", zipfile.ZIP_DEFLATED) as zf:
|
| 445 |
-
for i, key in enumerate(selected_keys, start=1):
|
| 446 |
-
img = images.get(key)
|
| 447 |
-
if img is None:
|
| 448 |
-
continue
|
| 449 |
-
base = f"{i:02d}_{key}"
|
| 450 |
-
|
| 451 |
-
buf = io.BytesIO()
|
| 452 |
-
img.convert("RGB").save(buf, format="PNG")
|
| 453 |
-
zf.writestr(f"dataset/{base}.png", buf.getvalue())
|
| 454 |
-
|
| 455 |
-
fixed = V.caption_tags(V.VIEW_BY_KEY[key])
|
| 456 |
-
results = per_view.get(key, {})
|
| 457 |
-
|
| 458 |
-
if primary:
|
| 459 |
-
predicted = results[primary].names() if primary in results else []
|
| 460 |
-
zf.writestr(
|
| 461 |
-
f"dataset/{base}.txt",
|
| 462 |
-
tagging.build_caption(fixed, predicted, trigger_word, exclude),
|
| 463 |
-
)
|
| 464 |
-
else:
|
| 465 |
-
# タガーを使わない場合でも構図タグだけのキャプションは出しておく
|
| 466 |
-
zf.writestr(
|
| 467 |
-
f"dataset/{base}.txt",
|
| 468 |
-
tagging.build_caption(fixed, [], trigger_word, exclude),
|
| 469 |
-
)
|
| 470 |
-
|
| 471 |
-
if alt and alt in results:
|
| 472 |
-
zf.writestr(
|
| 473 |
-
f"captions_alt/{base}.txt",
|
| 474 |
-
tagging.build_caption(fixed, results[alt].names(), trigger_word, exclude),
|
| 475 |
-
)
|
| 476 |
-
|
| 477 |
-
if per_view and alt:
|
| 478 |
-
zf.writestr("caption_comparison.md", tagging.comparison_markdown(per_view))
|
| 479 |
-
|
| 480 |
-
return zip_path
|
| 481 |
-
|
| 482 |
-
|
| 483 |
-
# --- UI ---------------------------------------------------------------------
|
| 484 |
-
|
| 485 |
-
CSS = """
|
| 486 |
-
#col-container {margin: 0 auto; max-width: 1400px;}
|
| 487 |
-
.notice {
|
| 488 |
-
background: #fff5f5; border: 1px solid #fca5a5; color: #7f1d1d;
|
| 489 |
-
padding: 12px 14px; border-radius: 10px; font-weight: 600;
|
| 490 |
-
line-height: 1.5; margin-bottom: 10px;
|
| 491 |
-
}
|
| 492 |
-
.quota {
|
| 493 |
-
background: #f0f9ff; border: 1px solid #7dd3fc; color: #0c4a6e;
|
| 494 |
-
padding: 10px 14px; border-radius: 10px; line-height: 1.6;
|
| 495 |
-
}
|
| 496 |
-
"""
|
| 497 |
-
|
| 498 |
-
|
| 499 |
-
def quota_markdown(*group_values) -> str:
|
| 500 |
-
selected = [k for group in group_values[:-2] for k in group]
|
| 501 |
-
two_stage = bool(group_values[-2])
|
| 502 |
-
hq = bool(group_values[-1])
|
| 503 |
-
requested, n_gen, n_chunks = estimate_quota(selected, two_stage, hq)
|
| 504 |
-
if not n_gen:
|
| 505 |
-
return "<div class='quota'>視点が選択されていません。</div>"
|
| 506 |
-
|
| 507 |
-
# xlarge は要求 duration が内部で 2 倍されてクォータから引かれる
|
| 508 |
-
total = requested * QUOTA_MULTIPLIER
|
| 509 |
-
|
| 510 |
-
def verdict(limit: int) -> str:
|
| 511 |
-
if total <= limit:
|
| 512 |
-
return f"✅ {limit}秒以内 (残り {limit - total}秒)"
|
| 513 |
-
return f"❌ {total - limit}秒 超過"
|
| 514 |
-
|
| 515 |
-
extra = ""
|
| 516 |
-
if n_gen > len(selected):
|
| 517 |
-
extra = (
|
| 518 |
-
f"<br><small>※ 生成 {n_gen} 枚のうち {n_gen - len(selected)} 枚は、"
|
| 519 |
-
"寄りの切り出し元やポーズ基準として必要な中間生成です。</small>"
|
| 520 |
-
)
|
| 521 |
-
|
| 522 |
-
size_note = (
|
| 523 |
-
f" <small>(GPU size <code>{GPU_SIZE}</code> のため要求 {requested} 秒 × 2)</small>"
|
| 524 |
-
if QUOTA_MULTIPLIER > 1
|
| 525 |
-
else ""
|
| 526 |
-
)
|
| 527 |
-
return (
|
| 528 |
-
"<div class='quota'>"
|
| 529 |
-
f"<b>推定 ZeroGPU 消費: {total} 秒</b>{size_note} "
|
| 530 |
-
f"({len(selected)} 視点 / 生成 {n_gen} 枚 / {n_chunks} 回に分割)<br>"
|
| 531 |
-
f"無料会員 (300秒/日): {verdict(FREE_QUOTA_SEC)}<br>"
|
| 532 |
-
f"未認証 (120秒/日): {verdict(ANON_QUOTA_SEC)}"
|
| 533 |
-
f"{extra}"
|
| 534 |
-
"</div>"
|
| 535 |
-
)
|
| 536 |
-
|
| 537 |
-
|
| 538 |
-
with gr.Blocks(css=CSS) as demo:
|
| 539 |
-
gr.Markdown("# キャラクター視点シート生成 (Qwen-Image-Edit-2511 + 角度LoRA)")
|
| 540 |
gr.Markdown(
|
| 541 |
-
"
|
| 542 |
-
"
|
| 543 |
-
"
|
| 544 |
-
"
|
| 545 |
-
"
|
| 546 |
-
"無料枠で通りやすくなります。生成は自動で複数回に分割されるため、"
|
| 547 |
-
"途中でクォータが尽きてもそこまでの結果は残ります。"
|
| 548 |
)
|
| 549 |
-
|
| 550 |
-
|
| 551 |
-
|
| 552 |
-
|
| 553 |
-
"
|
| 554 |
-
"
|
| 555 |
-
"
|
| 556 |
-
"
|
| 557 |
-
)
|
| 558 |
-
|
| 559 |
-
|
| 560 |
-
|
| 561 |
-
|
| 562 |
-
|
| 563 |
-
|
| 564 |
-
placeholder="例: anime style, soft lighting, pastel colors",
|
| 565 |
-
lines=2,
|
| 566 |
-
)
|
| 567 |
-
|
| 568 |
-
with gr.Column(scale=1):
|
| 569 |
-
gr.Markdown("### 生成する視点")
|
| 570 |
-
group_boxes = []
|
| 571 |
-
for group in V.GROUP_ORDER:
|
| 572 |
-
members = [v for v in V.VIEWS if v.group_ja == group]
|
| 573 |
-
group_boxes.append(
|
| 574 |
-
gr.CheckboxGroup(
|
| 575 |
-
label=group,
|
| 576 |
-
choices=[(v.label_ja, v.key) for v in members],
|
| 577 |
-
value=[v.key for v in members],
|
| 578 |
-
)
|
| 579 |
-
)
|
| 580 |
-
with gr.Row():
|
| 581 |
-
preset_buttons = [gr.Button(name, size="sm") for name in V.PRESETS]
|
| 582 |
-
hq_framing = gr.Checkbox(
|
| 583 |
-
label="寄り視点を高品質モードで生成 (時間 約1.8倍)",
|
| 584 |
-
value=False,
|
| 585 |
-
info="顔・上半身・カウボーイを「クロップ + 全身」の2枚で条件付けします。"
|
| 586 |
-
"情報量が増えて精細になりますが、要求クォータも増えます。",
|
| 587 |
-
)
|
| 588 |
-
quota_box = gr.HTML(value=quota_markdown(*[[v.key for v in V.VIEWS], False, False]))
|
| 589 |
-
|
| 590 |
-
run_button = gr.Button("🎨 生成", variant="primary")
|
| 591 |
-
status_text = gr.Textbox(label="ステータス", interactive=False)
|
| 592 |
-
gallery = gr.Gallery(
|
| 593 |
-
label="生成結果", columns=4, height=620, object_fit="contain", show_download_button=True
|
| 594 |
-
)
|
| 595 |
-
download_btn = gr.DownloadButton(
|
| 596 |
-
label="📦 学習用データセット (画像 + キャプション) を ZIP でダウンロード",
|
| 597 |
-
value=None,
|
| 598 |
-
variant="secondary",
|
| 599 |
-
interactive=False,
|
| 600 |
-
)
|
| 601 |
-
|
| 602 |
-
with gr.Accordion("🏷️ キャプション設定 (LoRA 学習用)", open=True):
|
| 603 |
-
gr.Markdown(
|
| 604 |
-
"タグ付けは **CPU (onnxruntime)** で実行するため ZeroGPU のクォータを消費しません。\n\n"
|
| 605 |
-
"構図タグ (`full body` / `from behind` / `from above` / `cowboy shot` など) は"
|
| 606 |
-
"カメラ設定から**決定的に注入**しています。タガーは構図を安定して当てられないためです。"
|
| 607 |
-
)
|
| 608 |
-
with gr.Row():
|
| 609 |
-
trigger_word = gr.Textbox(
|
| 610 |
-
label="トリガーワード (全キャプションの先頭に付与)",
|
| 611 |
-
placeholder="例: mychar",
|
| 612 |
-
)
|
| 613 |
-
exclude_tags = gr.Textbox(
|
| 614 |
-
label="除外タグ (カンマ区切り)",
|
| 615 |
-
placeholder="例: black hair, blue eyes ← LoRA に焼き込みたい特徴を外す",
|
| 616 |
-
)
|
| 617 |
-
tagger_choice = gr.Radio(
|
| 618 |
-
label="使用するタガー",
|
| 619 |
-
choices=["WD Tagger v3", "OppaiOracle V1.1", "両方 (比較する)"],
|
| 620 |
-
value="両方 (比較する)",
|
| 621 |
)
|
| 622 |
-
|
| 623 |
-
|
| 624 |
-
|
| 625 |
-
|
| 626 |
-
|
| 627 |
-
|
| 628 |
-
|
| 629 |
-
|
| 630 |
-
|
| 631 |
-
|
| 632 |
-
|
| 633 |
-
|
| 634 |
-
|
| 635 |
-
|
| 636 |
-
|
| 637 |
-
|
| 638 |
-
|
| 639 |
-
|
| 640 |
-
|
| 641 |
-
|
| 642 |
-
|
| 643 |
-
label="True guidance scale", minimum=1.0, maximum=10.0, step=0.1, value=1.0
|
| 644 |
-
)
|
| 645 |
-
num_inference_steps = gr.Slider(
|
| 646 |
-
label="生成ステップ数 (Lightning LoRA 前提で 4 推奨)",
|
| 647 |
-
minimum=1, maximum=40, step=1, value=4,
|
| 648 |
-
)
|
| 649 |
-
gr.Markdown("#### 診断")
|
| 650 |
-
with gr.Row():
|
| 651 |
-
selftest_btn = gr.Button("GPU 取得テスト", size="sm")
|
| 652 |
-
pipetest_btn = gr.Button("pipe() 単発テスト", size="sm")
|
| 653 |
-
selftest_out = gr.Textbox(label="診断結果", interactive=False)
|
| 654 |
-
|
| 655 |
-
two_stage_prone = gr.Checkbox(
|
| 656 |
-
label="うつ伏せを 2 段階で生成する (品質優先 / 生成 +1 枚)",
|
| 657 |
-
value=False,
|
| 658 |
-
info="ポーズ変更とカメラ移動を分けます。1 段階で破綻する場合に有効化してください。",
|
| 659 |
-
)
|
| 660 |
-
|
| 661 |
-
selftest_btn.click(fn=gpu_selftest, inputs=None, outputs=selftest_out)
|
| 662 |
-
pipetest_btn.click(fn=gpu_pipe_selftest, inputs=None, outputs=selftest_out)
|
| 663 |
-
|
| 664 |
-
# --- イベント ---
|
| 665 |
-
quota_inputs = group_boxes + [two_stage_prone, hq_framing]
|
| 666 |
-
for comp in quota_inputs:
|
| 667 |
-
comp.change(fn=quota_markdown, inputs=quota_inputs, outputs=quota_box)
|
| 668 |
-
|
| 669 |
-
for button, preset_name in zip(preset_buttons, V.PRESETS):
|
| 670 |
-
keys = V.PRESETS[preset_name]
|
| 671 |
-
|
| 672 |
-
def _apply(keys=keys):
|
| 673 |
-
return [
|
| 674 |
-
gr.CheckboxGroup(value=[v.key for v in V.VIEWS if v.group_ja == g and v.key in keys])
|
| 675 |
-
for g in V.GROUP_ORDER
|
| 676 |
-
]
|
| 677 |
-
|
| 678 |
-
button.click(fn=_apply, inputs=None, outputs=group_boxes).then(
|
| 679 |
-
fn=quota_markdown, inputs=quota_inputs, outputs=quota_box
|
| 680 |
-
)
|
| 681 |
-
|
| 682 |
-
def _collect_and_generate(image, *args):
|
| 683 |
-
n_groups = len(V.GROUP_ORDER)
|
| 684 |
-
selected = [k for group in args[:n_groups] for k in group]
|
| 685 |
-
yield from generate(image, selected, *args[n_groups:])
|
| 686 |
-
|
| 687 |
-
run_button.click(
|
| 688 |
-
fn=_collect_and_generate,
|
| 689 |
-
inputs=[input_image, *group_boxes, extra_prompt, trigger_word, exclude_tags,
|
| 690 |
-
tagger_choice, wd_threshold, oppai_threshold, seed, randomize_seed,
|
| 691 |
-
true_guidance_scale, num_inference_steps, two_stage_prone, hq_framing],
|
| 692 |
-
outputs=[gallery, download_btn, seed, status_text, comparison_md],
|
| 693 |
-
)
|
| 694 |
-
|
| 695 |
|
| 696 |
if __name__ == "__main__":
|
| 697 |
-
demo.launch()
|
|
|
|
| 1 |
+
"""Character View Sheet: 11 views, optional mannequin guides, PNG-only export."""
|
| 2 |
+
import json
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
import random
|
| 4 |
import tempfile
|
| 5 |
+
import time
|
| 6 |
+
from pathlib import Path
|
| 7 |
|
| 8 |
import gradio as gr
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 9 |
|
| 10 |
+
from backend import MAX_GPU_SECONDS, QUOTA_MULTIPLIER, USE_ANGLES, run_gpu
|
| 11 |
+
from core import build_zip, prepare_reference, requested_seconds
|
| 12 |
+
from pose_guides import ensure_guides, get_guide
|
| 13 |
+
from views import BY_KEY, DEFAULT_KEYS, SIZES, VIEWS, validate_keys
|
| 14 |
|
| 15 |
+
GUIDES = ensure_guides()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 16 |
|
| 17 |
|
| 18 |
+
def allocation_message(keys):
|
| 19 |
+
if not keys:
|
| 20 |
+
return "視点を選択してください。"
|
| 21 |
+
allocation = requested_seconds(keys, MAX_GPU_SECONDS)
|
| 22 |
+
quota = allocation * QUOTA_MULTIPLIER
|
| 23 |
+
message = (
|
| 24 |
+
f"選択: {len(set(keys))}視点。1回のGPU時間枠は最大{allocation}秒"
|
| 25 |
+
f"(利用枠への換算: {quota}秒)。\n\n"
|
| 26 |
+
"未ログインの1日枠は120秒です。他のZeroGPU利用分と共有されます。"
|
| 27 |
+
"11視点の完成時間は設定や混雑で変わります。余裕がなくなったら、完成済み画像を返します。"
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 28 |
)
|
| 29 |
+
if quota > 120:
|
| 30 |
+
message += "\n\n現在のGPU設定では未ログインの1日枠を超えます。"
|
| 31 |
+
return message
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
def pose_preview(keys):
|
| 35 |
+
return [(str(GUIDES[key]), BY_KEY[key].label) for key in (keys or []) if key in BY_KEY]
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
def generate(reference, keys, pose_enabled, resolution, extra, seed, random_seed, crop_close_views=False):
|
| 39 |
+
# Invalid retry inputs must not leave a previous character's ZIP visible.
|
| 40 |
+
yield [], None, None, "入力を確認しています。", seed
|
| 41 |
+
if reference is None:
|
| 42 |
+
raise gr.Error("キャラクターの参照画像をアップロードしてください。")
|
| 43 |
+
try:
|
| 44 |
+
keys = validate_keys(keys)
|
| 45 |
+
except ValueError as exc:
|
| 46 |
+
raise gr.Error(str(exc)) from exc
|
| 47 |
+
if resolution not in SIZES:
|
| 48 |
+
raise gr.Error("解像度を選択してください。")
|
| 49 |
+
seed = random.randint(0, 2**31 - 1) if random_seed else int(seed)
|
| 50 |
+
reference = prepare_reference(reference, 768 if resolution == "fast" else 1216)
|
| 51 |
+
guides = None
|
| 52 |
+
if pose_enabled:
|
| 53 |
+
guides = {key: get_guide(key, *SIZES[resolution][BY_KEY[key].shape]) for key in keys}
|
| 54 |
+
|
| 55 |
+
# Clear stale downloads and results before requesting GPU time.
|
| 56 |
+
yield [], None, None, "生成中です。", seed
|
| 57 |
+
started = time.perf_counter()
|
| 58 |
+
try:
|
| 59 |
+
images, reason, metrics = run_gpu(reference, keys, guides, resolution, seed, extra or "", crop_close_views)
|
| 60 |
+
except Exception as exc:
|
| 61 |
+
print(f"[app] GPU request failed: {type(exc).__name__}: {exc}", flush=True)
|
| 62 |
+
# Keep infrastructure quota errors visible; no invented successful result.
|
| 63 |
+
yield [], None, None, f"生成できませんでした: {exc}", seed
|
| 64 |
+
return
|
| 65 |
+
metrics["request_wall_seconds"] = round(time.perf_counter() - started, 3)
|
| 66 |
+
gallery = [(images[key], BY_KEY[key].label) for key in keys if key in images]
|
| 67 |
+
status = f"{len(images)}/{len(keys)}視点を生成しました。Seed: {seed}"
|
| 68 |
+
if reason:
|
| 69 |
+
status += "\n" + reason
|
| 70 |
+
# Gradio caches yielded files before requesting the next generator item.
|
| 71 |
+
# Keep originals alive across this yield, then remove both report and ZIP.
|
| 72 |
+
with tempfile.TemporaryDirectory(prefix="view-result-") as result_dir:
|
| 73 |
+
report = Path(result_dir) / "generation_metrics.json"
|
| 74 |
+
report.write_text(json.dumps(metrics, ensure_ascii=False, indent=2), encoding="utf-8")
|
| 75 |
+
archive = build_zip(images, keys, output_dir=result_dir)
|
| 76 |
+
yield gallery, archive, str(report), status, seed
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
with gr.Blocks(title="Character View Sheet (Qwen Image 2.1 turbo)", delete_cache=(3600, 3600)) as demo:
|
| 80 |
+
gr.Markdown("# Character View Sheet (Qwen Image 2.1 turbo)\n参照画像とポーズ人形から、学習用の11視点を生成します。")
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 81 |
gr.Markdown(
|
| 82 |
+
"**研究用デモ** · 多視点生成の速度・人物同一性・ポーズ追従を評価するための試作です。"
|
| 83 |
+
"利用モデルのライセンスは "
|
| 84 |
+
"[Qwen Research License](https://huggingface.co/Qwen/Qwen-Image-2.1-Turbo/blob/main/LICENSE)です。"
|
| 85 |
+
"商用利用は別許諾が必要です。生成画像から学習したモデルを配布・提供する場合、"
|
| 86 |
+
"関連文書に「Built with Qwen」または「Improved using Qwen」の表示条件があります。"
|
|
|
|
|
|
|
| 87 |
)
|
| 88 |
+
with gr.Row():
|
| 89 |
+
with gr.Column():
|
| 90 |
+
reference = gr.Image(label="キャラクターの参照画像", type="pil", height=380)
|
| 91 |
+
pose_enabled = gr.Checkbox(label="ポーズ人形を参照する", value=True)
|
| 92 |
+
crop_close_views = gr.Checkbox(label="白背景の直立全身画像:顔・上半身用に切り出す", value=False)
|
| 93 |
+
gr.Markdown("切り出しは実験機能です。構図が改善する一方、衣装の形が変わる場合があります。")
|
| 94 |
+
gr.Markdown("人形の姿勢・向き・構図を参考にします。関節位置を厳密に固定する機能ではありません。")
|
| 95 |
+
extra = gr.Textbox(label="追加の指示", placeholder="例: 元画像の線画と塗り方を維持", lines=2, max_lines=4)
|
| 96 |
+
with gr.Column():
|
| 97 |
+
keys = gr.CheckboxGroup(label="生成する視点", choices=[(v.label, v.key) for v in VIEWS], value=DEFAULT_KEYS)
|
| 98 |
+
resolution = gr.Radio(
|
| 99 |
+
label="画像サイズ", choices=[("高速: 全身512×768・寄り640×640", "fast"),
|
| 100 |
+
("標準・速度優先: 全身832×1216・寄り1024×1024", "balanced"),
|
| 101 |
+
("標準・細部優先: 全身832×1216・寄り1024×1024", "standard")],
|
| 102 |
+
value="balanced",
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 103 |
)
|
| 104 |
+
allocation = gr.Markdown(allocation_message(DEFAULT_KEYS))
|
| 105 |
+
with gr.Accordion("ポーズ人形を確認", open=False):
|
| 106 |
+
previews = gr.Gallery(value=pose_preview(DEFAULT_KEYS), columns=4, height=430,
|
| 107 |
+
label="ポーズ参照", object_fit="contain", interactive=False)
|
| 108 |
+
with gr.Accordion("Seed設定", open=False):
|
| 109 |
+
seed = gr.Number(label="Seed", value=0, precision=0, minimum=0, maximum=2**31 - 1)
|
| 110 |
+
random_seed = gr.Checkbox(label="ランダムSeed", value=True)
|
| 111 |
+
run = gr.Button("選択した視点を生成", variant="primary")
|
| 112 |
+
status = gr.Textbox(label="進行状況", interactive=False)
|
| 113 |
+
results = gr.Gallery(label="生成した画像", columns=4, height=580, object_fit="contain")
|
| 114 |
+
download = gr.File(label="画像だけのZIP", interactive=False)
|
| 115 |
+
with gr.Accordion("実行時間の記録", open=False):
|
| 116 |
+
report = gr.File(label="計測結果 JSON", interactive=False)
|
| 117 |
+
gr.Markdown("高速化の確認用です。画像ZIPには画像だけが入ります。")
|
| 118 |
+
if USE_ANGLES:
|
| 119 |
+
gr.Markdown("2.1用角度LoRAを併用した実験設定です。")
|
| 120 |
+
|
| 121 |
+
keys.change(fn=allocation_message, inputs=keys, outputs=allocation, queue=False)
|
| 122 |
+
keys.change(fn=pose_preview, inputs=keys, outputs=previews, queue=False)
|
| 123 |
+
run.click(generate, [reference, keys, pose_enabled, resolution, extra, seed, random_seed, crop_close_views],
|
| 124 |
+
[results, download, report, status, seed], concurrency_limit=1, concurrency_id="generation")
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 125 |
|
| 126 |
if __name__ == "__main__":
|
| 127 |
+
demo.queue(max_size=8, default_concurrency_limit=1).launch(max_file_size="20mb")
|
assets/cowboy_back.png
ADDED

|
Git LFS Details
|
assets/cowboy_front.png
ADDED

|
Git LFS Details
|
assets/face_front.png
ADDED
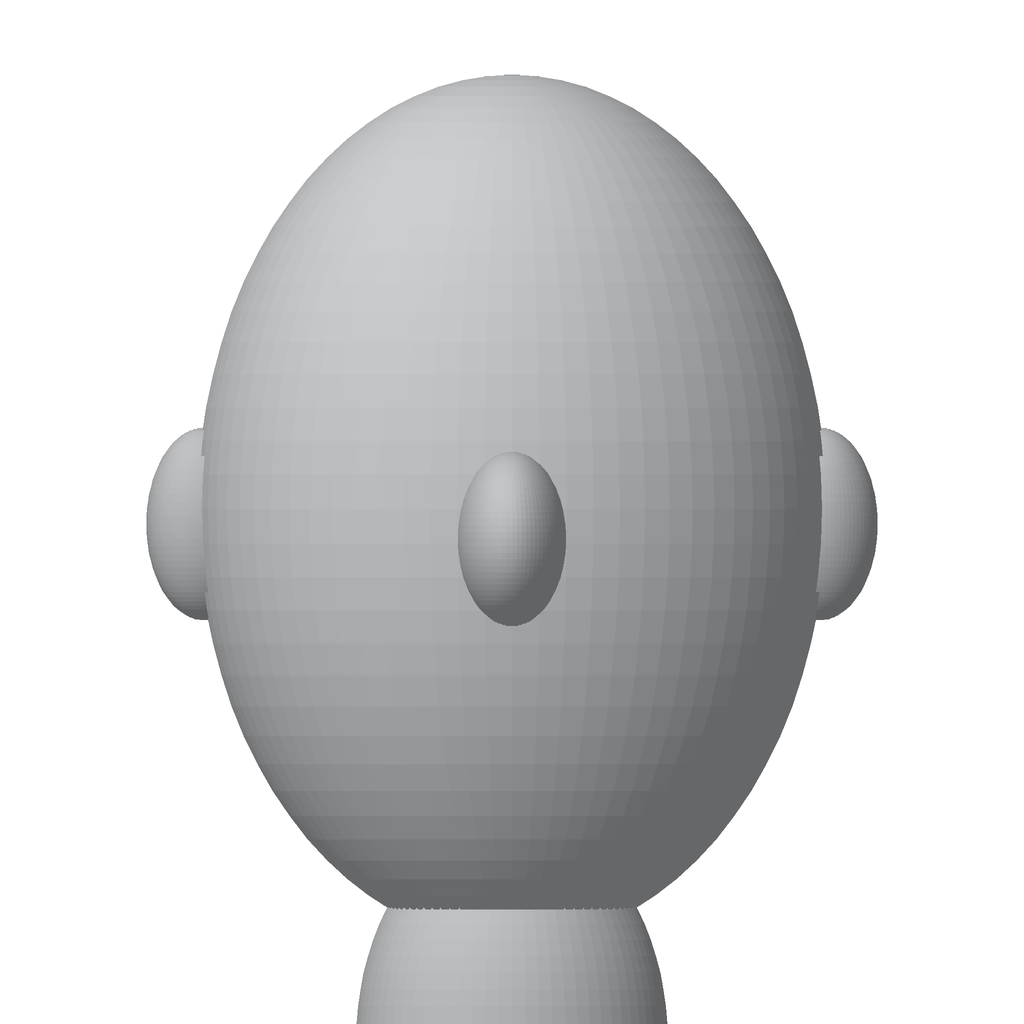
|
assets/full_back.png
ADDED

|
Git LFS Details
|
assets/full_front.png
ADDED

|
Git LFS Details
|
assets/full_left.png
ADDED
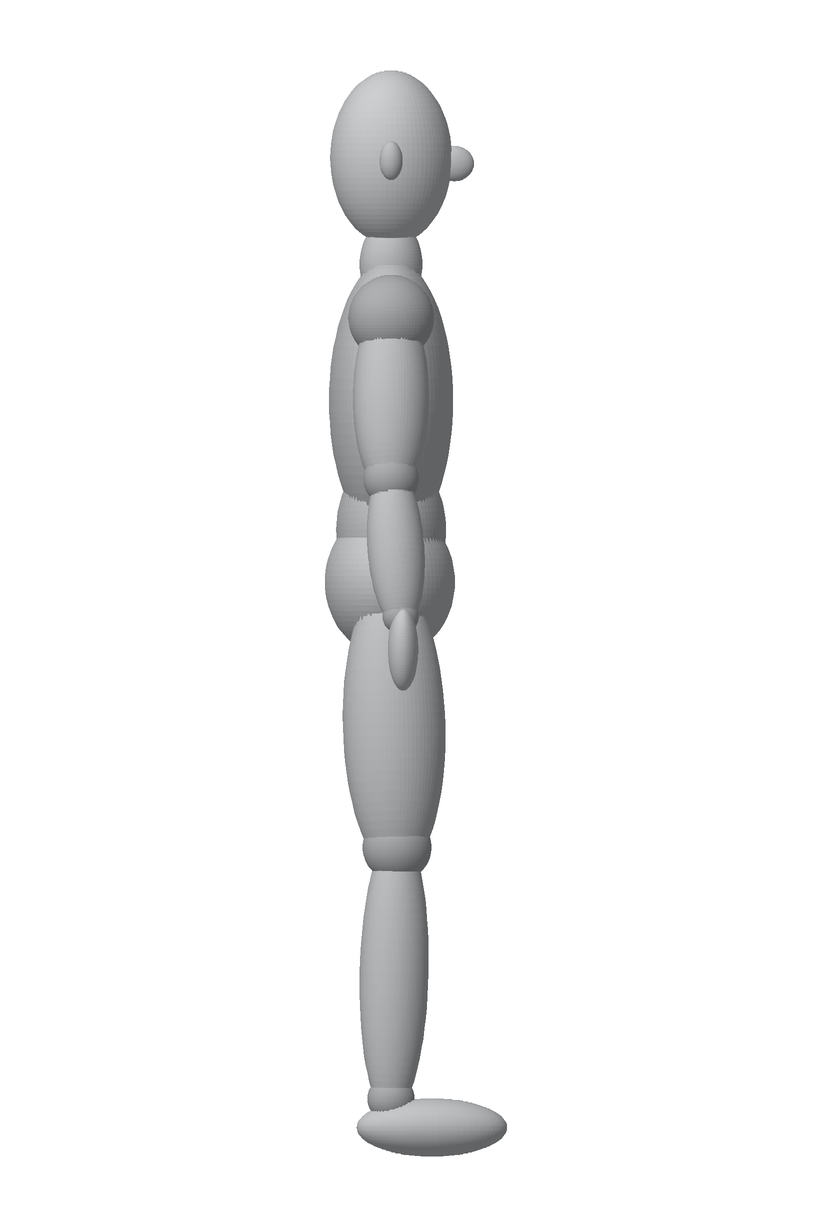
|
assets/full_right.png
ADDED
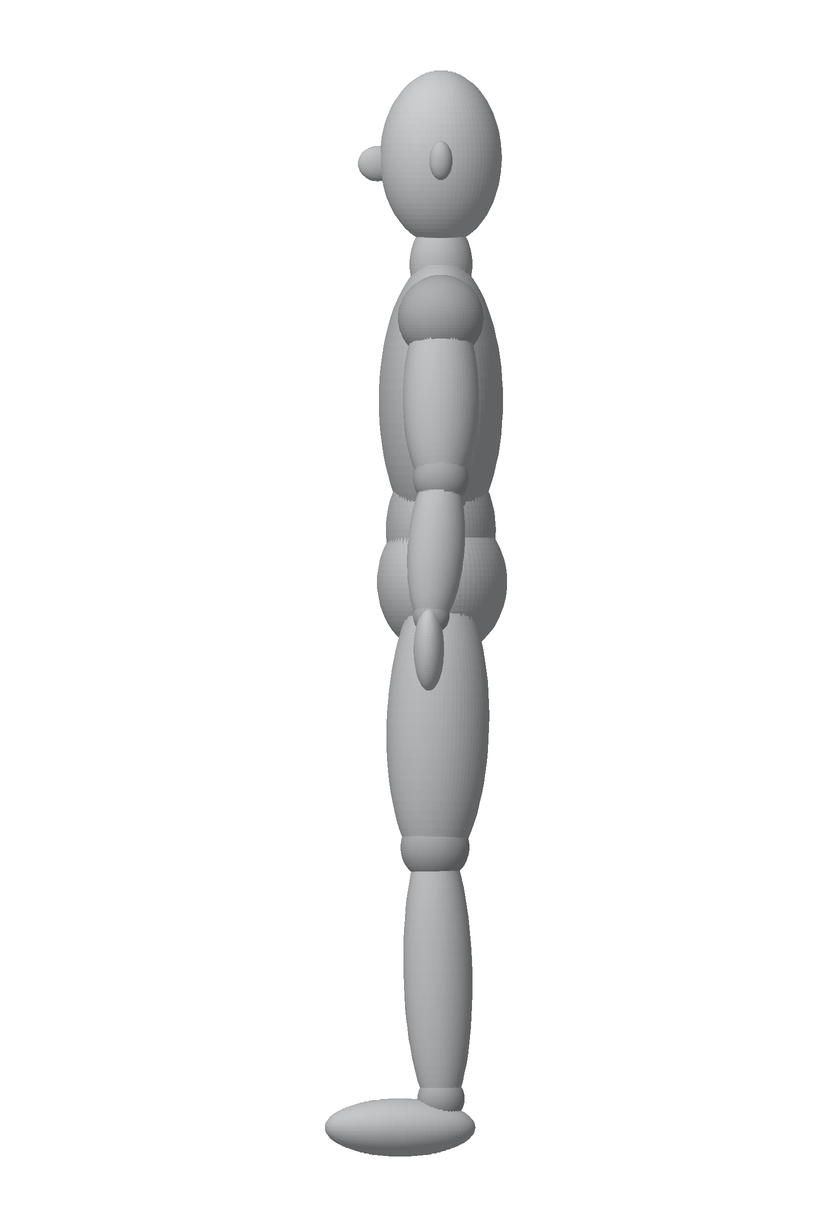
|
assets/knees_back.png
ADDED

|
Git LFS Details
|
assets/knees_front.png
ADDED

|
Git LFS Details
|
assets/pose_preview.png
ADDED

|
Git LFS Details
|
assets/prone_back.png
ADDED

|
Git LFS Details
|
assets/upper_front.png
ADDED
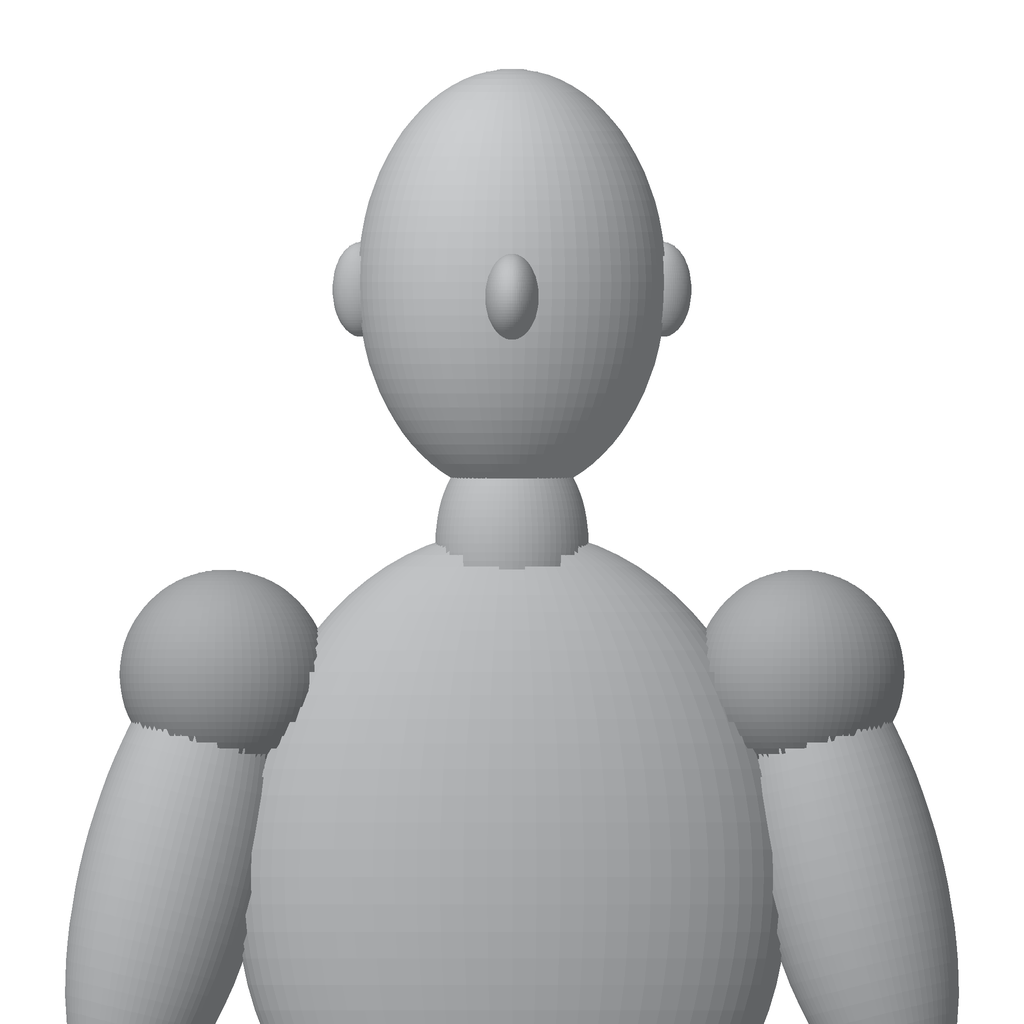
|
backend.py
ADDED
|
@@ -0,0 +1,92 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Turbo workflow verified on local CUDA and Hugging Face ZeroGPU large."""
|
| 2 |
+
import os
|
| 3 |
+
import time
|
| 4 |
+
|
| 5 |
+
import spaces
|
| 6 |
+
import torch
|
| 7 |
+
from diffusers import QwenImage21Pipeline
|
| 8 |
+
from huggingface_hub import hf_hub_download
|
| 9 |
+
|
| 10 |
+
from core import requested_seconds, run_batch, rgb_on_white
|
| 11 |
+
from angles_adapter import load_angles_adapter
|
| 12 |
+
from views import REFERENCE_RESOLUTION
|
| 13 |
+
|
| 14 |
+
MODEL_ID = "Qwen/Qwen-Image-2.1-Turbo"
|
| 15 |
+
MODEL_REVISION = "d65dbc9a7e8f6b5479e33dee6030eaab2a906509"
|
| 16 |
+
GPU_SIZE = os.getenv("GPU_SIZE", "large")
|
| 17 |
+
if GPU_SIZE not in ("large", "xlarge"):
|
| 18 |
+
raise ValueError("GPU_SIZE must be large or xlarge")
|
| 19 |
+
QUOTA_MULTIPLIER = 2 if GPU_SIZE == "xlarge" else 1
|
| 20 |
+
MAX_GPU_SECONDS = int(os.getenv("MAX_GPU_SECONDS", "110"))
|
| 21 |
+
if not 45 <= MAX_GPU_SECONDS <= 110:
|
| 22 |
+
raise ValueError("MAX_GPU_SECONDS must be between 45 and 110")
|
| 23 |
+
STARTUP_RESERVE_SECONDS = 15
|
| 24 |
+
USE_ANGLES = os.getenv("ENABLE_ANGLES_LORA", "0") == "1"
|
| 25 |
+
ANGLES_REPO = "akhaliq/Qwen-Image-2.1-Multiple-Angles-LoRA"
|
| 26 |
+
ANGLES_WEIGHT = ("checkpoints_v2/angles_v2_full_qwen21_multiple_angles_v2_"
|
| 27 |
+
"qwen21_multiple_angles_v2_000001500.safetensors")
|
| 28 |
+
|
| 29 |
+
# ZeroGPU requires startup CUDA placement, not moving the model for each request.
|
| 30 |
+
# Do not reuse the old 2511 Lightning or angles adapters on this architecture.
|
| 31 |
+
pipe = QwenImage21Pipeline.from_pretrained(
|
| 32 |
+
MODEL_ID, revision=MODEL_REVISION, dtype=torch.bfloat16,
|
| 33 |
+
)
|
| 34 |
+
if USE_ANGLES:
|
| 35 |
+
checkpoint = hf_hub_download(ANGLES_REPO, filename=ANGLES_WEIGHT)
|
| 36 |
+
print(load_angles_adapter(pipe, checkpoint, adapter_name="angles", strength=0.8))
|
| 37 |
+
pipe.fuse_lora(adapter_names=["angles"])
|
| 38 |
+
pipe.unload_lora_weights()
|
| 39 |
+
pipe.vae.enable_tiling()
|
| 40 |
+
pipe.to("cuda")
|
| 41 |
+
if len(pipe.config.get("sample_sigmas", [])) != 8:
|
| 42 |
+
raise RuntimeError("Turboの8-stepスケジュールを読み込めていません。Diffusersのバージョンを確認してください。")
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
def duration(reference, keys, guides, resolution, seed, extra, crop_close_views=False):
|
| 46 |
+
return requested_seconds(keys, MAX_GPU_SECONDS)
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
@spaces.GPU(duration=duration, size=GPU_SIZE)
|
| 50 |
+
def run_gpu(reference, keys, guides, resolution, seed, extra, crop_close_views=False):
|
| 51 |
+
started = time.perf_counter()
|
| 52 |
+
torch.cuda.reset_peak_memory_stats()
|
| 53 |
+
|
| 54 |
+
def generate_one(*, image, prompt, width, height, seed, check_budget):
|
| 55 |
+
def callback(pipeline, step, timestep, callback_kwargs):
|
| 56 |
+
check_budget()
|
| 57 |
+
return callback_kwargs
|
| 58 |
+
|
| 59 |
+
output = pipe(
|
| 60 |
+
image=image,
|
| 61 |
+
prompt=prompt,
|
| 62 |
+
width=width,
|
| 63 |
+
height=height,
|
| 64 |
+
# Also bounds the area used to encode EACH reference; reducing only
|
| 65 |
+
# PIL input dimensions does not avoid the pipeline's internal upscaling.
|
| 66 |
+
output_resolution=REFERENCE_RESOLUTION[resolution],
|
| 67 |
+
true_cfg_scale=1.0,
|
| 68 |
+
use_kv_cache=True,
|
| 69 |
+
num_images_per_prompt=1,
|
| 70 |
+
generator=torch.Generator("cpu").manual_seed(seed),
|
| 71 |
+
callback_on_step_end=callback,
|
| 72 |
+
).images[0]
|
| 73 |
+
return rgb_on_white(output)
|
| 74 |
+
|
| 75 |
+
allocation = duration(reference, keys, guides, resolution, seed, extra)
|
| 76 |
+
result = run_batch(
|
| 77 |
+
generate_one, reference, keys, guides, resolution, seed, extra, USE_ANGLES,
|
| 78 |
+
budget_seconds=allocation - STARTUP_RESERVE_SECONDS,
|
| 79 |
+
crop_close_views=crop_close_views,
|
| 80 |
+
)
|
| 81 |
+
metrics = {
|
| 82 |
+
"model": MODEL_ID, "revision": MODEL_REVISION, "gpu": torch.cuda.get_device_name(),
|
| 83 |
+
"gpu_size": GPU_SIZE, "reserved_seconds": allocation,
|
| 84 |
+
"quota_budget_seconds": allocation * QUOTA_MULTIPLIER,
|
| 85 |
+
"gpu_function_seconds": round(time.perf_counter() - started, 3),
|
| 86 |
+
"peak_allocated_gib": round(torch.cuda.max_memory_allocated() / 1024**3, 2),
|
| 87 |
+
"resolution": resolution, "pose_guides": guides is not None, "angles_lora": USE_ANGLES,
|
| 88 |
+
"crop_close_views": crop_close_views,
|
| 89 |
+
"seed": int(seed), "requested_views": keys, "completed_views": list(result.images),
|
| 90 |
+
"timings": result.timings, "stop_reason": result.stop_reason,
|
| 91 |
+
}
|
| 92 |
+
return result.images, result.stop_reason, metrics
|
bench/README.md
DELETED
|
@@ -1,102 +0,0 @@
|
|
| 1 |
-
---
|
| 2 |
-
title: Krea2 vs Qwen-Image-Edit Benchmark
|
| 3 |
-
emoji: ⏱️
|
| 4 |
-
colorFrom: yellow
|
| 5 |
-
colorTo: red
|
| 6 |
-
sdk: gradio
|
| 7 |
-
sdk_version: 5.49.1
|
| 8 |
-
app_file: app.py
|
| 9 |
-
pinned: false
|
| 10 |
-
license: apache-2.0
|
| 11 |
-
short_description: Krea 2 Turbo と Qwen-Image-Edit-2511 の生成時間・VRAM を実測比較
|
| 12 |
-
---
|
| 13 |
-
|
| 14 |
-
# Krea 2 Turbo vs Qwen-Image-Edit-2511 ベンチマーク
|
| 15 |
-
|
| 16 |
-
**これは別 Space として公開するためのディレクトリ。** メインの
|
| 17 |
-
`Qwen-Image-Edit-2511-Lora-Sheet` とは独立した Space リポジトリに push すること。
|
| 18 |
-
|
| 19 |
-
```bash
|
| 20 |
-
# 例
|
| 21 |
-
huggingface-cli repo create Krea2-vs-Qwen-Edit-Bench --type space --sdk gradio
|
| 22 |
-
cd bench && git init && git remote add origin https://huggingface.co/spaces/<user>/Krea2-vs-Qwen-Edit-Bench
|
| 23 |
-
git add . && git commit -m "init" && git push -u origin main
|
| 24 |
-
```
|
| 25 |
-
|
| 26 |
-
> ⚠️ **無料アカウントがホストできる ZeroGPU Space は最大 2 つ。**
|
| 27 |
-
> メインの Space と合わせてちょうど上限に達する。
|
| 28 |
-
|
| 29 |
-
## 何を測るか
|
| 30 |
-
|
| 31 |
-
- 1 枚あたりの生成時間 (cold = 初回 / warm = 2 回目以降の中央値)
|
| 32 |
-
- ピーク VRAM (`torch.cuda.max_memory_allocated`)
|
| 33 |
-
- 同一 seed・同一解像度での出力画像
|
| 34 |
-
|
| 35 |
-
## 公平性についての注記
|
| 36 |
-
|
| 37 |
-
**同一ワークロードの比較ではない。**
|
| 38 |
-
|
| 39 |
-
| | Krea 2 Turbo | Qwen-Image-Edit-2511 |
|
| 40 |
-
|---|---|---|
|
| 41 |
-
| stock diffusers での用途 | text-to-image のみ | 画像編集 (i2i, 多画像入力可) |
|
| 42 |
-
| パイプライン | `Krea2Pipeline` | `QwenImageEditPlusPipeline` |
|
| 43 |
-
| ステップ | 8 (TDM 蒸留), guidance 0.0 | 4 (Lightning LoRA), true_cfg 1.0 |
|
| 44 |
-
|
| 45 |
-
Krea 2 には「参照画像 1 枚から同一キャラの多視点を派生させる」機能が公式に存在しない。
|
| 46 |
-
そのため本ベンチは**各モデルが本来の用途を実行したときのコスト**を並べている。
|
| 47 |
-
|
| 48 |
-
## VRAM と ZeroGPU サイズ
|
| 49 |
-
|
| 50 |
-
bf16 での重みは概算で
|
| 51 |
-
|
| 52 |
-
- Qwen-Image-Edit-2511: transformer 40.9GB + text encoder (Qwen2.5-VL-7B) 16.6GB ≈ **57GB**
|
| 53 |
-
- Krea 2 Turbo: transformer ~24GB + text encoder (Qwen3-VL-4B) ~8GB ≈ **32GB**
|
| 54 |
-
|
| 55 |
-
合計 89GB となり、ZeroGPU の `large` (48GB) はもちろん `xlarge` (96GB) でも
|
| 56 |
-
活性値を含めると危うい。既定では**両モデルとも fp8 量子化**し `size="xlarge"` で動かす。
|
| 57 |
-
|
| 58 |
-
> `xlarge` はクォータを **2 倍**消費する。片方だけを正確に測るなら `BENCH_MODELS` で
|
| 59 |
-
> 絞ること (1 モデルなら `large` に収まり消費も半分になる)。
|
| 60 |
-
|
| 61 |
-
## 環境変数
|
| 62 |
-
|
| 63 |
-
| 変数 | 既定 | 意味 |
|
| 64 |
-
|---|---|---|
|
| 65 |
-
| `BENCH_MODELS` | `both` | `both` / `qwen` / `krea` |
|
| 66 |
-
| `BENCH_FP8` | `1` | `0` で bf16 のまま |
|
| 67 |
-
| `BENCH_SIZE` | `xlarge` | ZeroGPU の GPU サイズ |
|
| 68 |
-
| `KREA_REPO` | (なし) | Krea 2 の取得元を明示指定 |
|
| 69 |
-
|
| 70 |
-
## Krea 2 の取得について
|
| 71 |
-
|
| 72 |
-
本家 [`krea/Krea-2-Turbo`](https://huggingface.co/krea/Krea-2-Turbo) は **gated (auto)**。
|
| 73 |
-
Space の Settings で `HF_TOKEN` シークレットを設定し、モデルページで利用規約に同意しておく。
|
| 74 |
-
それを避けたい場合は非 gated のミラー (`unsloth/Krea-2-Turbo` /
|
| 75 |
-
`CalamitousFelicitousness/Krea-2-Turbo-Diffusers`) が自動でフォールバック候補になる。
|
| 76 |
-
|
| 77 |
-
### ライセンス上の注意
|
| 78 |
-
|
| 79 |
-
Krea 2 Community License は、**モデルをホストする側に入出力のセーフティ分類器の実装**を
|
| 80 |
-
求めている (NCII / CSAM 等の生成防止)。また無償の商用利用は年商 $1M 未満かつ 50 席未満に限られる。
|
| 81 |
-
|
| 82 |
-
このベンチ Space はユーザーの画像アップロードを受け付けるため、**公開運用するなら
|
| 83 |
-
この要件を検討する必要がある**。計測目的に限るなら Space を private にするのが安全。
|
| 84 |
-
|
| 85 |
-
Qwen-Image-Edit-2511 は Apache-2.0 で、この種の義務はない。
|
| 86 |
-
|
| 87 |
-
## Krea 2 の identity 編集を比較したい場合
|
| 88 |
-
|
| 89 |
-
Krea 2 で「参照画像の同一性を保った編集」を試すには、以下のいずれかが必要:
|
| 90 |
-
|
| 91 |
-
1. ComfyUI + [`conradlocke/krea2-identity-edit`](https://huggingface.co/conradlocke/krea2-identity-edit)
|
| 92 |
-
+ 専用ノードパック `ComfyUI-Krea2Edit` (標準ノードでは扱えない dual conditioning を使うため)
|
| 93 |
-
2. 非公式の diffusers 移植
|
| 94 |
-
[`huan-yin/Krea2-Identity-Edit-Diffusers`](https://github.com/huan-yin/Krea2-Identity-Edit-Diffusers)
|
| 95 |
-
(`trust_remote_code=True`, 10 step, `ref_boost` 既定 4.0)
|
| 96 |
-
|
| 97 |
-
いずれも公式サポート外で、元 LoRA のダウンロード実績もほぼ無い。モデルカード自身が
|
| 98 |
-
「特徴的な顔の骨格には弱い」「衣装の入れ替えは安定しない」と明記しており、
|
| 99 |
-
多視点にわたる同一性維持という用途では不利。
|
| 100 |
-
|
| 101 |
-
Space のビルドを壊すリスクがあるため `requirements.txt` には含めていない。
|
| 102 |
-
試す場合は手動で追加すること。
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
bench/app.py
DELETED
|
@@ -1,288 +0,0 @@
|
|
| 1 |
-
"""Krea 2 Turbo vs Qwen-Image-Edit-2511 の実測ベンチマーク Space.
|
| 2 |
-
|
| 3 |
-
測るもの:
|
| 4 |
-
- 1 枚あたりの生成時間 (cold = 初回, warm = 2 回目以降の中央値)
|
| 5 |
-
- ピーク VRAM (torch.cuda.max_memory_allocated)
|
| 6 |
-
- 同一 seed / 同一解像度での出力画像
|
| 7 |
-
|
| 8 |
-
**公平性についての注記**: この 2 つは同じ土俵に乗らない。
|
| 9 |
-
Krea 2 Turbo は text-to-image 専用 (stock diffusers に編集パイプラインが無い)、
|
| 10 |
-
Qwen-Image-Edit-2511 は画像編集モデルである。そのため
|
| 11 |
-
「それぞれが本来の用途を実行したときのコスト」を測る形にしてある。
|
| 12 |
-
同一ワークロードの比較ではないので、表を読むときは注意すること。
|
| 13 |
-
|
| 14 |
-
VRAM について:
|
| 15 |
-
bf16 では Qwen 約 57GB + Krea2 約 32GB = 89GB となり、ZeroGPU の
|
| 16 |
-
`large` (48GB) はもちろん `xlarge` (96GB) でも活性値を含めると危うい。
|
| 17 |
-
既定では両モデルとも fp8 量子化し、`size="xlarge"` で動かす。
|
| 18 |
-
片方だけを正確に測りたい場合は環境変数 BENCH_MODELS で絞ること
|
| 19 |
-
(1 モデルなら `large` に収まり、クォータ消費も半分になる)。
|
| 20 |
-
|
| 21 |
-
環境変数:
|
| 22 |
-
BENCH_MODELS "both" (既定) | "qwen" | "krea"
|
| 23 |
-
BENCH_FP8 "1" (既定) で fp8 量子化。"0" で bf16
|
| 24 |
-
BENCH_SIZE "xlarge" (既定) | "large" ZeroGPU の GPU サイズ
|
| 25 |
-
KREA_REPO Krea 2 の取得元を上書き
|
| 26 |
-
"""
|
| 27 |
-
|
| 28 |
-
import os
|
| 29 |
-
import statistics
|
| 30 |
-
import time
|
| 31 |
-
from typing import Dict, List, Optional
|
| 32 |
-
|
| 33 |
-
import gradio as gr
|
| 34 |
-
import spaces
|
| 35 |
-
import torch
|
| 36 |
-
from PIL import Image
|
| 37 |
-
|
| 38 |
-
MODELS = os.environ.get("BENCH_MODELS", "both").lower()
|
| 39 |
-
USE_FP8 = os.environ.get("BENCH_FP8", "1") not in ("0", "false", "False")
|
| 40 |
-
GPU_SIZE = os.environ.get("BENCH_SIZE", "xlarge")
|
| 41 |
-
|
| 42 |
-
DTYPE = torch.bfloat16
|
| 43 |
-
DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
|
| 44 |
-
|
| 45 |
-
QWEN_REPO = "Qwen/Qwen-Image-Edit-2511"
|
| 46 |
-
QWEN_LIGHTNING_REPO = "lightx2v/Qwen-Image-Edit-2511-Lightning"
|
| 47 |
-
QWEN_LIGHTNING_WEIGHT = "Qwen-Image-Edit-2511-Lightning-4steps-V1.0-bf16.safetensors"
|
| 48 |
-
QWEN_STEPS = 4
|
| 49 |
-
QWEN_CFG = 1.0
|
| 50 |
-
|
| 51 |
-
# 本家 krea/Krea-2-Turbo は gated (auto)。Space に HF_TOKEN シークレットを設定して
|
| 52 |
-
# 利用規約に同意しておくか、非 gated のミラーを使う。
|
| 53 |
-
KREA_REPO_CANDIDATES = [
|
| 54 |
-
os.environ.get("KREA_REPO"),
|
| 55 |
-
"krea/Krea-2-Turbo",
|
| 56 |
-
"unsloth/Krea-2-Turbo",
|
| 57 |
-
"CalamitousFelicitousness/Krea-2-Turbo-Diffusers",
|
| 58 |
-
]
|
| 59 |
-
KREA_STEPS = 8
|
| 60 |
-
KREA_GUIDANCE = 0.0
|
| 61 |
-
|
| 62 |
-
LOAD_NOTES: List[str] = []
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
def _quantize(module) -> bool:
|
| 66 |
-
if not USE_FP8:
|
| 67 |
-
return False
|
| 68 |
-
try:
|
| 69 |
-
from torchao.quantization import Float8DynamicActivationFloat8WeightConfig, quantize_
|
| 70 |
-
|
| 71 |
-
quantize_(module, Float8DynamicActivationFloat8WeightConfig())
|
| 72 |
-
return True
|
| 73 |
-
except Exception as exc: # noqa: BLE001
|
| 74 |
-
LOAD_NOTES.append(f"fp8 量子化に失敗 (bf16 で継続): {exc}")
|
| 75 |
-
return False
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
def _load_qwen():
|
| 79 |
-
from diffusers import QwenImageEditPlusPipeline
|
| 80 |
-
|
| 81 |
-
pipe = QwenImageEditPlusPipeline.from_pretrained(QWEN_REPO, torch_dtype=DTYPE).to(DEVICE)
|
| 82 |
-
pipe.load_lora_weights(QWEN_LIGHTNING_REPO, weight_name=QWEN_LIGHTNING_WEIGHT)
|
| 83 |
-
pipe.fuse_lora(lora_scale=1.0)
|
| 84 |
-
pipe.unload_lora_weights()
|
| 85 |
-
_quantize(pipe.transformer)
|
| 86 |
-
return pipe
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
def _load_krea():
|
| 90 |
-
try:
|
| 91 |
-
from diffusers import Krea2Pipeline
|
| 92 |
-
except ImportError as exc:
|
| 93 |
-
LOAD_NOTES.append(
|
| 94 |
-
"Krea2Pipeline を import できませんでした。diffusers 0.39.0 以上が必要です "
|
| 95 |
-
f"({exc})"
|
| 96 |
-
)
|
| 97 |
-
return None
|
| 98 |
-
|
| 99 |
-
last_error: Optional[Exception] = None
|
| 100 |
-
for repo in [r for r in KREA_REPO_CANDIDATES if r]:
|
| 101 |
-
try:
|
| 102 |
-
pipe = Krea2Pipeline.from_pretrained(repo, torch_dtype=DTYPE).to(DEVICE)
|
| 103 |
-
_quantize(pipe.transformer)
|
| 104 |
-
LOAD_NOTES.append(f"Krea 2 Turbo を `{repo}` から読み込み")
|
| 105 |
-
return pipe
|
| 106 |
-
except Exception as exc: # noqa: BLE001
|
| 107 |
-
last_error = exc
|
| 108 |
-
LOAD_NOTES.append(f"`{repo}` の読み込みに失敗: {type(exc).__name__}")
|
| 109 |
-
LOAD_NOTES.append(
|
| 110 |
-
"Krea 2 Turbo を読み込めませんでした。本家 `krea/Krea-2-Turbo` は gated のため、"
|
| 111 |
-
"Space の Settings で HF_TOKEN シークレットを設定し、モデルページで利用規約に"
|
| 112 |
-
f"同意してください。最後のエラー: {last_error}"
|
| 113 |
-
)
|
| 114 |
-
return None
|
| 115 |
-
|
| 116 |
-
|
| 117 |
-
qwen_pipe = _load_qwen() if MODELS in ("both", "qwen") else None
|
| 118 |
-
krea_pipe = _load_krea() if MODELS in ("both", "krea") else None
|
| 119 |
-
|
| 120 |
-
|
| 121 |
-
# --- 計測 -------------------------------------------------------------------
|
| 122 |
-
|
| 123 |
-
|
| 124 |
-
def _measure(fn, runs: int) -> Dict:
|
| 125 |
-
"""fn を runs 回実行し、時間とピーク VRAM を記録する。"""
|
| 126 |
-
torch.cuda.reset_peak_memory_stats()
|
| 127 |
-
timings: List[float] = []
|
| 128 |
-
image = None
|
| 129 |
-
for _ in range(runs):
|
| 130 |
-
torch.cuda.synchronize()
|
| 131 |
-
t0 = time.perf_counter()
|
| 132 |
-
image = fn()
|
| 133 |
-
torch.cuda.synchronize()
|
| 134 |
-
timings.append(time.perf_counter() - t0)
|
| 135 |
-
return {
|
| 136 |
-
"image": image,
|
| 137 |
-
"cold": timings[0],
|
| 138 |
-
"warm": statistics.median(timings[1:]) if len(timings) > 1 else timings[0],
|
| 139 |
-
"all": timings,
|
| 140 |
-
"peak_vram_gb": torch.cuda.max_memory_allocated() / (1024**3),
|
| 141 |
-
}
|
| 142 |
-
|
| 143 |
-
|
| 144 |
-
def _bench_duration(reference, prompt, seed, width, height, runs, *args, **kwargs) -> int:
|
| 145 |
-
"""要求 duration。Krea 8 step + Qwen 4 step を runs 回ずつ。"""
|
| 146 |
-
per_run = 12 # 1 枚あたりの余裕を見た秒数
|
| 147 |
-
models = sum(1 for p in (qwen_pipe, krea_pipe) if p is not None)
|
| 148 |
-
return int(30 + per_run * max(1, runs) * max(1, models))
|
| 149 |
-
|
| 150 |
-
|
| 151 |
-
@spaces.GPU(duration=_bench_duration, size=GPU_SIZE)
|
| 152 |
-
def run_benchmark(reference, prompt, seed, width, height, runs):
|
| 153 |
-
results: Dict[str, Dict] = {}
|
| 154 |
-
|
| 155 |
-
if qwen_pipe is not None:
|
| 156 |
-
if reference is None:
|
| 157 |
-
raise RuntimeError(
|
| 158 |
-
"Qwen-Image-Edit-2511 は編集モデルなので参照画像が必要です。"
|
| 159 |
-
"画像をアップロードするか BENCH_MODELS=krea にしてください。"
|
| 160 |
-
)
|
| 161 |
-
ref = reference.convert("RGB")
|
| 162 |
-
|
| 163 |
-
def _qwen():
|
| 164 |
-
gen = torch.Generator(device=DEVICE).manual_seed(int(seed))
|
| 165 |
-
return qwen_pipe(
|
| 166 |
-
image=[ref],
|
| 167 |
-
prompt=prompt,
|
| 168 |
-
negative_prompt=" ",
|
| 169 |
-
height=int(height),
|
| 170 |
-
width=int(width),
|
| 171 |
-
num_inference_steps=QWEN_STEPS,
|
| 172 |
-
generator=gen,
|
| 173 |
-
true_cfg_scale=QWEN_CFG,
|
| 174 |
-
).images[0]
|
| 175 |
-
|
| 176 |
-
results["qwen"] = _measure(_qwen, int(runs))
|
| 177 |
-
|
| 178 |
-
if krea_pipe is not None:
|
| 179 |
-
|
| 180 |
-
def _krea():
|
| 181 |
-
gen = torch.Generator(device=DEVICE).manual_seed(int(seed))
|
| 182 |
-
return krea_pipe(
|
| 183 |
-
prompt,
|
| 184 |
-
height=int(height),
|
| 185 |
-
width=int(width),
|
| 186 |
-
num_inference_steps=KREA_STEPS,
|
| 187 |
-
guidance_scale=KREA_GUIDANCE,
|
| 188 |
-
generator=gen,
|
| 189 |
-
).images[0]
|
| 190 |
-
|
| 191 |
-
results["krea"] = _measure(_krea, int(runs))
|
| 192 |
-
|
| 193 |
-
return results
|
| 194 |
-
|
| 195 |
-
|
| 196 |
-
def _format_report(results: Dict[str, Dict], width: int, height: int, runs: int) -> str:
|
| 197 |
-
precision = "fp8 (torchao dynamic)" if USE_FP8 else "bf16"
|
| 198 |
-
lines = [
|
| 199 |
-
"## 実測結果",
|
| 200 |
-
"",
|
| 201 |
-
f"解像度 {width}×{height} / 各 {runs} 回 / 精度 {precision} / ZeroGPU size `{GPU_SIZE}`",
|
| 202 |
-
"",
|
| 203 |
-
"| モデル | モード | ステップ | cold (初回) | warm (中央値) | ピーク VRAM |",
|
| 204 |
-
"|---|---|:---:|---:|---:|---:|",
|
| 205 |
-
]
|
| 206 |
-
labels = {
|
| 207 |
-
"qwen": ("Qwen-Image-Edit-2511 + Lightning", "画像編集 (i2i)", QWEN_STEPS),
|
| 208 |
-
"krea": ("Krea 2 Turbo", "text-to-image", KREA_STEPS),
|
| 209 |
-
}
|
| 210 |
-
for key, res in results.items():
|
| 211 |
-
name, mode, steps = labels[key]
|
| 212 |
-
lines.append(
|
| 213 |
-
f"| {name} | {mode} | {steps} | {res['cold']:.2f} 秒 | "
|
| 214 |
-
f"{res['warm']:.2f} 秒 | {res['peak_vram_gb']:.1f} GB |"
|
| 215 |
-
)
|
| 216 |
-
|
| 217 |
-
lines += [
|
| 218 |
-
"",
|
| 219 |
-
"### 読み方の注意",
|
| 220 |
-
"",
|
| 221 |
-
"- **同一ワークロードの比較ではない。** Krea 2 Turbo は stock diffusers では "
|
| 222 |
-
"text-to-image 専用で、参照画像から視点を派生させる編集ができない。"
|
| 223 |
-
"ここでは各モデルが本来の用途を実行したときのコストを並べている。",
|
| 224 |
-
"- ピーク VRAM は同一プロセス内の累積値なので、2 モデルを同時に読み込んだ場合は"
|
| 225 |
-
"分離できない。正確に測るには `BENCH_MODELS` で 1 モデルに絞ること。",
|
| 226 |
-
"- cold は初回呼び出し (カーネル選択や遅延初期化を含む)、warm は 2 回目以降の中央値。",
|
| 227 |
-
]
|
| 228 |
-
if LOAD_NOTES:
|
| 229 |
-
lines += ["", "### 読み込み時のログ", ""] + [f"- {n}" for n in LOAD_NOTES]
|
| 230 |
-
return "\n".join(lines)
|
| 231 |
-
|
| 232 |
-
|
| 233 |
-
def on_run(reference, prompt, seed, width, height, runs):
|
| 234 |
-
results = run_benchmark(reference, prompt, int(seed), int(width), int(height), int(runs))
|
| 235 |
-
gallery = []
|
| 236 |
-
if "qwen" in results:
|
| 237 |
-
gallery.append((results["qwen"]["image"], "Qwen-Image-Edit-2511 (i2i, 4 step)"))
|
| 238 |
-
if "krea" in results:
|
| 239 |
-
gallery.append((results["krea"]["image"], "Krea 2 Turbo (t2i, 8 step)"))
|
| 240 |
-
return gallery, _format_report(results, int(width), int(height), int(runs))
|
| 241 |
-
|
| 242 |
-
|
| 243 |
-
# --- UI ---------------------------------------------------------------------
|
| 244 |
-
|
| 245 |
-
with gr.Blocks() as demo:
|
| 246 |
-
gr.Markdown("# Krea 2 Turbo vs Qwen-Image-Edit-2511 ベンチマーク")
|
| 247 |
-
gr.Markdown(
|
| 248 |
-
"生成時間とピーク VRAM を実測して比較します。\n\n"
|
| 249 |
-
"⚠️ **同一ワークロードの比較ではありません。** Krea 2 Turbo は stock diffusers では "
|
| 250 |
-
"text-to-image 専用で、参照画像から多視点を派生させる編集機能がありません。"
|
| 251 |
-
"各モデルが本来の用途を実行したときのコストを並べたものです。\n\n"
|
| 252 |
-
f"現在の設定: モデル `{MODELS}` / fp8 `{USE_FP8}` / GPU size `{GPU_SIZE}`"
|
| 253 |
-
)
|
| 254 |
-
if LOAD_NOTES:
|
| 255 |
-
gr.Markdown("**読み込み時のログ**\n\n" + "\n".join(f"- {n}" for n in LOAD_NOTES))
|
| 256 |
-
|
| 257 |
-
with gr.Row():
|
| 258 |
-
with gr.Column():
|
| 259 |
-
reference = gr.Image(label="参照画像 (Qwen の編集用)", type="pil", height=320)
|
| 260 |
-
prompt = gr.Textbox(
|
| 261 |
-
label="プロンプト (両モデル共通)",
|
| 262 |
-
value="A full-body character standing in a neutral A-pose, plain white background.",
|
| 263 |
-
lines=3,
|
| 264 |
-
)
|
| 265 |
-
with gr.Row():
|
| 266 |
-
width = gr.Slider(label="幅", minimum=512, maximum=1536, step=64, value=1024)
|
| 267 |
-
height = gr.Slider(label="高さ", minimum=512, maximum=1536, step=64, value=1024)
|
| 268 |
-
with gr.Row():
|
| 269 |
-
seed = gr.Number(label="Seed", value=42, precision=0)
|
| 270 |
-
runs = gr.Slider(
|
| 271 |
-
label="計測回数 (1回目は cold として別集計)",
|
| 272 |
-
minimum=1, maximum=5, step=1, value=3,
|
| 273 |
-
)
|
| 274 |
-
run_button = gr.Button("⏱️ ベンチマーク実行", variant="primary")
|
| 275 |
-
|
| 276 |
-
with gr.Column():
|
| 277 |
-
gallery = gr.Gallery(label="出力", columns=2, height=420, object_fit="contain")
|
| 278 |
-
report = gr.Markdown()
|
| 279 |
-
|
| 280 |
-
run_button.click(
|
| 281 |
-
fn=on_run,
|
| 282 |
-
inputs=[reference, prompt, seed, width, height, runs],
|
| 283 |
-
outputs=[gallery, report],
|
| 284 |
-
)
|
| 285 |
-
|
| 286 |
-
|
| 287 |
-
if __name__ == "__main__":
|
| 288 |
-
demo.launch()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
bench/requirements.txt
DELETED
|
@@ -1,20 +0,0 @@
|
|
| 1 |
-
# Krea2Pipeline は diffusers 0.39.0 で追加された。それ未満だと import できない。
|
| 2 |
-
--extra-index-url https://download.pytorch.org/whl/cu130
|
| 3 |
-
torch==2.11.0
|
| 4 |
-
torchvision==0.26.0
|
| 5 |
-
transformers==5.14.1
|
| 6 |
-
accelerate==1.14.0
|
| 7 |
-
diffusers==0.39.0
|
| 8 |
-
peft==0.19.1
|
| 9 |
-
huggingface-hub==1.24.0
|
| 10 |
-
spaces==0.51.1
|
| 11 |
-
torchao==0.16.0
|
| 12 |
-
safetensors
|
| 13 |
-
sentencepiece
|
| 14 |
-
pillow
|
| 15 |
-
|
| 16 |
-
# 注記: Krea 2 の identity 編集を比較したい場合は、非公式の diffusers 移植
|
| 17 |
-
# pip install git+https://github.com/huan-yin/Krea2-Identity-Edit-Diffusers
|
| 18 |
-
# を追加する。ただし trust_remote_code が必要で、元になる LoRA
|
| 19 |
-
# (conradlocke/krea2-identity-edit) はダウンロード実績がほぼ無く未検証。
|
| 20 |
-
# Space のビルドを壊すおそれがあるため、既定では含めていない。
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
benchmark_local.py
ADDED
|
@@ -0,0 +1,415 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Calibrate the eleven-view Turbo workflow on a local CUDA GPU.
|
| 2 |
+
|
| 3 |
+
No Spaces/Gradio import, quota timer, or captions are used. The angle LoRA is off
|
| 4 |
+
by default and can be enabled for a comparison using an existing --image. An omitted
|
| 5 |
+
--image uses the bundled mannequin for a speed smoke test only; --create-sample
|
| 6 |
+
first generates a synthetic character reference with the same loaded model. A memory limit
|
| 7 |
+
caps PyTorch's allocator; it does not emulate MIG, half a GPU, or ZeroGPU latency.
|
| 8 |
+
"""
|
| 9 |
+
import argparse
|
| 10 |
+
from datetime import datetime, timezone
|
| 11 |
+
import importlib.metadata
|
| 12 |
+
import json
|
| 13 |
+
import math
|
| 14 |
+
from pathlib import Path
|
| 15 |
+
import sys
|
| 16 |
+
import time
|
| 17 |
+
|
| 18 |
+
from PIL import Image
|
| 19 |
+
|
| 20 |
+
from core import prepare_reference, conditioning_reference, rgb_on_white
|
| 21 |
+
from pose_guides import get_guide
|
| 22 |
+
from views import BY_KEY, DEFAULT_KEYS, SIZES, make_prompt, PROMPT_VERSION, REFERENCE_RESOLUTION
|
| 23 |
+
|
| 24 |
+
# Keep in sync with backend.py without importing its ZeroGPU startup code.
|
| 25 |
+
MODEL_ID = "Qwen/Qwen-Image-2.1-Turbo"
|
| 26 |
+
MODEL_REVISION = "d65dbc9a7e8f6b5479e33dee6030eaab2a906509"
|
| 27 |
+
ANGLES_REPO = "akhaliq/Qwen-Image-2.1-Multiple-Angles-LoRA"
|
| 28 |
+
ANGLES_WEIGHT = ("checkpoints_v2/angles_v2_full_qwen21_multiple_angles_v2_"
|
| 29 |
+
"qwen21_multiple_angles_v2_000001500.safetensors")
|
| 30 |
+
ANGLES_STRENGTH = 0.8
|
| 31 |
+
GIB = 1024**3
|
| 32 |
+
SAMPLE_SEED = 20261012
|
| 33 |
+
SAMPLE_PROMPT = (
|
| 34 |
+
"A single clean anime-style character illustration of a clearly adult woman in her late twenties, "
|
| 35 |
+
"full body, straight front view at eye level, standing in a relaxed neutral A-pose with her hands "
|
| 36 |
+
"lowered and legs narrowly spaced. Short teal bob haircut ending at her jaw, straight bangs, "
|
| 37 |
+
"amber eyes and a calm neutral expression. She wears a bright orange hip-length zip-front jacket "
|
| 38 |
+
"with a large cobalt-blue rectangular patch on the left chest and a yellow stripe around the "
|
| 39 |
+
"right forearm, a cream crew-neck shirt, straight dark navy trousers, and white ankle boots "
|
| 40 |
+
"with black soles. Opaque everyday clothing, natural adult proportions, clearly defined clothing "
|
| 41 |
+
"seams and consistent flat colors with restrained cel shading. Show the complete top of her "
|
| 42 |
+
"head and both boots with generous margins. Plain white background, soft even lighting. "
|
| 43 |
+
"One character only, no text, no letters, no logo, no reference panels, no collage."
|
| 44 |
+
)
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def positive_int(value):
|
| 48 |
+
number = int(value)
|
| 49 |
+
if number < 1:
|
| 50 |
+
raise argparse.ArgumentTypeError("must be at least 1")
|
| 51 |
+
return number
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
def positive_float(value):
|
| 55 |
+
number = float(value)
|
| 56 |
+
if not math.isfinite(number) or number <= 0:
|
| 57 |
+
raise argparse.ArgumentTypeError("must be a finite number greater than 0")
|
| 58 |
+
return number
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
def parse_args(argv=None):
|
| 62 |
+
parser = argparse.ArgumentParser(description=__doc__)
|
| 63 |
+
source = parser.add_mutually_exclusive_group()
|
| 64 |
+
source.add_argument("--image", type=Path,
|
| 65 |
+
help="Character reference. Omit both source options for mannequin-only speed smoke test.")
|
| 66 |
+
source.add_argument("--create-sample", action="store_true",
|
| 67 |
+
help="Generate a synthetic adult anime character reference with the same loaded Turbo model.")
|
| 68 |
+
parser.add_argument("--output-dir", type=Path, required=True,
|
| 69 |
+
help="Save PNGs and metrics.json here; existing metrics are never overwritten.")
|
| 70 |
+
parser.add_argument("--resolution", choices=tuple(SIZES), default="fast")
|
| 71 |
+
parser.add_argument("--pose-guides", choices=("on", "off"), default="on")
|
| 72 |
+
parser.add_argument("--reference-crop", choices=("on", "off"), default="off",
|
| 73 |
+
help="Use close-view crops only for an upright full-body reference on white.")
|
| 74 |
+
parser.add_argument("--angles-lora", choices=("on", "off"), default="off",
|
| 75 |
+
help="Compare the optional Qwen2.1 angle adapter at strength0.8. Requires --image.")
|
| 76 |
+
parser.add_argument("--repeat", type=positive_int, default=1,
|
| 77 |
+
help="Number of complete eleven-view batches (default: 1).")
|
| 78 |
+
parser.add_argument("--warmup", type=int, choices=(0, 1), default=0,
|
| 79 |
+
help="Optionally generate one extra front view before the measured batches. "
|
| 80 |
+
"Its time, memory and image are also recorded (default: 0).")
|
| 81 |
+
parser.add_argument("--memory-limit-gib", type=positive_float,
|
| 82 |
+
help="PyTorch allocator cap in GiB, e.g. 48. This is not a MIG/compute cap.")
|
| 83 |
+
parser.add_argument("--seed", type=int, default=0,
|
| 84 |
+
help="Base seed; each view adds its fixed index, identical across repeats.")
|
| 85 |
+
args = parser.parse_args(argv)
|
| 86 |
+
if args.angles_lora == "on" and not args.image:
|
| 87 |
+
parser.error("--angles-lora on requires --image; reuse an existing reference "
|
| 88 |
+
"instead of --create-sample for a comparable source image")
|
| 89 |
+
return args
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
def write_metrics(path, metrics):
|
| 93 |
+
"""Replace the JSON atomically, retaining completed results after a late error."""
|
| 94 |
+
temporary = path.with_suffix(".json.tmp")
|
| 95 |
+
temporary.write_text(json.dumps(metrics, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
| 96 |
+
temporary.replace(path)
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
def cuda_memory(torch):
|
| 100 |
+
return {
|
| 101 |
+
"allocated_gib": round(torch.cuda.memory_allocated() / GIB, 4),
|
| 102 |
+
"reserved_gib": round(torch.cuda.memory_reserved() / GIB, 4),
|
| 103 |
+
"peak_allocated_gib": round(torch.cuda.max_memory_allocated() / GIB, 4),
|
| 104 |
+
"peak_reserved_gib": round(torch.cuda.max_memory_reserved() / GIB, 4),
|
| 105 |
+
}
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
def package_versions():
|
| 109 |
+
versions = {}
|
| 110 |
+
for name in ("torch", "diffusers", "transformers", "accelerate", "peft", "pillow"):
|
| 111 |
+
try:
|
| 112 |
+
versions[name] = importlib.metadata.version(name)
|
| 113 |
+
except importlib.metadata.PackageNotFoundError:
|
| 114 |
+
versions[name] = None
|
| 115 |
+
return versions
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
def benchmark(args):
|
| 119 |
+
output_dir = args.output_dir.expanduser().resolve()
|
| 120 |
+
output_dir.mkdir(parents=True, exist_ok=True)
|
| 121 |
+
metrics_path = output_dir / "metrics.json"
|
| 122 |
+
if metrics_path.exists():
|
| 123 |
+
raise FileExistsError(f"{metrics_path} already exists; choose a new --output-dir")
|
| 124 |
+
|
| 125 |
+
pose_enabled = args.pose_guides == "on"
|
| 126 |
+
angles_enabled = args.angles_lora == "on"
|
| 127 |
+
metrics = {
|
| 128 |
+
"status": "running",
|
| 129 |
+
"started_at_utc": datetime.now(timezone.utc).isoformat(),
|
| 130 |
+
"model": MODEL_ID,
|
| 131 |
+
"revision": MODEL_REVISION,
|
| 132 |
+
"input": str(args.image.expanduser().resolve()) if args.image else None,
|
| 133 |
+
"input_kind": ("user_reference" if args.image else
|
| 134 |
+
"synthetic_character" if args.create_sample else "mannequin_speed_smoke_only"),
|
| 135 |
+
"quality_validation": "not performed by this benchmark",
|
| 136 |
+
"resolution": args.resolution,
|
| 137 |
+
"pose_guides": pose_enabled,
|
| 138 |
+
"angles_lora": angles_enabled,
|
| 139 |
+
"prompt_version": PROMPT_VERSION,
|
| 140 |
+
"conditioning": ("original reference with white-background close-view crops v1"
|
| 141 |
+
if args.reference_crop == "on" else "original reference unchanged"),
|
| 142 |
+
"crop_close_views": args.reference_crop == "on",
|
| 143 |
+
"angles_adapter": ({"repo": ANGLES_REPO, "weight": ANGLES_WEIGHT,
|
| 144 |
+
"strength": ANGLES_STRENGTH, "adapter_name": "angles",
|
| 145 |
+
"strategy": "fuse on CPU, unload adapter, then move pipeline to CUDA"}
|
| 146 |
+
if angles_enabled else None),
|
| 147 |
+
"base_seed": args.seed,
|
| 148 |
+
"requested_views": DEFAULT_KEYS,
|
| 149 |
+
"repeat": args.repeat,
|
| 150 |
+
"warmup": args.warmup,
|
| 151 |
+
"memory_limit_gib": args.memory_limit_gib,
|
| 152 |
+
"memory_limit_scope": "PyTorch allocator only; not MIG or a compute limit. "
|
| 153 |
+
"Non-PyTorch CUDA allocations can be outside this cap.",
|
| 154 |
+
"timing_scope": "Each inference uses CUDA synchronization before and after the pipeline call; "
|
| 155 |
+
"PNG writing is excluded. Batch wall time includes saving PNGs and metrics. "
|
| 156 |
+
"Cold means the first pipeline call in this process. A synthetic reference "
|
| 157 |
+
"or warmup prewarms the pipeline before the measured edit batches. "
|
| 158 |
+
"No ZeroGPU startup, queue, transport, or quota is simulated.",
|
| 159 |
+
"pipeline": {"true_cfg_scale": 1.0, "use_kv_cache": True,
|
| 160 |
+
"output_resolution": REFERENCE_RESOLUTION[args.resolution],
|
| 161 |
+
"num_images_per_prompt": 1, "sampling": "checkpoint-configured eight sigmas"},
|
| 162 |
+
"packages": package_versions(),
|
| 163 |
+
"generations": [],
|
| 164 |
+
"batches": [],
|
| 165 |
+
"completed_images": 0,
|
| 166 |
+
}
|
| 167 |
+
write_metrics(metrics_path, metrics)
|
| 168 |
+
process_started = time.perf_counter()
|
| 169 |
+
torch = None
|
| 170 |
+
stage = "input_preparation"
|
| 171 |
+
active_generation = None
|
| 172 |
+
active_batch = None
|
| 173 |
+
pipeline_call_count = 0
|
| 174 |
+
edit_call_count = 0
|
| 175 |
+
exit_code = 0
|
| 176 |
+
try:
|
| 177 |
+
max_edge = 768 if args.resolution == "fast" else 1216
|
| 178 |
+
if args.image:
|
| 179 |
+
with Image.open(args.image.expanduser()) as source:
|
| 180 |
+
reference = prepare_reference(source, max_edge)
|
| 181 |
+
elif not args.create_sample:
|
| 182 |
+
reference = prepare_reference(get_guide("full_front", 512, 768), max_edge)
|
| 183 |
+
print("No --image: using the mannequin for a SPEED SMOKE TEST ONLY; "
|
| 184 |
+
"these images do not validate character identity or pose quality.", flush=True)
|
| 185 |
+
else:
|
| 186 |
+
reference = None
|
| 187 |
+
if reference is not None:
|
| 188 |
+
metrics["reference_size"] = list(reference.size)
|
| 189 |
+
guides = None
|
| 190 |
+
if pose_enabled:
|
| 191 |
+
guides = {key: get_guide(key, *SIZES[args.resolution][BY_KEY[key].shape])
|
| 192 |
+
for key in DEFAULT_KEYS}
|
| 193 |
+
|
| 194 |
+
stage = "cuda_initialization"
|
| 195 |
+
import torch as torch_module
|
| 196 |
+
torch = torch_module
|
| 197 |
+
if not torch.cuda.is_available():
|
| 198 |
+
raise RuntimeError("CUDA is unavailable; this benchmark requires a local CUDA GPU")
|
| 199 |
+
device = torch.cuda.current_device()
|
| 200 |
+
properties = torch.cuda.get_device_properties(device)
|
| 201 |
+
metrics["gpu"] = {"name": torch.cuda.get_device_name(device),
|
| 202 |
+
"device_index": device,
|
| 203 |
+
"total_memory_gib": round(properties.total_memory / GIB, 4),
|
| 204 |
+
"compute_capability": f"{properties.major}.{properties.minor}",
|
| 205 |
+
"torch_cuda_version": torch.version.cuda}
|
| 206 |
+
if args.memory_limit_gib is not None:
|
| 207 |
+
fraction = args.memory_limit_gib * GIB / properties.total_memory
|
| 208 |
+
if fraction > 1:
|
| 209 |
+
raise ValueError("--memory-limit-gib exceeds the selected GPU's total memory")
|
| 210 |
+
# Set before model loading or CUDA model placement.
|
| 211 |
+
torch.cuda.set_per_process_memory_fraction(fraction, device)
|
| 212 |
+
metrics["allocator_fraction"] = fraction
|
| 213 |
+
print(f"PyTorch allocator cap: {args.memory_limit_gib:g} GiB. "
|
| 214 |
+
"The GPU still has its full compute capacity; this is not MIG or half-GPU emulation.",
|
| 215 |
+
flush=True)
|
| 216 |
+
torch.cuda.synchronize()
|
| 217 |
+
torch.cuda.reset_peak_memory_stats()
|
| 218 |
+
write_metrics(metrics_path, metrics)
|
| 219 |
+
|
| 220 |
+
stage = "model_load"
|
| 221 |
+
from diffusers import QwenImage21Pipeline
|
| 222 |
+
load_started = time.perf_counter()
|
| 223 |
+
pipe = QwenImage21Pipeline.from_pretrained(
|
| 224 |
+
MODEL_ID, revision=MODEL_REVISION, dtype=torch.bfloat16,
|
| 225 |
+
)
|
| 226 |
+
pipe.set_progress_bar_config(disable=True)
|
| 227 |
+
if angles_enabled:
|
| 228 |
+
from huggingface_hub import hf_hub_download
|
| 229 |
+
from angles_adapter import load_angles_adapter
|
| 230 |
+
checkpoint = hf_hub_download(ANGLES_REPO, filename=ANGLES_WEIGHT)
|
| 231 |
+
metrics["angles_adapter"]["conversion"] = load_angles_adapter(
|
| 232 |
+
pipe, checkpoint, adapter_name="angles", strength=ANGLES_STRENGTH,
|
| 233 |
+
)
|
| 234 |
+
pipe.fuse_lora(adapter_names=["angles"])
|
| 235 |
+
pipe.unload_lora_weights()
|
| 236 |
+
pipe.vae.enable_tiling()
|
| 237 |
+
pipe.to("cuda")
|
| 238 |
+
torch.cuda.synchronize()
|
| 239 |
+
metrics["model_load_seconds"] = round(time.perf_counter() - load_started, 4)
|
| 240 |
+
metrics["model_load_scope"] = ("from_pretrained through CUDA placement; includes optional "
|
| 241 |
+
"CPU adapter fusion and downloads if uncached")
|
| 242 |
+
metrics["model_load_memory"] = cuda_memory(torch)
|
| 243 |
+
sample_sigmas = pipe.config.get("sample_sigmas", [])
|
| 244 |
+
if len(sample_sigmas) != 8:
|
| 245 |
+
raise RuntimeError("The pinned Turbo checkpoint's eight-sigma sampling schedule was not loaded")
|
| 246 |
+
metrics["sample_sigmas"] = list(sample_sigmas)
|
| 247 |
+
metrics["peak_allocated_gib"] = metrics["model_load_memory"]["peak_allocated_gib"]
|
| 248 |
+
metrics["peak_reserved_gib"] = metrics["model_load_memory"]["peak_reserved_gib"]
|
| 249 |
+
print(f"Loaded {metrics['gpu']['name']} in {metrics['model_load_seconds']:.3f}s; "
|
| 250 |
+
f"model allocation {metrics['model_load_memory']['allocated_gib']:.2f} GiB.", flush=True)
|
| 251 |
+
write_metrics(metrics_path, metrics)
|
| 252 |
+
|
| 253 |
+
if args.create_sample:
|
| 254 |
+
stage = "sample_generation"
|
| 255 |
+
active_generation = {
|
| 256 |
+
"phase": "sample_reference", "key": "reference", "status": "running",
|
| 257 |
+
"seed": SAMPLE_SEED, "prompt": SAMPLE_PROMPT,
|
| 258 |
+
"width": 832, "height": 1216, "output_resolution": 1024,
|
| 259 |
+
"references": 0, "cache_state": "cold", "is_first_pipeline_call": True,
|
| 260 |
+
"is_first_edit": False, "pipeline_call_index": 1,
|
| 261 |
+
}
|
| 262 |
+
metrics["sample_generation"] = active_generation
|
| 263 |
+
metrics["active_generation"] = active_generation
|
| 264 |
+
write_metrics(metrics_path, metrics)
|
| 265 |
+
torch.cuda.synchronize()
|
| 266 |
+
torch.cuda.reset_peak_memory_stats()
|
| 267 |
+
sample_started = time.perf_counter()
|
| 268 |
+
pipeline_call_count += 1
|
| 269 |
+
sample_image = pipe(
|
| 270 |
+
prompt=SAMPLE_PROMPT, width=832, height=1216, output_resolution=1024,
|
| 271 |
+
true_cfg_scale=1.0, use_kv_cache=True, num_images_per_prompt=1,
|
| 272 |
+
generator=torch.Generator("cpu").manual_seed(SAMPLE_SEED),
|
| 273 |
+
).images[0]
|
| 274 |
+
torch.cuda.synchronize()
|
| 275 |
+
sample_seconds = round(time.perf_counter() - sample_started, 4)
|
| 276 |
+
active_generation["seconds"] = sample_seconds
|
| 277 |
+
active_generation.update(cuda_memory(torch))
|
| 278 |
+
stage = "sample_save"
|
| 279 |
+
rgb_on_white(sample_image).save(output_dir / "reference.png", format="PNG")
|
| 280 |
+
active_generation["image"] = "reference.png"
|
| 281 |
+
active_generation["status"] = "complete"
|
| 282 |
+
metrics["sample_generation_seconds"] = sample_seconds
|
| 283 |
+
metrics["cold_generation"] = dict(active_generation)
|
| 284 |
+
metrics["first_pipeline_generation"] = dict(active_generation)
|
| 285 |
+
for field in ("peak_allocated_gib", "peak_reserved_gib"):
|
| 286 |
+
metrics[field] = max(metrics[field], active_generation[field])
|
| 287 |
+
reference = prepare_reference(sample_image, max_edge)
|
| 288 |
+
metrics["reference_size"] = list(reference.size)
|
| 289 |
+
metrics["input"] = "reference.png"
|
| 290 |
+
metrics.pop("active_generation", None)
|
| 291 |
+
active_generation = None
|
| 292 |
+
write_metrics(metrics_path, metrics)
|
| 293 |
+
print(f"Synthetic reference: {sample_seconds:.3f}s; saved reference.png. "
|
| 294 |
+
"This time is separate from edit batches; image quality has not been validated.", flush=True)
|
| 295 |
+
|
| 296 |
+
def generate(key, *, phase, repeat_index):
|
| 297 |
+
nonlocal stage, active_generation, pipeline_call_count, edit_call_count
|
| 298 |
+
view = BY_KEY[key]
|
| 299 |
+
width, height = SIZES[args.resolution][view.shape]
|
| 300 |
+
inputs = [conditioning_reference(reference, key, width, height)
|
| 301 |
+
if args.reference_crop == "on" else reference]
|
| 302 |
+
if guides is not None:
|
| 303 |
+
inputs.append(guides[key])
|
| 304 |
+
seed = (args.seed + DEFAULT_KEYS.index(key)) % (2**31)
|
| 305 |
+
directory = output_dir / ("warmup" if phase == "warmup" else f"run_{repeat_index:02d}")
|
| 306 |
+
directory.mkdir(exist_ok=True)
|
| 307 |
+
target = directory / f"{DEFAULT_KEYS.index(key) + 1:02d}_{key}.png"
|
| 308 |
+
active_generation = {"key": key, "phase": phase, "repeat_index": repeat_index,
|
| 309 |
+
"cache_state": "cold" if pipeline_call_count == 0 else "warm",
|
| 310 |
+
"is_first_pipeline_call": pipeline_call_count == 0,
|
| 311 |
+
"is_first_edit": edit_call_count == 0,
|
| 312 |
+
"pipeline_call_index": pipeline_call_count + 1,
|
| 313 |
+
"seed": seed, "width": width, "height": height,
|
| 314 |
+
"references": len(inputs), "status": "running"}
|
| 315 |
+
metrics["active_generation"] = active_generation
|
| 316 |
+
write_metrics(metrics_path, metrics)
|
| 317 |
+
stage = "generation"
|
| 318 |
+
torch.cuda.synchronize()
|
| 319 |
+
torch.cuda.reset_peak_memory_stats()
|
| 320 |
+
inference_started = time.perf_counter()
|
| 321 |
+
pipeline_call_count += 1
|
| 322 |
+
edit_call_count += 1
|
| 323 |
+
# Match backend.py. No budget callback: calibration must attempt all eleven views.
|
| 324 |
+
edit_prompt = make_prompt(view, "", pose_enabled, angles_enabled)
|
| 325 |
+
active_generation["prompt"] = edit_prompt
|
| 326 |
+
image = pipe(
|
| 327 |
+
image=inputs, prompt=edit_prompt,
|
| 328 |
+
width=width, height=height,
|
| 329 |
+
output_resolution=REFERENCE_RESOLUTION[args.resolution],
|
| 330 |
+
true_cfg_scale=1.0, use_kv_cache=True, num_images_per_prompt=1,
|
| 331 |
+
generator=torch.Generator("cpu").manual_seed(seed),
|
| 332 |
+
).images[0]
|
| 333 |
+
torch.cuda.synchronize()
|
| 334 |
+
active_generation["seconds"] = round(time.perf_counter() - inference_started, 4)
|
| 335 |
+
active_generation.update(cuda_memory(torch))
|
| 336 |
+
stage = "image_save"
|
| 337 |
+
rgb_on_white(image).save(target, format="PNG")
|
| 338 |
+
active_generation["image"] = str(target.relative_to(output_dir))
|
| 339 |
+
active_generation["status"] = "complete"
|
| 340 |
+
metrics["generations"].append(active_generation)
|
| 341 |
+
if active_generation["cache_state"] == "cold":
|
| 342 |
+
metrics["cold_generation"] = dict(active_generation)
|
| 343 |
+
if active_generation["is_first_pipeline_call"]:
|
| 344 |
+
metrics["first_pipeline_generation"] = dict(active_generation)
|
| 345 |
+
if active_generation["is_first_edit"]:
|
| 346 |
+
metrics["first_edit_generation"] = dict(active_generation)
|
| 347 |
+
for field in ("peak_allocated_gib", "peak_reserved_gib"):
|
| 348 |
+
metrics[field] = max(metrics[field], active_generation[field])
|
| 349 |
+
metrics["completed_images"] += 1
|
| 350 |
+
if phase == "batch":
|
| 351 |
+
active_batch["completed_views"].append(key)
|
| 352 |
+
active_batch["inference_seconds"] = round(
|
| 353 |
+
active_batch["inference_seconds"] + active_generation["seconds"], 4)
|
| 354 |
+
metrics.pop("active_generation", None)
|
| 355 |
+
completed = active_generation
|
| 356 |
+
active_generation = None
|
| 357 |
+
write_metrics(metrics_path, metrics)
|
| 358 |
+
print(f"{phase} {repeat_index or '-'} / {key}: {completed['seconds']:.3f}s, "
|
| 359 |
+
f"peak allocated {completed['peak_allocated_gib']:.2f} GiB, "
|
| 360 |
+
f"peak reserved {completed['peak_reserved_gib']:.2f} GiB "
|
| 361 |
+
f"({completed['cache_state']})", flush=True)
|
| 362 |
+
|
| 363 |
+
if args.warmup:
|
| 364 |
+
generate("full_front", phase="warmup", repeat_index=0)
|
| 365 |
+
for repeat_index in range(1, args.repeat + 1):
|
| 366 |
+
active_batch = {"repeat_index": repeat_index, "status": "running",
|
| 367 |
+
"completed_views": [], "inference_seconds": 0.0,
|
| 368 |
+
"includes_cold_generation": pipeline_call_count == 0}
|
| 369 |
+
metrics["batches"].append(active_batch)
|
| 370 |
+
batch_started = time.perf_counter()
|
| 371 |
+
for key in DEFAULT_KEYS:
|
| 372 |
+
generate(key, phase="batch", repeat_index=repeat_index)
|
| 373 |
+
active_batch["wall_seconds"] = round(time.perf_counter() - batch_started, 4)
|
| 374 |
+
active_batch["status"] = "complete"
|
| 375 |
+
print(f"Batch {repeat_index}: 11/11 views, inference "
|
| 376 |
+
f"{active_batch['inference_seconds']:.3f}s, wall {active_batch['wall_seconds']:.3f}s.",
|
| 377 |
+
flush=True)
|
| 378 |
+
write_metrics(metrics_path, metrics)
|
| 379 |
+
active_batch = None
|
| 380 |
+
metrics["status"] = "complete"
|
| 381 |
+
except (Exception, KeyboardInterrupt) as exc:
|
| 382 |
+
exit_code = 130 if isinstance(exc, KeyboardInterrupt) else 1
|
| 383 |
+
metrics["status"] = "interrupted" if exit_code == 130 else "failed"
|
| 384 |
+
metrics["error"] = {"stage": stage, "type": type(exc).__name__, "message": str(exc)}
|
| 385 |
+
if active_generation is not None:
|
| 386 |
+
active_generation["status"] = metrics["status"]
|
| 387 |
+
if active_batch is not None:
|
| 388 |
+
active_batch["status"] = metrics["status"]
|
| 389 |
+
active_batch["wall_seconds"] = round(time.perf_counter() - batch_started, 4)
|
| 390 |
+
if torch is not None:
|
| 391 |
+
try:
|
| 392 |
+
metrics["memory_at_failure"] = cuda_memory(torch)
|
| 393 |
+
except Exception:
|
| 394 |
+
pass
|
| 395 |
+
print(f"Benchmark {metrics['status']} during {stage}: {type(exc).__name__}: {exc}\n"
|
| 396 |
+
"Completed PNGs and metrics are retained.", file=sys.stderr, flush=True)
|
| 397 |
+
finally:
|
| 398 |
+
metrics["process_seconds"] = round(time.perf_counter() - process_started, 4)
|
| 399 |
+
metrics["finished_at_utc"] = datetime.now(timezone.utc).isoformat()
|
| 400 |
+
write_metrics(metrics_path, metrics)
|
| 401 |
+
print(f"Metrics: {metrics_path}", flush=True)
|
| 402 |
+
return exit_code
|
| 403 |
+
|
| 404 |
+
|
| 405 |
+
def main(argv=None):
|
| 406 |
+
args = parse_args(argv)
|
| 407 |
+
try:
|
| 408 |
+
return benchmark(args)
|
| 409 |
+
except (OSError, ValueError) as exc:
|
| 410 |
+
print(f"Cannot start benchmark: {exc}", file=sys.stderr)
|
| 411 |
+
return 1
|
| 412 |
+
|
| 413 |
+
|
| 414 |
+
if __name__ == "__main__":
|
| 415 |
+
raise SystemExit(main())
|
core.py
ADDED
|
@@ -0,0 +1,151 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""CPU-side dataset export and time-budget orchestration; independently testable."""
|
| 2 |
+
import io
|
| 3 |
+
import tempfile
|
| 4 |
+
import time
|
| 5 |
+
import zipfile
|
| 6 |
+
from dataclasses import dataclass, field
|
| 7 |
+
from pathlib import Path
|
| 8 |
+
|
| 9 |
+
from PIL import Image, ImageChops, ImageOps
|
| 10 |
+
|
| 11 |
+
from views import BY_KEY, DEFAULT_KEYS, SIZES, make_prompt, validate_keys
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
class BudgetExhausted(Exception):
|
| 15 |
+
pass
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
@dataclass
|
| 19 |
+
class BatchResult:
|
| 20 |
+
images: dict = field(default_factory=dict)
|
| 21 |
+
timings: list = field(default_factory=list)
|
| 22 |
+
stop_reason: str = ""
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
def rgb_on_white(image):
|
| 26 |
+
"""Return an independent RGB image, compositing any transparency onto white."""
|
| 27 |
+
rgba = image.convert("RGBA")
|
| 28 |
+
white = Image.new("RGBA", rgba.size, "white")
|
| 29 |
+
white.alpha_composite(rgba)
|
| 30 |
+
return white.convert("RGB")
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
def prepare_reference(image, max_edge):
|
| 34 |
+
image = ImageOps.exif_transpose(image)
|
| 35 |
+
result = rgb_on_white(image)
|
| 36 |
+
result.thumbnail((max_edge, max_edge), Image.Resampling.LANCZOS)
|
| 37 |
+
return result
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
def conditioning_reference(reference, key, width, height):
|
| 41 |
+
"""Crop close views from an upright full-body reference on a white background.
|
| 42 |
+
|
| 43 |
+
Fractions are measured from the detected foreground's head to feet. Crops are
|
| 44 |
+
derived independently from the original reference, with a small head margin,
|
| 45 |
+
and fitted proportionally onto a white canvas at the requested output size.
|
| 46 |
+
Full-body/pose views preserve the original reference object unchanged.
|
| 47 |
+
"""
|
| 48 |
+
fraction = {"cowboy_front": 0.72, "cowboy_back": 0.72,
|
| 49 |
+
"upper_front": 0.45, "face_front": 0.20}.get(key)
|
| 50 |
+
if fraction is None:
|
| 51 |
+
return reference
|
| 52 |
+
if width <= 0 or height <= 0:
|
| 53 |
+
raise ValueError("Conditioning dimensions must be positive")
|
| 54 |
+
rgb = rgb_on_white(reference)
|
| 55 |
+
difference = ImageChops.difference(rgb, Image.new("RGB", rgb.size, "white"))
|
| 56 |
+
red, green, blue = difference.split()
|
| 57 |
+
distance = ImageChops.lighter(ImageChops.lighter(red, green), blue)
|
| 58 |
+
mask = distance.point(lambda value: 255 if value > 18 else 0)
|
| 59 |
+
bbox = mask.getbbox() or (0, 0, rgb.width, rgb.height)
|
| 60 |
+
subject_height = bbox[3] - bbox[1]
|
| 61 |
+
keep_height = max(1, round(subject_height * fraction))
|
| 62 |
+
top_padding = max(1, round(keep_height * 0.06))
|
| 63 |
+
top = max(0, bbox[1] - top_padding)
|
| 64 |
+
bottom = min(rgb.height, bbox[1] + keep_height)
|
| 65 |
+
|
| 66 |
+
# Use this band's foreground width so the full body's arms/legs do not force
|
| 67 |
+
# excess whitespace around a face crop. Preserve a small horizontal margin.
|
| 68 |
+
band_bbox = mask.crop((0, top, rgb.width, bottom)).getbbox()
|
| 69 |
+
left, right = (band_bbox[0], band_bbox[2]) if band_bbox else (bbox[0], bbox[2])
|
| 70 |
+
side_padding = max(1, round((right - left) * 0.06))
|
| 71 |
+
crop = rgb.crop((max(0, left - side_padding), top,
|
| 72 |
+
min(rgb.width, right + side_padding), bottom))
|
| 73 |
+
fitted = ImageOps.contain(crop, (width, height), Image.Resampling.LANCZOS)
|
| 74 |
+
canvas = Image.new("RGB", (width, height), "white")
|
| 75 |
+
canvas.paste(fitted, ((width - fitted.width) // 2, (height - fitted.height) // 2))
|
| 76 |
+
return canvas
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
def requested_seconds(keys, maximum=110):
|
| 80 |
+
"""An execution budget, NOT a benchmark-based estimate or a guarantee."""
|
| 81 |
+
# Even a one-view smoke test needs startup and decode time in addition to
|
| 82 |
+
# the denoising budget. Keep a practical floor without claiming a speed.
|
| 83 |
+
return min(maximum, max(45, 15 + 10 * len(validate_keys(keys))))
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
def run_batch(generate_one, reference, keys, guide_images, resolution, seed, extra,
|
| 87 |
+
angles, budget_seconds, clock=time.monotonic, crop_close_views=False):
|
| 88 |
+
keys = validate_keys(keys)
|
| 89 |
+
result = BatchResult()
|
| 90 |
+
started = clock()
|
| 91 |
+
deadline = started + budget_seconds
|
| 92 |
+
longest = 0.0
|
| 93 |
+
|
| 94 |
+
def check_budget():
|
| 95 |
+
# Called at denoising step boundaries. Leave room for decode and result transfer.
|
| 96 |
+
if clock() >= deadline - 6:
|
| 97 |
+
raise BudgetExhausted()
|
| 98 |
+
|
| 99 |
+
for key in keys:
|
| 100 |
+
remaining = deadline - clock()
|
| 101 |
+
if remaining <= max(8.0, longest * 1.4 + 6):
|
| 102 |
+
result.stop_reason = "時間枠に達する前に終了しました。完成した画像を保存できます。"
|
| 103 |
+
break
|
| 104 |
+
view = BY_KEY[key]
|
| 105 |
+
width, height = SIZES[resolution][view.shape]
|
| 106 |
+
inputs = [conditioning_reference(reference, key, width, height)
|
| 107 |
+
if crop_close_views else reference]
|
| 108 |
+
if guide_images is not None:
|
| 109 |
+
inputs.append(guide_images[key])
|
| 110 |
+
# Stable per-view seed, unaffected by selecting or reordering other views.
|
| 111 |
+
view_seed = (int(seed) + DEFAULT_KEYS.index(key)) % (2**31)
|
| 112 |
+
t0 = clock()
|
| 113 |
+
try:
|
| 114 |
+
output = generate_one(
|
| 115 |
+
image=inputs, prompt=make_prompt(view, extra, guide_images is not None, angles),
|
| 116 |
+
width=width, height=height, seed=view_seed, check_budget=check_budget,
|
| 117 |
+
)
|
| 118 |
+
except BudgetExhausted:
|
| 119 |
+
result.stop_reason = "時間枠に達する前に終了しました。完成した画像を保存できます。"
|
| 120 |
+
break
|
| 121 |
+
except Exception as exc:
|
| 122 |
+
# A late view failure must not discard images already completed.
|
| 123 |
+
print(f"[generation] {key} failed: {type(exc).__name__}: {exc}", flush=True)
|
| 124 |
+
result.stop_reason = f"「{view.label}」の生成に失敗しました。完成済み画像は保存できます。"
|
| 125 |
+
break
|
| 126 |
+
elapsed = clock() - t0
|
| 127 |
+
longest = max(longest, elapsed)
|
| 128 |
+
result.images[key] = output
|
| 129 |
+
result.timings.append({"key": key, "seconds": round(elapsed, 3), "seed": view_seed,
|
| 130 |
+
"width": width, "height": height, "references": len(inputs)})
|
| 131 |
+
print(f"[generation] {key}: {elapsed:.2f}s", flush=True)
|
| 132 |
+
return result
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
def build_zip(images, selected_keys, output_dir=None):
|
| 136 |
+
"""Export PNGs only; optionally write inside a caller-managed directory."""
|
| 137 |
+
keys = validate_keys(selected_keys)
|
| 138 |
+
if not any(key in images for key in keys):
|
| 139 |
+
return None
|
| 140 |
+
folder = Path(output_dir) if output_dir is not None else Path(tempfile.mkdtemp(prefix="character-views-"))
|
| 141 |
+
folder.mkdir(parents=True, exist_ok=True)
|
| 142 |
+
target = folder / "character_views.zip"
|
| 143 |
+
with zipfile.ZipFile(target, "w", zipfile.ZIP_STORED) as archive:
|
| 144 |
+
for key in keys:
|
| 145 |
+
if key not in images:
|
| 146 |
+
continue
|
| 147 |
+
buffer = io.BytesIO()
|
| 148 |
+
rgb_on_white(images[key]).save(buffer, format="PNG")
|
| 149 |
+
index = DEFAULT_KEYS.index(key) + 1
|
| 150 |
+
archive.writestr(f"dataset/{index:02d}_{key}.png", buffer.getvalue())
|
| 151 |
+
return str(target)
|
framing.py
DELETED
|
@@ -1,59 +0,0 @@
|
|
| 1 |
-
"""寄り視点用に、全身画像から目的の構図を切り出すユーティリティ.
|
| 2 |
-
|
| 3 |
-
なぜ必要か (実機検証の結果):
|
| 4 |
-
全身画像を条件にして「カウボーイショットにして」とプロンプトで頼んでも、
|
| 5 |
-
Qwen-Image-Edit は入力のフレーミングを保とうとして全身のまま出力する。
|
| 6 |
-
プロンプトの言い回しを 8 通り試しても直らなかった。
|
| 7 |
-
あらかじめ目的の構図に切り出した画像を条件にすると、フレーミングが
|
| 8 |
-
決定的に決まり、モデルはディテール補完に専念できる。
|
| 9 |
-
"""
|
| 10 |
-
|
| 11 |
-
from typing import Tuple
|
| 12 |
-
|
| 13 |
-
import numpy as np
|
| 14 |
-
from PIL import Image
|
| 15 |
-
|
| 16 |
-
#: 被写体の全高を 1.0 としたときに、頭頂から何割を残すか
|
| 17 |
-
CROP_FRACTION = {
|
| 18 |
-
"face": 0.20,
|
| 19 |
-
"upper": 0.45,
|
| 20 |
-
"cowboy": 0.72,
|
| 21 |
-
}
|
| 22 |
-
|
| 23 |
-
#: 顔が切れないように上へ足す余白 (切り出し高さに対する割合)
|
| 24 |
-
TOP_PAD_RATIO = 0.06
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
def subject_bbox(img: Image.Image, tol: int = 18) -> Tuple[int, int, int, int]:
|
| 28 |
-
"""白背景を除いた被写体のバウンディングボックス (x0, y0, x1, y1)。
|
| 29 |
-
|
| 30 |
-
背景は全視点で plain white に固定しているので、白からの距離で判定できる。
|
| 31 |
-
被写体が見つからない場合は画像全体を返す。
|
| 32 |
-
"""
|
| 33 |
-
arr = np.asarray(img.convert("RGB")).astype(np.int16)
|
| 34 |
-
mask = (255 - arr).max(axis=2) > tol
|
| 35 |
-
ys, xs = np.nonzero(mask)
|
| 36 |
-
if len(ys) == 0:
|
| 37 |
-
return (0, 0, img.width, img.height)
|
| 38 |
-
return (int(xs.min()), int(ys.min()), int(xs.max()) + 1, int(ys.max()) + 1)
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
def crop_framing(img: Image.Image, kind: str, out_w: int, out_h: int) -> Image.Image:
|
| 42 |
-
"""被写体の上から一定割合を切り出し、出力アスペクト比に合わせて整える。"""
|
| 43 |
-
if kind not in CROP_FRACTION:
|
| 44 |
-
return img
|
| 45 |
-
|
| 46 |
-
x0, y0, x1, y1 = subject_bbox(img)
|
| 47 |
-
subject_h = max(1, y1 - y0)
|
| 48 |
-
keep_h = max(8, int(subject_h * CROP_FRACTION[kind]))
|
| 49 |
-
|
| 50 |
-
cy0 = max(0, y0 - int(keep_h * TOP_PAD_RATIO))
|
| 51 |
-
cy1 = min(img.height, cy0 + keep_h)
|
| 52 |
-
|
| 53 |
-
# 出力アスペクト比に合わせて横幅を決め、被写体の水平中心に寄せる
|
| 54 |
-
need_w = max(8, int((cy1 - cy0) * (out_w / out_h)))
|
| 55 |
-
cx = (x0 + x1) // 2
|
| 56 |
-
cx0 = max(0, min(cx - need_w // 2, img.width - need_w)) if need_w <= img.width else 0
|
| 57 |
-
cx1 = min(img.width, cx0 + need_w)
|
| 58 |
-
|
| 59 |
-
return img.crop((cx0, cy0, cx1, cy1)).resize((out_w, out_h), Image.LANCZOS)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
optimization.py
DELETED
|
@@ -1,167 +0,0 @@
|
|
| 1 |
-
"""ZeroGPU 向け高速化 (fp8 量子化 + PyTorch ahead-of-time コンパイル).
|
| 2 |
-
|
| 3 |
-
tori29umai/Qwen-Image-2509-CharacterSheet の optimization.py を土台に、
|
| 4 |
-
fp8 量子化を有効化し、失敗時に素の bf16 へフォールバックする経路を足したもの。
|
| 5 |
-
|
| 6 |
-
なぜ必要か:
|
| 7 |
-
ZeroGPU は 2026/05 に H200 (~70GB) から RTX Pro 6000 Blackwell へ移行し、
|
| 8 |
-
既定の `large` サイズは 48GB になった。Qwen-Image-Edit-2511 は bf16 で
|
| 9 |
-
transformer 40.9GB + text encoder 16.6GB ≈ 57GB あり、48GB 枠に収まらない。
|
| 10 |
-
fp8 量子化で transformer を約半分に落とすことが実質的な前提条件になる。
|
| 11 |
-
|
| 12 |
-
さらに ZeroGPU はクォータを「実行時間」ではなく「要求 duration」で消費するため、
|
| 13 |
-
1 視点あたりの生成時間を削ることがそのまま無料枠での生成可能枚数に効く。
|
| 14 |
-
|
| 15 |
-
環境変数:
|
| 16 |
-
DISABLE_FP8=1 fp8 量子化を無効化 (bf16 のまま)
|
| 17 |
-
DISABLE_AOTI=1 AoTI コンパイルを無効化
|
| 18 |
-
DISABLE_FA3=1 FlashAttention-3 を無効化
|
| 19 |
-
"""
|
| 20 |
-
|
| 21 |
-
import os
|
| 22 |
-
from typing import Any, Callable, ParamSpec
|
| 23 |
-
|
| 24 |
-
import spaces
|
| 25 |
-
import torch
|
| 26 |
-
from torch.utils._pytree import tree_map
|
| 27 |
-
|
| 28 |
-
P = ParamSpec("P")
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
TRANSFORMER_IMAGE_SEQ_LENGTH_DIM = torch.export.Dim("image_seq_length")
|
| 32 |
-
TRANSFORMER_TEXT_SEQ_LENGTH_DIM = torch.export.Dim("text_seq_length")
|
| 33 |
-
|
| 34 |
-
# 画像/テキストの系列長を動的次元にしておくことで、視点ごとに解像度が変わっても
|
| 35 |
-
# (832x1216 / 1024x1024 / 1216x832) 再コンパイルが走らない。
|
| 36 |
-
TRANSFORMER_DYNAMIC_SHAPES = {
|
| 37 |
-
"hidden_states": {
|
| 38 |
-
1: TRANSFORMER_IMAGE_SEQ_LENGTH_DIM,
|
| 39 |
-
},
|
| 40 |
-
"encoder_hidden_states": {
|
| 41 |
-
1: TRANSFORMER_TEXT_SEQ_LENGTH_DIM,
|
| 42 |
-
},
|
| 43 |
-
"encoder_hidden_states_mask": {
|
| 44 |
-
1: TRANSFORMER_TEXT_SEQ_LENGTH_DIM,
|
| 45 |
-
},
|
| 46 |
-
"image_rotary_emb": (
|
| 47 |
-
{0: TRANSFORMER_IMAGE_SEQ_LENGTH_DIM},
|
| 48 |
-
{0: TRANSFORMER_TEXT_SEQ_LENGTH_DIM},
|
| 49 |
-
),
|
| 50 |
-
}
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
INDUCTOR_CONFIGS = {
|
| 54 |
-
"conv_1x1_as_mm": True,
|
| 55 |
-
"epilogue_fusion": False,
|
| 56 |
-
"coordinate_descent_tuning": True,
|
| 57 |
-
"coordinate_descent_check_all_directions": True,
|
| 58 |
-
"max_autotune": True,
|
| 59 |
-
"triton.cudagraphs": True,
|
| 60 |
-
}
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
def _env_off(name: str) -> bool:
|
| 64 |
-
return os.environ.get(name, "").strip() not in ("", "0", "false", "False")
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
def apply_fa3_(pipeline) -> bool:
|
| 68 |
-
"""FlashAttention-3 の attention processor を適用する。成功したら True。"""
|
| 69 |
-
if _env_off("DISABLE_FA3"):
|
| 70 |
-
print("[optimization] FA3 は DISABLE_FA3 により無効")
|
| 71 |
-
return False
|
| 72 |
-
try:
|
| 73 |
-
from qwenimage.qwen_fa3_processor import QwenDoubleStreamAttnProcessorFA3
|
| 74 |
-
|
| 75 |
-
pipeline.transformer.set_attn_processor(QwenDoubleStreamAttnProcessorFA3())
|
| 76 |
-
print("[optimization] FlashAttention-3 を適用")
|
| 77 |
-
return True
|
| 78 |
-
except Exception as exc: # noqa: BLE001 - Space を落とさないことを優先
|
| 79 |
-
print(f"[optimization] FA3 を適用できず既定の attention を使用: {exc}")
|
| 80 |
-
return False
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
#: 量子化は一度きり。AoTI が途中で失敗した場合にフォールバック側が二重適用しないよう記録する。
|
| 84 |
-
_FP8_APPLIED = False
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
def quantize_fp8_(module) -> bool:
|
| 88 |
-
"""transformer を fp8 動的量子化する。成功したら True。
|
| 89 |
-
|
| 90 |
-
VRAM を約半減させるのが主目的で、副次的に ~1.2x の高速化が乗る。
|
| 91 |
-
"""
|
| 92 |
-
global _FP8_APPLIED
|
| 93 |
-
if _FP8_APPLIED:
|
| 94 |
-
return True
|
| 95 |
-
if _env_off("DISABLE_FP8"):
|
| 96 |
-
print("[optimization] fp8 は DISABLE_FP8 により無効")
|
| 97 |
-
return False
|
| 98 |
-
try:
|
| 99 |
-
from torchao.quantization import (
|
| 100 |
-
Float8DynamicActivationFloat8WeightConfig,
|
| 101 |
-
quantize_,
|
| 102 |
-
)
|
| 103 |
-
|
| 104 |
-
quantize_(module, Float8DynamicActivationFloat8WeightConfig())
|
| 105 |
-
_FP8_APPLIED = True
|
| 106 |
-
print("[optimization] fp8 動的量子化を適用")
|
| 107 |
-
return True
|
| 108 |
-
except Exception as exc: # noqa: BLE001
|
| 109 |
-
print(f"[optimization] fp8 量子化に失敗、bf16 のまま継続: {exc}")
|
| 110 |
-
return False
|
| 111 |
-
|
| 112 |
-
|
| 113 |
-
def optimize_pipeline_(pipeline: Callable[P, Any], *args: P.args, **kwargs: P.kwargs) -> bool:
|
| 114 |
-
"""fp8 量子化 + AoTI コンパイルを適用する。AoTI まで通ったら True。
|
| 115 |
-
|
| 116 |
-
量子化と export は同一の GPU コンテキスト内で行う必要があるため、
|
| 117 |
-
まとめて `@spaces.GPU` 関数の中で実行する。
|
| 118 |
-
"""
|
| 119 |
-
if _env_off("DISABLE_AOTI"):
|
| 120 |
-
print("[optimization] AoTI は DISABLE_AOTI により無効")
|
| 121 |
-
if not _FP8_APPLIED:
|
| 122 |
-
# 通常は app.py 側が CPU 上で量子化済み。未適用ならここで救済する。
|
| 123 |
-
@spaces.GPU(duration=120)
|
| 124 |
-
def quantize_only():
|
| 125 |
-
return quantize_fp8_(pipeline.transformer)
|
| 126 |
-
|
| 127 |
-
quantize_only()
|
| 128 |
-
return False
|
| 129 |
-
|
| 130 |
-
@spaces.GPU(duration=1500)
|
| 131 |
-
def compile_transformer():
|
| 132 |
-
# 実入力の形状を捕まえるためにパイプラインを 1 回だけ空回しする
|
| 133 |
-
with spaces.aoti_capture(pipeline.transformer) as call:
|
| 134 |
-
pipeline(*args, **kwargs)
|
| 135 |
-
|
| 136 |
-
dynamic_shapes = tree_map(lambda t: None, call.kwargs)
|
| 137 |
-
dynamic_shapes |= TRANSFORMER_DYNAMIC_SHAPES
|
| 138 |
-
|
| 139 |
-
# 通常は app.py 側で CPU 転送前に量子化済み (_FP8_APPLIED が True なので no-op)。
|
| 140 |
-
# export より前に済んでいれば、量子化後のカーネルがグラフに焼き込まれる。
|
| 141 |
-
quantize_fp8_(pipeline.transformer)
|
| 142 |
-
|
| 143 |
-
exported = torch.export.export(
|
| 144 |
-
mod=pipeline.transformer,
|
| 145 |
-
args=call.args,
|
| 146 |
-
kwargs=call.kwargs,
|
| 147 |
-
dynamic_shapes=dynamic_shapes,
|
| 148 |
-
)
|
| 149 |
-
return spaces.aoti_compile(exported, INDUCTOR_CONFIGS)
|
| 150 |
-
|
| 151 |
-
try:
|
| 152 |
-
spaces.aoti_apply(compile_transformer(), pipeline.transformer)
|
| 153 |
-
print("[optimization] AoTI コンパイル済みの transformer を適用")
|
| 154 |
-
return True
|
| 155 |
-
except Exception as exc: # noqa: BLE001
|
| 156 |
-
# コンパイルに失敗しても Space は動き続けるべき。量子化だけでも効果はある。
|
| 157 |
-
print(f"[optimization] AoTI コンパイルに失敗、非コンパイル経路で継続: {exc}")
|
| 158 |
-
|
| 159 |
-
@spaces.GPU(duration=120)
|
| 160 |
-
def quantize_fallback():
|
| 161 |
-
return quantize_fp8_(pipeline.transformer)
|
| 162 |
-
|
| 163 |
-
try:
|
| 164 |
-
quantize_fallback()
|
| 165 |
-
except Exception as exc2: # noqa: BLE001
|
| 166 |
-
print(f"[optimization] fp8 フォールバックも失敗: {exc2}")
|
| 167 |
-
return False
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
pose_guides.py
ADDED
|
@@ -0,0 +1,330 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Deterministic, neutral pose mannequins for the eleven reference views.
|
| 2 |
+
|
| 3 |
+
These are ordinary RGB image references, not ControlNet or OpenPose maps. They
|
| 4 |
+
describe pose/camera/framing; a separate character image supplies identity.
|
| 5 |
+
No network, downloaded models, random sampling, or GPU is used. Pillow is the
|
| 6 |
+
only third-party dependency. Run ``python pose_guides.py --regenerate`` to
|
| 7 |
+
rebuild the bundled assets.
|
| 8 |
+
"""
|
| 9 |
+
|
| 10 |
+
from __future__ import annotations
|
| 11 |
+
|
| 12 |
+
import math
|
| 13 |
+
from pathlib import Path
|
| 14 |
+
|
| 15 |
+
from PIL import Image, ImageDraw, ImageFont
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
ASSET_DIR = Path(__file__).resolve().parent / "assets"
|
| 19 |
+
GUIDE_VERSION = 1
|
| 20 |
+
# key: (English preview label, pose, camera azimuth, elevation, crop, size)
|
| 21 |
+
GUIDE_SPECS = {
|
| 22 |
+
"full_front": ("01 Full / front", "standing", 0, 0, "full", (832, 1216)),
|
| 23 |
+
"full_left": ("02 Full / left", "standing", 270, 0, "full", (832, 1216)),
|
| 24 |
+
"full_right": ("03 Full / right", "standing", 90, 0, "full", (832, 1216)),
|
| 25 |
+
"full_back": ("04 Full / back", "standing", 180, 0, "full", (832, 1216)),
|
| 26 |
+
"cowboy_front": ("05 Mid-thigh / front", "standing", 0, 0, "cowboy", (1024, 1024)),
|
| 27 |
+
"cowboy_back": ("06 Mid-thigh / back", "standing", 180, 0, "cowboy", (1024, 1024)),
|
| 28 |
+
"upper_front": ("07 Upper body / front", "standing", 0, 0, "upper", (1024, 1024)),
|
| 29 |
+
"face_front": ("08 Face / front", "standing", 0, 0, "face", (1024, 1024)),
|
| 30 |
+
"knees_front": ("09 Hug knees / front", "knees", 0, 0, "full", (832, 1216)),
|
| 31 |
+
"knees_back": ("10 Hug knees / back", "knees", 180, 0, "full", (832, 1216)),
|
| 32 |
+
"prone_back": ("11 Prone / rear, elevated", "prone", 180, 60, "full", (1216, 832)),
|
| 33 |
+
}
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def _add(a, b):
|
| 37 |
+
return tuple(x + y for x, y in zip(a, b))
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
def _sub(a, b):
|
| 41 |
+
return tuple(x - y for x, y in zip(a, b))
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
def _mul(a, scale):
|
| 45 |
+
return tuple(x * scale for x in a)
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
def _dot(a, b):
|
| 49 |
+
return sum(x * y for x, y in zip(a, b))
|
| 50 |
+
|
| 51 |
+
|
| 52 |
+
def _cross(a, b):
|
| 53 |
+
return (a[1] * b[2] - a[2] * b[1],
|
| 54 |
+
a[2] * b[0] - a[0] * b[2],
|
| 55 |
+
a[0] * b[1] - a[1] * b[0])
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
def _unit(a):
|
| 59 |
+
length = math.sqrt(_dot(a, a))
|
| 60 |
+
return _mul(a, 1 / length) if length > 1e-12 else (0.0, 1.0, 0.0)
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
class _Mannequin:
|
| 64 |
+
"""Small ellipsoid mesh model with articulated limbs and subtle joints."""
|
| 65 |
+
|
| 66 |
+
def __init__(self):
|
| 67 |
+
self.faces = []
|
| 68 |
+
|
| 69 |
+
def ellipsoid(self, center, radii, tone=177, axis=(0, 1, 0), facing=None):
|
| 70 |
+
ey = _unit(axis)
|
| 71 |
+
if facing is None:
|
| 72 |
+
helper = (0, 0, 1) if abs(ey[2]) < 0.9 else (0, 1, 0)
|
| 73 |
+
ex = _unit(_cross(ey, helper))
|
| 74 |
+
ez = _unit(_cross(ex, ey))
|
| 75 |
+
else:
|
| 76 |
+
ez = _unit(facing)
|
| 77 |
+
ex = _unit(_cross(ey, ez))
|
| 78 |
+
ez = _unit(_cross(ex, ey))
|
| 79 |
+
rings, sectors = 40, 72
|
| 80 |
+
vertices = []
|
| 81 |
+
for ring in range(rings + 1):
|
| 82 |
+
latitude = math.pi * ring / rings
|
| 83 |
+
row = []
|
| 84 |
+
for sector in range(sectors):
|
| 85 |
+
longitude = 2 * math.pi * sector / sectors
|
| 86 |
+
local = (radii[0] * math.sin(latitude) * math.cos(longitude),
|
| 87 |
+
radii[1] * math.cos(latitude),
|
| 88 |
+
radii[2] * math.sin(latitude) * math.sin(longitude))
|
| 89 |
+
world = _add(center, _add(_mul(ex, local[0]),
|
| 90 |
+
_add(_mul(ey, local[1]), _mul(ez, local[2]))))
|
| 91 |
+
normal = _unit(_add(_mul(ex, local[0] / radii[0] ** 2),
|
| 92 |
+
_add(_mul(ey, local[1] / radii[1] ** 2),
|
| 93 |
+
_mul(ez, local[2] / radii[2] ** 2))))
|
| 94 |
+
row.append((world, normal))
|
| 95 |
+
vertices.append(row)
|
| 96 |
+
for ring in range(rings):
|
| 97 |
+
for sector in range(sectors):
|
| 98 |
+
next_sector = (sector + 1) % sectors
|
| 99 |
+
corners = [vertices[ring][sector], vertices[ring + 1][sector],
|
| 100 |
+
vertices[ring + 1][next_sector], vertices[ring][next_sector]]
|
| 101 |
+
points = tuple(v[0] for v in corners)
|
| 102 |
+
normal = _unit(tuple(sum(v[1][i] for v in corners) for i in range(3)))
|
| 103 |
+
self.faces.append((points, normal, tone))
|
| 104 |
+
|
| 105 |
+
def limb(self, start, end, radius, tone=178):
|
| 106 |
+
delta = _sub(end, start)
|
| 107 |
+
length = math.sqrt(_dot(delta, delta))
|
| 108 |
+
self.ellipsoid(_mul(_add(start, end), 0.5),
|
| 109 |
+
(radius, length / 2 + radius * 0.5, radius), tone, delta)
|
| 110 |
+
|
| 111 |
+
def joint(self, point, radius):
|
| 112 |
+
self.ellipsoid(point, (radius, radius, radius), 160)
|
| 113 |
+
|
| 114 |
+
def head(self, center, axis=(0, 1, 0), facing=(0, 0, 1)):
|
| 115 |
+
up, forward = _unit(axis), _unit(facing)
|
| 116 |
+
side = _unit(_cross(up, forward))
|
| 117 |
+
self.ellipsoid(center, (0.105, 0.145, 0.101), 187, up, forward)
|
| 118 |
+
# A short, blunt nose and small ears make front/back/side unambiguous.
|
| 119 |
+
nose = _add(center, _add(_mul(forward, 0.105), _mul(up, -0.01)))
|
| 120 |
+
self.ellipsoid(nose, (0.018, 0.029, 0.033), 179, up, forward)
|
| 121 |
+
for sign in (-1, 1):
|
| 122 |
+
ear = _add(center, _add(_mul(side, sign * 0.103), _mul(up, -0.005)))
|
| 123 |
+
self.ellipsoid(ear, (0.019, 0.032, 0.019), 176, up, forward)
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
def _standing():
|
| 127 |
+
model = _Mannequin()
|
| 128 |
+
model.ellipsoid((0, 1.26, 0), (0.189, 0.237, 0.103))
|
| 129 |
+
model.ellipsoid((0, 1.045, 0), (0.130, 0.129, 0.091), 172)
|
| 130 |
+
model.ellipsoid((0, 0.958, -0.002), (0.158, 0.125, 0.108), 180)
|
| 131 |
+
model.limb((0, 1.438, 0), (0, 1.536, 0), 0.052)
|
| 132 |
+
model.head((0, 1.665, 0))
|
| 133 |
+
for side in (-1, 1):
|
| 134 |
+
shoulder = (side * 0.196, 1.398, 0)
|
| 135 |
+
elbow = (side * 0.264, 1.130, 0)
|
| 136 |
+
wrist = (side * 0.309, 0.901, 0.016)
|
| 137 |
+
model.joint(shoulder, 0.071)
|
| 138 |
+
model.limb(shoulder, elbow, 0.063)
|
| 139 |
+
model.joint(elbow, 0.046)
|
| 140 |
+
model.limb(elbow, wrist, 0.047)
|
| 141 |
+
model.joint(wrist, 0.030)
|
| 142 |
+
model.ellipsoid((side * 0.319, 0.846, 0.02), (0.039, 0.069, 0.025), 183,
|
| 143 |
+
(side * 0.13, 1, 0))
|
| 144 |
+
hip = (side * 0.089, 0.920, 0)
|
| 145 |
+
knee = (side * 0.105, 0.516, 0.010)
|
| 146 |
+
ankle = (side * 0.111, 0.097, 0)
|
| 147 |
+
model.limb(hip, knee, 0.085)
|
| 148 |
+
model.joint(knee, 0.057)
|
| 149 |
+
model.limb(knee, ankle, 0.057)
|
| 150 |
+
model.joint(ankle, 0.039)
|
| 151 |
+
model.ellipsoid((side * 0.111, 0.049, 0.068), (0.059, 0.048, 0.125), 180)
|
| 152 |
+
return model
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
def _knees():
|
| 156 |
+
model = _Mannequin()
|
| 157 |
+
model.ellipsoid((0, 0.230, -0.111), (0.163, 0.135, 0.119), 180)
|
| 158 |
+
model.ellipsoid((0, 0.445, -0.148), (0.151, 0.190, 0.103), 173,
|
| 159 |
+
(0, 1, 0.10))
|
| 160 |
+
model.ellipsoid((0, 0.624, -0.096), (0.183, 0.177, 0.099), 177,
|
| 161 |
+
(0, 1, 0.24))
|
| 162 |
+
model.limb((0, 0.745, -0.065), (0, 0.823, -0.01), 0.050)
|
| 163 |
+
model.head((0, 0.939, 0.024), axis=(0, 0.99, 0.08), facing=(0, -0.08, 0.99))
|
| 164 |
+
for side in (-1, 1):
|
| 165 |
+
hip = (side * 0.105, 0.226, -0.080)
|
| 166 |
+
knee = (side * 0.116, 0.603, 0.248)
|
| 167 |
+
ankle = (side * 0.119, 0.097, 0.320)
|
| 168 |
+
model.limb(hip, knee, 0.086)
|
| 169 |
+
model.joint(knee, 0.062)
|
| 170 |
+
model.limb(knee, ankle, 0.056)
|
| 171 |
+
model.joint(ankle, 0.038)
|
| 172 |
+
model.ellipsoid((side * 0.120, 0.050, 0.383), (0.061, 0.050, 0.114), 180)
|
| 173 |
+
shoulder = (side * 0.186, 0.724, -0.064)
|
| 174 |
+
elbow = (side * 0.264, 0.465, 0.257)
|
| 175 |
+
wrist = (side * 0.085, 0.470, 0.356)
|
| 176 |
+
model.joint(shoulder, 0.063)
|
| 177 |
+
model.limb(shoulder, elbow, 0.058)
|
| 178 |
+
model.joint(elbow, 0.043)
|
| 179 |
+
model.limb(elbow, wrist, 0.043)
|
| 180 |
+
model.joint(wrist, 0.027)
|
| 181 |
+
model.ellipsoid((side * 0.037, 0.467 + side * 0.012, 0.359),
|
| 182 |
+
(0.030, 0.062, 0.023), 184, (1, side * 0.1, 0))
|
| 183 |
+
return model
|
| 184 |
+
|
| 185 |
+
|
| 186 |
+
def _prone():
|
| 187 |
+
model = _Mannequin()
|
| 188 |
+
model.ellipsoid((0, 0.178, 1.227), (0.189, 0.237, 0.103), axis=(0, 0, 1), facing=(0, -1, 0))
|
| 189 |
+
model.ellipsoid((0, 0.165, 1.021), (0.130, 0.130, 0.092), 172,
|
| 190 |
+
axis=(0, 0, 1), facing=(0, -1, 0))
|
| 191 |
+
model.ellipsoid((0, 0.182, 0.924), (0.158, 0.127, 0.111), 180,
|
| 192 |
+
axis=(0, 0, 1), facing=(0, -1, 0))
|
| 193 |
+
model.limb((0, 0.17, 1.418), (0, 0.16, 1.500), 0.052)
|
| 194 |
+
model.head((0, 0.162, 1.641), axis=(0, 0, 1), facing=(0, -1, 0))
|
| 195 |
+
for side in (-1, 1):
|
| 196 |
+
shoulder = (side * 0.195, 0.172, 1.372)
|
| 197 |
+
elbow = (side * 0.375, 0.083, 1.606)
|
| 198 |
+
wrist = (side * 0.244, 0.065, 1.797)
|
| 199 |
+
model.joint(shoulder, 0.068)
|
| 200 |
+
model.limb(shoulder, elbow, 0.060)
|
| 201 |
+
model.joint(elbow, 0.043)
|
| 202 |
+
model.limb(elbow, wrist, 0.045)
|
| 203 |
+
model.joint(wrist, 0.027)
|
| 204 |
+
model.ellipsoid((side * 0.188, 0.052, 1.823), (0.032, 0.066, 0.023), 183,
|
| 205 |
+
axis=(side, 0, -0.2), facing=(0, -1, 0))
|
| 206 |
+
hip = (side * 0.090, 0.177, 0.899)
|
| 207 |
+
knee = (side * 0.105, 0.116, 0.491)
|
| 208 |
+
ankle = (side * 0.113, 0.083, 0.098)
|
| 209 |
+
model.limb(hip, knee, 0.083)
|
| 210 |
+
model.joint(knee, 0.055)
|
| 211 |
+
model.limb(knee, ankle, 0.056)
|
| 212 |
+
model.joint(ankle, 0.036)
|
| 213 |
+
model.ellipsoid((side * 0.114, 0.058, 0.026), (0.058, 0.111, 0.047), 180,
|
| 214 |
+
axis=(0, -0.25, 1), facing=(0, -1, -0.25))
|
| 215 |
+
return model
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
def _render(model, azimuth, elevation, crop, size, pose):
|
| 219 |
+
azimuth, elevation = math.radians(azimuth), math.radians(elevation)
|
| 220 |
+
toward = (math.sin(azimuth) * math.cos(elevation), math.sin(elevation),
|
| 221 |
+
math.cos(azimuth) * math.cos(elevation))
|
| 222 |
+
right = (math.cos(azimuth), 0, -math.sin(azimuth))
|
| 223 |
+
up = _cross(toward, right)
|
| 224 |
+
if pose == "prone":
|
| 225 |
+
# Roll the overhead camera so the long body fits the landscape bucket.
|
| 226 |
+
right, up = up, _mul(right, -1)
|
| 227 |
+
projected = [(_dot(vertex, right), _dot(vertex, up))
|
| 228 |
+
for points, _, _ in model.faces for vertex in points]
|
| 229 |
+
min_x, max_x = min(v[0] for v in projected), max(v[0] for v in projected)
|
| 230 |
+
min_y, max_y = min(v[1] for v in projected), max(v[1] for v in projected)
|
| 231 |
+
if crop != "full":
|
| 232 |
+
# Absolute anatomical cut planes avoid uncertain image segmentation.
|
| 233 |
+
min_y = {"cowboy": 0.705, "upper": 1.160, "face": 1.493}[crop]
|
| 234 |
+
max_y += {"cowboy": 0.065, "upper": 0.047, "face": 0.025}[crop]
|
| 235 |
+
else:
|
| 236 |
+
height = max_y - min_y
|
| 237 |
+
min_y -= height * 0.055
|
| 238 |
+
max_y += height * 0.065
|
| 239 |
+
width = max_x - min_x
|
| 240 |
+
min_x -= width * 0.075
|
| 241 |
+
max_x += width * 0.075
|
| 242 |
+
width, height = size
|
| 243 |
+
scale = min(width / (max_x - min_x), height / (max_y - min_y)) if crop == "full" else height / (max_y - min_y)
|
| 244 |
+
center_x, center_y = (min_x + max_x) / 2, (min_y + max_y) / 2
|
| 245 |
+
supersample = 2
|
| 246 |
+
canvas = Image.new("RGB", (width * supersample, height * supersample), "white")
|
| 247 |
+
draw = ImageDraw.Draw(canvas)
|
| 248 |
+
# Camera-relative studio lighting makes shape readable at every azimuth.
|
| 249 |
+
light = _unit(_add(_mul(right, -0.40), _add(_mul(up, 0.68), _mul(toward, 0.80))))
|
| 250 |
+
faces = sorted(model.faces, key=lambda face: sum(_dot(p, toward) for p in face[0]))
|
| 251 |
+
for points, normal, tone in faces:
|
| 252 |
+
if _dot(normal, toward) < -0.08:
|
| 253 |
+
continue
|
| 254 |
+
coords = [(((_dot(p, right) - center_x) * scale + width / 2) * supersample,
|
| 255 |
+
(height / 2 - (_dot(p, up) - center_y) * scale) * supersample)
|
| 256 |
+
for p in points]
|
| 257 |
+
if max(p[1] for p in coords) < 0 or min(p[1] for p in coords) > height * supersample:
|
| 258 |
+
continue
|
| 259 |
+
diffuse = max(0, _dot(normal, light))
|
| 260 |
+
shade = round(tone * (0.54 + 0.55 * diffuse))
|
| 261 |
+
color = (shade, min(255, shade + 2), min(255, shade + 4))
|
| 262 |
+
draw.polygon(coords, fill=color)
|
| 263 |
+
return canvas.resize(size, Image.Resampling.LANCZOS)
|
| 264 |
+
|
| 265 |
+
|
| 266 |
+
def _preview(paths):
|
| 267 |
+
card_w, card_h, padding = 360, 420, 20
|
| 268 |
+
sheet = Image.new("RGB", (card_w * 3 + padding * 4, card_h * 4 + padding * 5), "#eef0f3")
|
| 269 |
+
draw = ImageDraw.Draw(sheet)
|
| 270 |
+
try:
|
| 271 |
+
font = ImageFont.truetype("DejaVuSans.ttf", 19)
|
| 272 |
+
except OSError:
|
| 273 |
+
font = ImageFont.load_default(size=19)
|
| 274 |
+
for index, (key, path) in enumerate(paths.items()):
|
| 275 |
+
x = padding + index % 3 * (card_w + padding)
|
| 276 |
+
y = padding + index // 3 * (card_h + padding)
|
| 277 |
+
draw.rounded_rectangle((x, y, x + card_w, y + card_h), radius=12, fill="white")
|
| 278 |
+
draw.text((x + 16, y + 17), GUIDE_SPECS[key][0], fill="#283444", font=font)
|
| 279 |
+
with Image.open(path) as source:
|
| 280 |
+
thumbnail = source.copy()
|
| 281 |
+
thumbnail.thumbnail((card_w - 24, card_h - 66), Image.Resampling.LANCZOS)
|
| 282 |
+
sheet.paste(thumbnail, (x + (card_w - thumbnail.width) // 2,
|
| 283 |
+
y + 52 + (card_h - 66 - thumbnail.height) // 2))
|
| 284 |
+
sheet.save(ASSET_DIR / "pose_preview.png", optimize=True)
|
| 285 |
+
|
| 286 |
+
|
| 287 |
+
def ensure_guides(*, regenerate: bool = False) -> dict[str, Path]:
|
| 288 |
+
"""Return the eleven bundled PNG paths; create any missing assets locally."""
|
| 289 |
+
ASSET_DIR.mkdir(parents=True, exist_ok=True)
|
| 290 |
+
paths = {key: ASSET_DIR / f"{key}.png" for key in GUIDE_SPECS}
|
| 291 |
+
models = {}
|
| 292 |
+
changed = False
|
| 293 |
+
for key, path in paths.items():
|
| 294 |
+
if path.is_file() and not regenerate:
|
| 295 |
+
continue
|
| 296 |
+
_, pose, azimuth, elevation, crop, size = GUIDE_SPECS[key]
|
| 297 |
+
if pose not in models:
|
| 298 |
+
models[pose] = {"standing": _standing, "knees": _knees, "prone": _prone}[pose]()
|
| 299 |
+
_render(models[pose], azimuth, elevation, crop, size, pose).save(path, optimize=True)
|
| 300 |
+
changed = True
|
| 301 |
+
if changed or not (ASSET_DIR / "pose_preview.png").is_file():
|
| 302 |
+
_preview(paths)
|
| 303 |
+
return paths
|
| 304 |
+
|
| 305 |
+
|
| 306 |
+
def get_guide(key: str, width: int, height: int) -> Image.Image:
|
| 307 |
+
"""Load one neutral RGB guide, resizing to the requested output dimensions."""
|
| 308 |
+
if key not in GUIDE_SPECS:
|
| 309 |
+
raise KeyError(f"Unknown pose guide: {key}")
|
| 310 |
+
if width <= 0 or height <= 0:
|
| 311 |
+
raise ValueError("Guide width and height must be positive")
|
| 312 |
+
path = ASSET_DIR / f"{key}.png"
|
| 313 |
+
if not path.is_file():
|
| 314 |
+
path = ensure_guides()[key]
|
| 315 |
+
with Image.open(path) as source:
|
| 316 |
+
result = source.convert("RGB")
|
| 317 |
+
if result.size != (width, height):
|
| 318 |
+
result = result.resize((width, height), Image.Resampling.LANCZOS)
|
| 319 |
+
return result
|
| 320 |
+
|
| 321 |
+
|
| 322 |
+
if __name__ == "__main__":
|
| 323 |
+
import argparse
|
| 324 |
+
|
| 325 |
+
parser = argparse.ArgumentParser(description=__doc__)
|
| 326 |
+
parser.add_argument("--regenerate", action="store_true", help="Rebuild all bundled PNGs")
|
| 327 |
+
args = parser.parse_args()
|
| 328 |
+
for guide_key, guide_path in ensure_guides(regenerate=args.regenerate).items():
|
| 329 |
+
print(f"{guide_key}: {guide_path}")
|
| 330 |
+
print(f"Preview: {ASSET_DIR / 'pose_preview.png'}")
|
qwenimage/__init__.py
DELETED
|
File without changes
|
qwenimage/qwen_fa3_processor.py
DELETED
|
@@ -1,142 +0,0 @@
|
|
| 1 |
-
"""
|
| 2 |
-
Paired with a good language model. Thanks!
|
| 3 |
-
"""
|
| 4 |
-
|
| 5 |
-
import torch
|
| 6 |
-
from typing import Optional, Tuple
|
| 7 |
-
from diffusers.models.transformers.transformer_qwenimage import apply_rotary_emb_qwen
|
| 8 |
-
|
| 9 |
-
try:
|
| 10 |
-
from kernels import get_kernel
|
| 11 |
-
_k = get_kernel("kernels-community/vllm-flash-attn3")
|
| 12 |
-
_flash_attn_func = _k.flash_attn_func
|
| 13 |
-
except Exception as e:
|
| 14 |
-
_flash_attn_func = None
|
| 15 |
-
_kernels_err = e
|
| 16 |
-
|
| 17 |
-
|
| 18 |
-
def _ensure_fa3_available():
|
| 19 |
-
if _flash_attn_func is None:
|
| 20 |
-
raise ImportError(
|
| 21 |
-
"FlashAttention-3 via Hugging Face `kernels` is required. "
|
| 22 |
-
"Tried `get_kernel('kernels-community/vllm-flash-attn3')` and failed with:\n"
|
| 23 |
-
f"{_kernels_err}"
|
| 24 |
-
)
|
| 25 |
-
|
| 26 |
-
@torch.library.custom_op("flash::flash_attn_func", mutates_args=())
|
| 27 |
-
def flash_attn_func(
|
| 28 |
-
q: torch.Tensor, k: torch.Tensor, v: torch.Tensor, causal: bool = False
|
| 29 |
-
) -> torch.Tensor:
|
| 30 |
-
outputs, lse = _flash_attn_func(q, k, v, causal=causal)
|
| 31 |
-
return outputs
|
| 32 |
-
|
| 33 |
-
@flash_attn_func.register_fake
|
| 34 |
-
def _(q, k, v, **kwargs):
|
| 35 |
-
# two outputs:
|
| 36 |
-
# 1. output: (batch, seq_len, num_heads, head_dim)
|
| 37 |
-
# 2. softmax_lse: (batch, num_heads, seq_len) with dtype=torch.float32
|
| 38 |
-
meta_q = torch.empty_like(q).contiguous()
|
| 39 |
-
return meta_q #, q.new_empty((q.size(0), q.size(2), q.size(1)), dtype=torch.float32)
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
class QwenDoubleStreamAttnProcessorFA3:
|
| 43 |
-
"""
|
| 44 |
-
FA3-based attention processor for Qwen double-stream architecture.
|
| 45 |
-
Computes joint attention over concatenated [text, image] streams using vLLM FlashAttention-3
|
| 46 |
-
accessed via Hugging Face `kernels`.
|
| 47 |
-
|
| 48 |
-
Notes / limitations:
|
| 49 |
-
- General attention masks are not supported here (FA3 path). `is_causal=False` and no arbitrary mask.
|
| 50 |
-
- Optional windowed attention / sink tokens / softcap can be plumbed through if you use those features.
|
| 51 |
-
- Expects an available `apply_rotary_emb_qwen` in scope (same as your non-FA3 processor).
|
| 52 |
-
"""
|
| 53 |
-
|
| 54 |
-
_attention_backend = "fa3" # for parity with your other processors, not used internally
|
| 55 |
-
|
| 56 |
-
def __init__(self):
|
| 57 |
-
_ensure_fa3_available()
|
| 58 |
-
|
| 59 |
-
@torch.no_grad()
|
| 60 |
-
def __call__(
|
| 61 |
-
self,
|
| 62 |
-
attn, # Attention module with to_q/to_k/to_v/add_*_proj, norms, to_out, to_add_out, and .heads
|
| 63 |
-
hidden_states: torch.FloatTensor, # (B, S_img, D_model) image stream
|
| 64 |
-
encoder_hidden_states: torch.FloatTensor = None, # (B, S_txt, D_model) text stream
|
| 65 |
-
encoder_hidden_states_mask: torch.FloatTensor = None, # unused in FA3 path
|
| 66 |
-
attention_mask: Optional[torch.FloatTensor] = None, # unused in FA3 path
|
| 67 |
-
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None, # (img_freqs, txt_freqs)
|
| 68 |
-
) -> Tuple[torch.FloatTensor, torch.FloatTensor]:
|
| 69 |
-
if encoder_hidden_states is None:
|
| 70 |
-
raise ValueError("QwenDoubleStreamAttnProcessorFA3 requires encoder_hidden_states (text stream).")
|
| 71 |
-
if attention_mask is not None:
|
| 72 |
-
# FA3 kernel path here does not consume arbitrary masks; fail fast to avoid silent correctness issues.
|
| 73 |
-
raise NotImplementedError("attention_mask is not supported in this FA3 implementation.")
|
| 74 |
-
|
| 75 |
-
_ensure_fa3_available()
|
| 76 |
-
|
| 77 |
-
B, S_img, _ = hidden_states.shape
|
| 78 |
-
S_txt = encoder_hidden_states.shape[1]
|
| 79 |
-
|
| 80 |
-
# ---- QKV projections (image/sample stream) ----
|
| 81 |
-
img_q = attn.to_q(hidden_states) # (B, S_img, D)
|
| 82 |
-
img_k = attn.to_k(hidden_states)
|
| 83 |
-
img_v = attn.to_v(hidden_states)
|
| 84 |
-
|
| 85 |
-
# ---- QKV projections (text/context stream) ----
|
| 86 |
-
txt_q = attn.add_q_proj(encoder_hidden_states) # (B, S_txt, D)
|
| 87 |
-
txt_k = attn.add_k_proj(encoder_hidden_states)
|
| 88 |
-
txt_v = attn.add_v_proj(encoder_hidden_states)
|
| 89 |
-
|
| 90 |
-
# ---- Reshape to (B, S, H, D_h) ----
|
| 91 |
-
H = attn.heads
|
| 92 |
-
img_q = img_q.unflatten(-1, (H, -1))
|
| 93 |
-
img_k = img_k.unflatten(-1, (H, -1))
|
| 94 |
-
img_v = img_v.unflatten(-1, (H, -1))
|
| 95 |
-
|
| 96 |
-
txt_q = txt_q.unflatten(-1, (H, -1))
|
| 97 |
-
txt_k = txt_k.unflatten(-1, (H, -1))
|
| 98 |
-
txt_v = txt_v.unflatten(-1, (H, -1))
|
| 99 |
-
|
| 100 |
-
# ---- Q/K normalization (per your module contract) ----
|
| 101 |
-
if getattr(attn, "norm_q", None) is not None:
|
| 102 |
-
img_q = attn.norm_q(img_q)
|
| 103 |
-
if getattr(attn, "norm_k", None) is not None:
|
| 104 |
-
img_k = attn.norm_k(img_k)
|
| 105 |
-
if getattr(attn, "norm_added_q", None) is not None:
|
| 106 |
-
txt_q = attn.norm_added_q(txt_q)
|
| 107 |
-
if getattr(attn, "norm_added_k", None) is not None:
|
| 108 |
-
txt_k = attn.norm_added_k(txt_k)
|
| 109 |
-
|
| 110 |
-
# ---- RoPE (Qwen variant) ----
|
| 111 |
-
if image_rotary_emb is not None:
|
| 112 |
-
img_freqs, txt_freqs = image_rotary_emb
|
| 113 |
-
# expects tensors shaped (B, S, H, D_h)
|
| 114 |
-
img_q = apply_rotary_emb_qwen(img_q, img_freqs, use_real=False)
|
| 115 |
-
img_k = apply_rotary_emb_qwen(img_k, img_freqs, use_real=False)
|
| 116 |
-
txt_q = apply_rotary_emb_qwen(txt_q, txt_freqs, use_real=False)
|
| 117 |
-
txt_k = apply_rotary_emb_qwen(txt_k, txt_freqs, use_real=False)
|
| 118 |
-
|
| 119 |
-
# ---- Joint attention over [text, image] along sequence axis ----
|
| 120 |
-
# Shapes: (B, S_total, H, D_h)
|
| 121 |
-
q = torch.cat([txt_q, img_q], dim=1)
|
| 122 |
-
k = torch.cat([txt_k, img_k], dim=1)
|
| 123 |
-
v = torch.cat([txt_v, img_v], dim=1)
|
| 124 |
-
|
| 125 |
-
# FlashAttention-3 path expects (B, S, H, D_h) and returns (out, softmax_lse)
|
| 126 |
-
out = flash_attn_func(q, k, v, causal=False) # out: (B, S_total, H, D_h)
|
| 127 |
-
|
| 128 |
-
# ---- Back to (B, S, D_model) ----
|
| 129 |
-
out = out.flatten(2, 3).to(q.dtype)
|
| 130 |
-
|
| 131 |
-
# Split back to text / image segments
|
| 132 |
-
txt_attn_out = out[:, :S_txt, :]
|
| 133 |
-
img_attn_out = out[:, S_txt:, :]
|
| 134 |
-
|
| 135 |
-
# ---- Output projections ----
|
| 136 |
-
img_attn_out = attn.to_out[0](img_attn_out)
|
| 137 |
-
if len(attn.to_out) > 1:
|
| 138 |
-
img_attn_out = attn.to_out[1](img_attn_out) # dropout if present
|
| 139 |
-
|
| 140 |
-
txt_attn_out = attn.to_add_out(txt_attn_out)
|
| 141 |
-
|
| 142 |
-
return img_attn_out, txt_attn_out
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
requirements.txt
CHANGED
|
@@ -1,35 +1,9 @@
|
|
| 1 |
-
# torch
|
| 2 |
-
#
|
| 3 |
-
|
| 4 |
-
|
| 5 |
-
# RuntimeError: NVML_SUCCESS == r INTERNAL ASSERT FAILED at CUDACachingAllocator.cpp:1165
|
| 6 |
-
# で必ず落ちた (spaces が pin_memory().cuda() でモデルを転送する箇所)。
|
| 7 |
-
# ZeroGPU のベースイメージが入れる torch をそのまま使うこと。
|
| 8 |
-
#
|
| 9 |
-
# 依存の組み合わせは、同じ Qwen-Image-Edit-2511 + 同じ角度 LoRA で実際に稼働している
|
| 10 |
-
# multimodalart/qwen-image-multiple-angles-3d-camera に合わせてある。
|
| 11 |
-
diffusers==0.39.0
|
| 12 |
-
transformers
|
| 13 |
accelerate
|
| 14 |
safetensors
|
| 15 |
-
sentencepiece
|
| 16 |
peft
|
| 17 |
torchvision
|
| 18 |
-
|
| 19 |
-
# FlashAttention-3 をカーネルとして取得する。
|
| 20 |
-
# kernels 0.15 以降は get_kernel() に version=/revision= が必須になり、
|
| 21 |
-
# vendoring している qwen_fa3_processor.py の呼び出しが通らなくなるため 0.15 未満に固定。
|
| 22 |
-
kernels<0.15
|
| 23 |
-
|
| 24 |
-
# fp8 動的量子化 (VRAM 削減 + 約 1.2 倍の高速化)
|
| 25 |
-
torchao==0.16.0
|
| 26 |
-
|
| 27 |
-
# タガーは CPU 実行 (ZeroGPU クォータを消費しない)
|
| 28 |
-
onnxruntime
|
| 29 |
pillow
|
| 30 |
-
numpy
|
| 31 |
-
|
| 32 |
-
# `spaces` と `gradio` は書かないこと。
|
| 33 |
-
# HF Spaces はビルドコマンドで両方を強制注入する:
|
| 34 |
-
# pip install -r requirements.txt "torch<=2.11.0" gradio[oauth,mcp]==5.49.1 ... spaces==0.51.1
|
| 35 |
-
# requirements.txt 側で別バージョンを指定すると ResolutionImpossible でビルドが落ちる。
|
|
|
|
| 1 |
+
# HF Gradio/ZeroGPU supplies torch, spaces and gradio. Keep those environment versions.
|
| 2 |
+
# Pinned upstream implementation includes QwenImage21 + saved Turbo sigma schedules.
|
| 3 |
+
git+https://github.com/huggingface/diffusers.git@85c9fa4caee33d1c5b473395784471d2d7957c1b
|
| 4 |
+
transformers>=5.17.0,<6
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
accelerate
|
| 6 |
safetensors
|
|
|
|
| 7 |
peft
|
| 8 |
torchvision
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 9 |
pillow
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
tagging.py
DELETED
|
@@ -1,441 +0,0 @@
|
|
| 1 |
-
"""LoRA 学習用キャプション生成 (WD Tagger v3 / OppaiOracle の比較付き).
|
| 2 |
-
|
| 3 |
-
どちらのタガーも ONNX なので **onnxruntime の CPU 実行**にしてある。
|
| 4 |
-
ZeroGPU のクォータは要求 duration ぶんそのまま消費されるため、タグ付けを GPU 側で
|
| 5 |
-
やると生成できる視点数が直接減る。CPU で回せばクォータ消費はゼロになる。
|
| 6 |
-
|
| 7 |
-
キャプションの構成:
|
| 8 |
-
{トリガーワード}, {構図の確定タグ}, {タガーが推定したタグ}
|
| 9 |
-
|
| 10 |
-
構図タグ (full body / from behind / from above / cowboy shot など) は
|
| 11 |
-
views.py のカメラパラメータから決定的に注入する。タガーは構図を安定して当てられない
|
| 12 |
-
ので、既知の情報を推論に任せない方が精度が高い。
|
| 13 |
-
"""
|
| 14 |
-
|
| 15 |
-
from __future__ import annotations
|
| 16 |
-
|
| 17 |
-
import csv
|
| 18 |
-
import json
|
| 19 |
-
import threading
|
| 20 |
-
from dataclasses import dataclass
|
| 21 |
-
from typing import Dict, List, Sequence, Tuple
|
| 22 |
-
|
| 23 |
-
import numpy as np
|
| 24 |
-
from huggingface_hub import hf_hub_download
|
| 25 |
-
from PIL import Image
|
| 26 |
-
|
| 27 |
-
# --- タガー定義 -------------------------------------------------------------
|
| 28 |
-
|
| 29 |
-
WD_REPO = "SmilingWolf/wd-swinv2-tagger-v3"
|
| 30 |
-
WD_DEFAULT_THRESHOLD = 0.35
|
| 31 |
-
|
| 32 |
-
OPPAI_REPO = "Grio43/OppaiOracle"
|
| 33 |
-
OPPAI_SUBDIR = "V1.1_onnx"
|
| 34 |
-
# pr_thresholds.json の micro.f1_optimal.threshold。WD の 0.35 とは桁が違うので
|
| 35 |
-
# 共通の既定値を使ってはいけない。
|
| 36 |
-
OPPAI_DEFAULT_THRESHOLD = 0.805
|
| 37 |
-
OPPAI_SKIP_INDICES = (0, 1) # <PAD>, <UNK>
|
| 38 |
-
|
| 39 |
-
#: Danbooru の rating / character カテゴリ。キャラクター LoRA の学習では
|
| 40 |
-
#: 通常どちらもキャプションから外す (rating はノイズ、character 名は固有名詞)。
|
| 41 |
-
WD_KEEP_CATEGORIES = (0,)
|
| 42 |
-
|
| 43 |
-
#: OppaiOracle は全タグが general カテゴリ扱いで、rating タグも同じ空間に入っている
|
| 44 |
-
#: (実測で `rating:general` が確信度 1.00 で出る)。名前で落とす。
|
| 45 |
-
META_TAG_PREFIXES = ("rating:",)
|
| 46 |
-
|
| 47 |
-
#: 画像そのものの素性を表すメタタグ。学習キャプションに残すとノイズにしかならない。
|
| 48 |
-
META_TAGS = frozenset(
|
| 49 |
-
{
|
| 50 |
-
"highres", "absurdres", "incredibly absurdres", "lowres", "hugefilesize",
|
| 51 |
-
"commentary", "commentary request", "english commentary", "chinese commentary",
|
| 52 |
-
"translated", "translation request", "check translation",
|
| 53 |
-
"bad id", "bad pixiv id", "bad twitter id", "bad link",
|
| 54 |
-
"jpeg artifacts", "scan", "official art", "artist request", "character request",
|
| 55 |
-
"md5 mismatch", "resolution mismatch", "source larger", "non-web source",
|
| 56 |
-
"third-party edit", "revision", "duplicate", "image sample",
|
| 57 |
-
}
|
| 58 |
-
)
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
def is_meta_tag(tag: str) -> bool:
|
| 62 |
-
norm = _normalize(tag)
|
| 63 |
-
return norm in META_TAGS or any(norm.startswith(p) for p in META_TAG_PREFIXES)
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
def format_tag(tag: str) -> str:
|
| 67 |
-
"""Danbooru タグを kohya-ss のキャプション表記に整える。"""
|
| 68 |
-
if tag in ("^_^", ">_<", "o_o", "0_0", "|_|", "._.", "\\m/", "^^^"):
|
| 69 |
-
return tag
|
| 70 |
-
return tag.replace("_", " ").replace("(", r"\(").replace(")", r"\)")
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
def _normalize(tag: str) -> str:
|
| 74 |
-
"""重複判定・除外判定に使う正規形。"""
|
| 75 |
-
return tag.replace("_", " ").replace("\\", "").strip().lower()
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
@dataclass
|
| 79 |
-
class TagResult:
|
| 80 |
-
tagger: str
|
| 81 |
-
tags: List[Tuple[str, float]] #: (整形済みタグ, 確信度) を確信度降順で
|
| 82 |
-
|
| 83 |
-
def names(self) -> List[str]:
|
| 84 |
-
return [t for t, _ in self.tags]
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
class _OnnxTagger:
|
| 88 |
-
"""ONNX タガーの共通土台。セッションはプロセス内で 1 回だけ作る。"""
|
| 89 |
-
|
| 90 |
-
name = "base"
|
| 91 |
-
default_threshold = 0.35
|
| 92 |
-
#: UI の閾値スライダー範囲 (min, max, step)。両タガーはスコア分布が大きく違うため、
|
| 93 |
-
#: 共通のレンジを使うと片方が実用外の値しか選べなくなる。
|
| 94 |
-
threshold_range = (0.05, 0.95, 0.01)
|
| 95 |
-
|
| 96 |
-
def __init__(self) -> None:
|
| 97 |
-
self._session = None
|
| 98 |
-
self._tags: List[str] = []
|
| 99 |
-
self._categories: List[int] = []
|
| 100 |
-
self._lock = threading.Lock()
|
| 101 |
-
|
| 102 |
-
def _build(self) -> None: # pragma: no cover - サブクラスで実装
|
| 103 |
-
raise NotImplementedError
|
| 104 |
-
|
| 105 |
-
def ensure_loaded(self) -> None:
|
| 106 |
-
if self._session is not None:
|
| 107 |
-
return
|
| 108 |
-
with self._lock:
|
| 109 |
-
if self._session is None:
|
| 110 |
-
self._build()
|
| 111 |
-
|
| 112 |
-
def _preprocess(self, image: Image.Image) -> Dict[str, np.ndarray]: # pragma: no cover
|
| 113 |
-
raise NotImplementedError
|
| 114 |
-
|
| 115 |
-
def predict(
|
| 116 |
-
self,
|
| 117 |
-
image: Image.Image,
|
| 118 |
-
threshold: float | None = None,
|
| 119 |
-
drop_meta: bool = True,
|
| 120 |
-
max_tags: int = 60,
|
| 121 |
-
) -> TagResult:
|
| 122 |
-
self.ensure_loaded()
|
| 123 |
-
thr = self.default_threshold if threshold is None else float(threshold)
|
| 124 |
-
probs = self._session.run(None, self._preprocess(image))[0][0]
|
| 125 |
-
|
| 126 |
-
picked: List[Tuple[str, float]] = []
|
| 127 |
-
for idx in np.nonzero(probs >= thr)[0]:
|
| 128 |
-
if idx >= len(self._tags):
|
| 129 |
-
continue
|
| 130 |
-
raw = self._tags[idx]
|
| 131 |
-
if not raw:
|
| 132 |
-
continue
|
| 133 |
-
if self._categories and self._categories[idx] not in WD_KEEP_CATEGORIES:
|
| 134 |
-
continue
|
| 135 |
-
if drop_meta and is_meta_tag(raw):
|
| 136 |
-
continue
|
| 137 |
-
picked.append((format_tag(raw), float(probs[idx])))
|
| 138 |
-
picked.sort(key=lambda x: x[1], reverse=True)
|
| 139 |
-
# 閾値を下げすぎたときに数千タグが出てキャプションが壊れるのを防ぐ
|
| 140 |
-
return TagResult(self.name, picked[:max_tags])
|
| 141 |
-
|
| 142 |
-
|
| 143 |
-
class WDTagger(_OnnxTagger):
|
| 144 |
-
"""SmilingWolf/wd-*-tagger-v3.
|
| 145 |
-
|
| 146 |
-
ONNX 入力は NHWC・BGR・0-255 のまま (正規化はグラフ内)。余白は白で
|
| 147 |
-
正方形にパディングしてからリサイズする、というのが SmilingWolf 系の作法。
|
| 148 |
-
"""
|
| 149 |
-
|
| 150 |
-
name = "WD Tagger v3"
|
| 151 |
-
default_threshold = WD_DEFAULT_THRESHOLD
|
| 152 |
-
threshold_range = (0.10, 0.70, 0.01)
|
| 153 |
-
|
| 154 |
-
def __init__(self, repo: str = WD_REPO) -> None:
|
| 155 |
-
super().__init__()
|
| 156 |
-
self.repo = repo
|
| 157 |
-
self._size = 448
|
| 158 |
-
self._channels_last = True
|
| 159 |
-
self._input_name = "input"
|
| 160 |
-
|
| 161 |
-
def _build(self) -> None:
|
| 162 |
-
import onnxruntime as ort
|
| 163 |
-
|
| 164 |
-
model_path = hf_hub_download(self.repo, "model.onnx")
|
| 165 |
-
tags_path = hf_hub_download(self.repo, "selected_tags.csv")
|
| 166 |
-
|
| 167 |
-
with open(tags_path, "r", encoding="utf-8") as fh:
|
| 168 |
-
rows = list(csv.DictReader(fh))
|
| 169 |
-
self._tags = [r["name"] for r in rows]
|
| 170 |
-
self._categories = [int(r["category"]) for r in rows]
|
| 171 |
-
|
| 172 |
-
session = ort.InferenceSession(model_path, providers=["CPUExecutionProvider"])
|
| 173 |
-
inp = session.get_inputs()[0]
|
| 174 |
-
self._input_name = inp.name
|
| 175 |
-
shape = inp.shape
|
| 176 |
-
# [N, H, W, 3] なら NHWC、[N, 3, H, W] なら NCHW
|
| 177 |
-
self._channels_last = len(shape) == 4 and shape[-1] == 3
|
| 178 |
-
dim = shape[1] if self._channels_last else shape[2]
|
| 179 |
-
if isinstance(dim, int) and dim > 0:
|
| 180 |
-
self._size = dim
|
| 181 |
-
self._session = session
|
| 182 |
-
print(f"[tagging] {self.name} loaded: {len(self._tags)} tags, input={inp.name}{shape}")
|
| 183 |
-
|
| 184 |
-
def _preprocess(self, image: Image.Image) -> Dict[str, np.ndarray]:
|
| 185 |
-
img = image.convert("RGBA")
|
| 186 |
-
canvas = Image.new("RGBA", img.size, (255, 255, 255))
|
| 187 |
-
canvas.alpha_composite(img)
|
| 188 |
-
img = canvas.convert("RGB")
|
| 189 |
-
|
| 190 |
-
side = max(img.size)
|
| 191 |
-
square = Image.new("RGB", (side, side), (255, 255, 255))
|
| 192 |
-
square.paste(img, ((side - img.size[0]) // 2, (side - img.size[1]) // 2))
|
| 193 |
-
square = square.resize((self._size, self._size), Image.BICUBIC)
|
| 194 |
-
|
| 195 |
-
arr = np.asarray(square, dtype=np.float32)[:, :, ::-1] # RGB -> BGR
|
| 196 |
-
if not self._channels_last:
|
| 197 |
-
arr = arr.transpose(2, 0, 1)
|
| 198 |
-
return {self._input_name: np.expand_dims(arr, axis=0)}
|
| 199 |
-
|
| 200 |
-
|
| 201 |
-
class OppaiOracleTagger(_OnnxTagger):
|
| 202 |
-
"""Grio43/OppaiOracle V1.1.
|
| 203 |
-
|
| 204 |
-
前処理はグラフ外。preprocessing.json の指定どおり
|
| 205 |
-
letterbox (アスペクト比維持 + (114,114,114) パディング) → (x/255 - 0.5) / 0.5。
|
| 206 |
-
`padding_mask` (True = パディング画素) を第 2 入力として渡す必要がある。
|
| 207 |
-
"""
|
| 208 |
-
|
| 209 |
-
name = "OppaiOracle V1.1"
|
| 210 |
-
default_threshold = OPPAI_DEFAULT_THRESHOLD
|
| 211 |
-
# 実測: 0.805 で 21 タグ / 0.5 で 445 タグ / 0.35 で 2768 タグ。
|
| 212 |
-
# WD と同じレンジにすると実用外の領域しか触れなくなるので分けてある。
|
| 213 |
-
threshold_range = (0.60, 0.97, 0.005)
|
| 214 |
-
|
| 215 |
-
def __init__(self) -> None:
|
| 216 |
-
super().__init__()
|
| 217 |
-
self._size = 448
|
| 218 |
-
self._pad = (114, 114, 114)
|
| 219 |
-
self._mean = 0.5
|
| 220 |
-
self._std = 0.5
|
| 221 |
-
|
| 222 |
-
def _build(self) -> None:
|
| 223 |
-
import onnxruntime as ort
|
| 224 |
-
|
| 225 |
-
model_path = hf_hub_download(OPPAI_REPO, f"{OPPAI_SUBDIR}/model.onnx")
|
| 226 |
-
tags_path = hf_hub_download(OPPAI_REPO, f"{OPPAI_SUBDIR}/selected_tags.csv")
|
| 227 |
-
prep_path = hf_hub_download(OPPAI_REPO, f"{OPPAI_SUBDIR}/preprocessing.json")
|
| 228 |
-
|
| 229 |
-
with open(prep_path, "r", encoding="utf-8") as fh:
|
| 230 |
-
prep = json.load(fh)
|
| 231 |
-
self._size = int(prep.get("image_size", 448))
|
| 232 |
-
self._pad = tuple(prep.get("pad_color_rgb", [114, 114, 114]))
|
| 233 |
-
self._mean = float(prep.get("normalize_mean", [0.5])[0])
|
| 234 |
-
self._std = float(prep.get("normalize_std", [0.5])[0])
|
| 235 |
-
|
| 236 |
-
with open(tags_path, "r", encoding="utf-8") as fh:
|
| 237 |
-
rows = list(csv.DictReader(fh))
|
| 238 |
-
self._tags = [r["name"] for r in rows]
|
| 239 |
-
# 全タグが general カテゴリなのでカテゴリ絞り込みはしない
|
| 240 |
-
self._categories = []
|
| 241 |
-
for idx in OPPAI_SKIP_INDICES:
|
| 242 |
-
if idx < len(self._tags):
|
| 243 |
-
self._tags[idx] = "" # <PAD> / <UNK> は出力しない
|
| 244 |
-
|
| 245 |
-
self._session = ort.InferenceSession(model_path, providers=["CPUExecutionProvider"])
|
| 246 |
-
names = [i.name for i in self._session.get_inputs()]
|
| 247 |
-
print(f"[tagging] {self.name} loaded: {len(self._tags)} tags, inputs={names}")
|
| 248 |
-
|
| 249 |
-
def _preprocess(self, image: Image.Image) -> Dict[str, np.ndarray]:
|
| 250 |
-
img = image.convert("RGB")
|
| 251 |
-
w, h = img.size
|
| 252 |
-
scale = self._size / max(w, h)
|
| 253 |
-
nw, nh = max(1, round(w * scale)), max(1, round(h * scale))
|
| 254 |
-
resized = img.resize((nw, nh), Image.BICUBIC)
|
| 255 |
-
|
| 256 |
-
canvas = Image.new("RGB", (self._size, self._size), self._pad)
|
| 257 |
-
off_x, off_y = (self._size - nw) // 2, (self._size - nh) // 2
|
| 258 |
-
canvas.paste(resized, (off_x, off_y))
|
| 259 |
-
|
| 260 |
-
arr = np.asarray(canvas, dtype=np.float32) / 255.0
|
| 261 |
-
arr = (arr - self._mean) / self._std
|
| 262 |
-
arr = arr.transpose(2, 0, 1)[None] # NCHW
|
| 263 |
-
|
| 264 |
-
mask = np.ones((self._size, self._size), dtype=bool) # True = パディング
|
| 265 |
-
mask[off_y : off_y + nh, off_x : off_x + nw] = False
|
| 266 |
-
return {"pixel_values": arr, "padding_mask": mask[None]}
|
| 267 |
-
|
| 268 |
-
|
| 269 |
-
_WD = WDTagger()
|
| 270 |
-
_OPPAI = OppaiOracleTagger()
|
| 271 |
-
|
| 272 |
-
TAGGERS: Dict[str, _OnnxTagger] = {
|
| 273 |
-
"wd": _WD,
|
| 274 |
-
"oppai": _OPPAI,
|
| 275 |
-
}
|
| 276 |
-
TAGGER_LABELS = {
|
| 277 |
-
"wd": "WD Tagger v3 (SmilingWolf)",
|
| 278 |
-
"oppai": "OppaiOracle V1.1 (Grio43)",
|
| 279 |
-
}
|
| 280 |
-
|
| 281 |
-
|
| 282 |
-
# --- キャプション組み立て ---------------------------------------------------
|
| 283 |
-
|
| 284 |
-
|
| 285 |
-
#: 互いに排他的なタグ群。タガーは「うつ伏せの視点」を条件付け元の立ち絵から
|
| 286 |
-
#: 推定してしまい `standing` を返すことがある (実測)。確定タグ側で構図が決まって
|
| 287 |
-
#: いる群については、タガー由来の同じ群のタグを落として矛盾を防ぐ。
|
| 288 |
-
CONFLICT_GROUPS: Tuple[frozenset, ...] = (
|
| 289 |
-
# フレーミング
|
| 290 |
-
frozenset(
|
| 291 |
-
{
|
| 292 |
-
"full body", "upper body", "portrait", "close-up", "cowboy shot",
|
| 293 |
-
"lower body", "feet out of frame", "head out of frame",
|
| 294 |
-
}
|
| 295 |
-
),
|
| 296 |
-
# カメラ方向
|
| 297 |
-
frozenset(
|
| 298 |
-
{
|
| 299 |
-
"from behind", "from side", "from above", "from below", "from front",
|
| 300 |
-
"profile", "facing away", "facing viewer", "dutch angle",
|
| 301 |
-
}
|
| 302 |
-
),
|
| 303 |
-
# ポーズ
|
| 304 |
-
frozenset(
|
| 305 |
-
{
|
| 306 |
-
"standing", "sitting", "lying", "on stomach", "on back", "on side",
|
| 307 |
-
"squatting", "kneeling", "walking", "running", "all fours",
|
| 308 |
-
"hugging own legs", "knees up", "crossed legs", "wariza", "yokozuwari",
|
| 309 |
-
"seiza", "arms up", "leaning forward",
|
| 310 |
-
}
|
| 311 |
-
),
|
| 312 |
-
)
|
| 313 |
-
|
| 314 |
-
|
| 315 |
-
def _conflicting_keys(fixed_norm: set) -> set:
|
| 316 |
-
"""確定タグが触れている群のうち、確定タグ自身には無いタグの正規形。"""
|
| 317 |
-
blocked: set = set()
|
| 318 |
-
for group in CONFLICT_GROUPS:
|
| 319 |
-
if fixed_norm & group:
|
| 320 |
-
blocked |= group - fixed_norm
|
| 321 |
-
return blocked
|
| 322 |
-
|
| 323 |
-
|
| 324 |
-
def build_caption(
|
| 325 |
-
fixed_tags: Sequence[str],
|
| 326 |
-
predicted: Sequence[str],
|
| 327 |
-
trigger: str = "",
|
| 328 |
-
exclude: Sequence[str] | str = (),
|
| 329 |
-
) -> str:
|
| 330 |
-
"""確定タグとタガー出力をマージして 1 行のキャプションにする。
|
| 331 |
-
|
| 332 |
-
確定タグを先に置くのは、kohya-ss の caption dropout / shuffle を使わない
|
| 333 |
-
運用で先頭ほど強く効くため。
|
| 334 |
-
"""
|
| 335 |
-
if isinstance(exclude, str):
|
| 336 |
-
exclude = parse_exclude(exclude)
|
| 337 |
-
# ユーザー指定の除外は確定タグにも効かせる (白背景を外したい等のため)
|
| 338 |
-
user_excluded = {_normalize(e) for e in exclude if e.strip()}
|
| 339 |
-
# 矛盾による除外はタガー出力にだけ効かせる
|
| 340 |
-
conflict_blocked = _conflicting_keys({_normalize(t) for t in fixed_tags})
|
| 341 |
-
|
| 342 |
-
seen: set = set()
|
| 343 |
-
out: List[str] = []
|
| 344 |
-
|
| 345 |
-
trigger = (trigger or "").strip()
|
| 346 |
-
if trigger:
|
| 347 |
-
out.append(trigger)
|
| 348 |
-
seen.add(_normalize(trigger))
|
| 349 |
-
|
| 350 |
-
for tag in fixed_tags:
|
| 351 |
-
key = _normalize(tag)
|
| 352 |
-
if not key or key in seen or key in user_excluded:
|
| 353 |
-
continue
|
| 354 |
-
seen.add(key)
|
| 355 |
-
out.append(tag)
|
| 356 |
-
|
| 357 |
-
for tag in predicted:
|
| 358 |
-
key = _normalize(tag)
|
| 359 |
-
if not key or key in seen or key in user_excluded or key in conflict_blocked:
|
| 360 |
-
continue
|
| 361 |
-
seen.add(key)
|
| 362 |
-
out.append(tag)
|
| 363 |
-
|
| 364 |
-
return ", ".join(out)
|
| 365 |
-
|
| 366 |
-
|
| 367 |
-
def parse_exclude(text: str) -> List[str]:
|
| 368 |
-
return [t.strip() for t in (text or "").replace("\n", ",").split(",") if t.strip()]
|
| 369 |
-
|
| 370 |
-
|
| 371 |
-
def compare(results: Dict[str, TagResult]) -> Dict[str, List[str]]:
|
| 372 |
-
"""タガー間の共通タグ / 片方だけのタグを求める。"""
|
| 373 |
-
if len(results) < 2:
|
| 374 |
-
only = next(iter(results.values())).names() if results else []
|
| 375 |
-
return {"common": only, "wd_only": [], "oppai_only": []}
|
| 376 |
-
|
| 377 |
-
wd = results.get("wd")
|
| 378 |
-
op = results.get("oppai")
|
| 379 |
-
wd_set = {_normalize(t): t for t in (wd.names() if wd else [])}
|
| 380 |
-
op_set = {_normalize(t): t for t in (op.names() if op else [])}
|
| 381 |
-
common = [wd_set[k] for k in wd_set if k in op_set]
|
| 382 |
-
return {
|
| 383 |
-
"common": common,
|
| 384 |
-
"wd_only": [wd_set[k] for k in wd_set if k not in op_set],
|
| 385 |
-
"oppai_only": [op_set[k] for k in op_set if k not in wd_set],
|
| 386 |
-
}
|
| 387 |
-
|
| 388 |
-
|
| 389 |
-
def comparison_markdown(per_view: Dict[str, Dict[str, TagResult]]) -> str:
|
| 390 |
-
"""ZIP に同梱する比較レポート。"""
|
| 391 |
-
lines = [
|
| 392 |
-
"# キャプション比較: WD Tagger v3 vs OppaiOracle V1.1",
|
| 393 |
-
"",
|
| 394 |
-
"同一画像に両タガーを適用した結果。`共通` が多いほど両者の判断が一致している。",
|
| 395 |
-
"どちらも Danbooru 系のアニメタガーなので、実写寄りの参照画像ではタグ品質が落ちる。",
|
| 396 |
-
"",
|
| 397 |
-
"| 視点 | 共通 | WD のみ | OppaiOracle のみ | WD 総数 | Oppai 総数 |",
|
| 398 |
-
"|---|---|---|---|:---:|:---:|",
|
| 399 |
-
]
|
| 400 |
-
totals = {"common": 0, "wd_only": 0, "oppai_only": 0, "wd": 0, "oppai": 0}
|
| 401 |
-
for view_key, results in per_view.items():
|
| 402 |
-
cmp = compare(results)
|
| 403 |
-
wd_n = len(results["wd"].tags) if "wd" in results else 0
|
| 404 |
-
op_n = len(results["oppai"].tags) if "oppai" in results else 0
|
| 405 |
-
totals["common"] += len(cmp["common"])
|
| 406 |
-
totals["wd_only"] += len(cmp["wd_only"])
|
| 407 |
-
totals["oppai_only"] += len(cmp["oppai_only"])
|
| 408 |
-
totals["wd"] += wd_n
|
| 409 |
-
totals["oppai"] += op_n
|
| 410 |
-
lines.append(
|
| 411 |
-
f"| {view_key} | {', '.join(cmp['common']) or '-'} | "
|
| 412 |
-
f"{', '.join(cmp['wd_only']) or '-'} | {', '.join(cmp['oppai_only']) or '-'} | "
|
| 413 |
-
f"{wd_n} | {op_n} |"
|
| 414 |
-
)
|
| 415 |
-
|
| 416 |
-
lines += [
|
| 417 |
-
"",
|
| 418 |
-
"## 合計",
|
| 419 |
-
"",
|
| 420 |
-
f"- 共通タグ: {totals['common']}",
|
| 421 |
-
f"- WD のみ: {totals['wd_only']}",
|
| 422 |
-
f"- OppaiOracle のみ: {totals['oppai_only']}",
|
| 423 |
-
f"- 総タグ数: WD {totals['wd']} / OppaiOracle {totals['oppai']}",
|
| 424 |
-
"",
|
| 425 |
-
"## 閾値について",
|
| 426 |
-
"",
|
| 427 |
-
f"- WD Tagger v3 の既定閾値は {WD_DEFAULT_THRESHOLD}",
|
| 428 |
-
f"- OppaiOracle の既定閾値は {OPPAI_DEFAULT_THRESHOLD} "
|
| 429 |
-
"(pr_thresholds.json の micro.f1_optimal)",
|
| 430 |
-
"",
|
| 431 |
-
"両者はスコアの分布が大きく違うため、同じ閾値で比べると不公平になる。",
|
| 432 |
-
"タグ数を揃えて比べたい場合は UI の閾値スライダーで調整すること。",
|
| 433 |
-
"",
|
| 434 |
-
"## 既知の傾向",
|
| 435 |
-
"",
|
| 436 |
-
"- OppaiOracle はモデルカード自身が「色名タグはソース由来のノイズが多い」"
|
| 437 |
-
"「本来 50+ 付くべきところ平均 28 タグしか付いていない」と明記している。",
|
| 438 |
-
"- 構図タグ (from behind / from above / cowboy shot など) は"
|
| 439 |
-
"どちらのタガーも安定しないため、本 Space ではカメラパラメータから決定的に注入している。",
|
| 440 |
-
]
|
| 441 |
-
return "\n".join(lines)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
tests/test_core.py
ADDED
|
@@ -0,0 +1,321 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""CPU-only behavioral checks. These do not validate model speed or image quality."""
|
| 2 |
+
import contextlib
|
| 3 |
+
import io
|
| 4 |
+
from pathlib import Path
|
| 5 |
+
import shutil
|
| 6 |
+
import sys
|
| 7 |
+
import unittest
|
| 8 |
+
import zipfile
|
| 9 |
+
|
| 10 |
+
from PIL import Image, ImageDraw
|
| 11 |
+
|
| 12 |
+
sys.path.insert(0, str(Path(__file__).resolve().parents[1]))
|
| 13 |
+
|
| 14 |
+
from core import (build_zip, conditioning_reference, prepare_reference,
|
| 15 |
+
requested_seconds, rgb_on_white, run_batch)
|
| 16 |
+
from views import BY_KEY, DEFAULT_KEYS, SIZES, VIEWS, validate_keys
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
class FakeClock:
|
| 20 |
+
def __init__(self):
|
| 21 |
+
self.now = 0.0
|
| 22 |
+
|
| 23 |
+
def __call__(self):
|
| 24 |
+
return self.now
|
| 25 |
+
|
| 26 |
+
def advance(self, seconds):
|
| 27 |
+
self.now += seconds
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
class CoreTests(unittest.TestCase):
|
| 31 |
+
def setUp(self):
|
| 32 |
+
self.reference = Image.new("RGB", (24, 32), "red")
|
| 33 |
+
self.guides = {key: Image.new("RGB", (12, 16), (index, 0, 0))
|
| 34 |
+
for index, key in enumerate(DEFAULT_KEYS)}
|
| 35 |
+
self.clock = FakeClock()
|
| 36 |
+
|
| 37 |
+
def run_generation(self, generate_one, keys=None, **overrides):
|
| 38 |
+
options = dict(generate_one=generate_one, reference=self.reference,
|
| 39 |
+
keys=DEFAULT_KEYS if keys is None else keys,
|
| 40 |
+
guide_images=self.guides, resolution="fast", seed=123,
|
| 41 |
+
extra="", angles=False, budget_seconds=100,
|
| 42 |
+
clock=self.clock)
|
| 43 |
+
options.update(overrides)
|
| 44 |
+
with contextlib.redirect_stdout(io.StringIO()):
|
| 45 |
+
return run_batch(**options)
|
| 46 |
+
|
| 47 |
+
def test_exactly_the_eleven_requested_views(self):
|
| 48 |
+
expected = ["full_front", "full_left", "full_right", "full_back",
|
| 49 |
+
"cowboy_front", "cowboy_back", "upper_front", "face_front",
|
| 50 |
+
"knees_front", "knees_back", "prone_back"]
|
| 51 |
+
self.assertEqual(DEFAULT_KEYS, expected)
|
| 52 |
+
self.assertEqual(len(VIEWS), 11)
|
| 53 |
+
self.assertEqual(len(BY_KEY), 11)
|
| 54 |
+
self.assertEqual(validate_keys(["full_front", "face_front", "full_front"]),
|
| 55 |
+
["full_front", "face_front"])
|
| 56 |
+
for invalid in ([], ["unknown"], ["full_front", "unknown"]):
|
| 57 |
+
with self.subTest(invalid=invalid), self.assertRaises(ValueError):
|
| 58 |
+
validate_keys(invalid)
|
| 59 |
+
|
| 60 |
+
def test_each_view_uses_original_identity_and_its_own_guide(self):
|
| 61 |
+
calls = []
|
| 62 |
+
generated = []
|
| 63 |
+
|
| 64 |
+
def generate(**kwargs):
|
| 65 |
+
calls.append(kwargs)
|
| 66 |
+
output = Image.new("RGB", (8, 8), (0, len(calls), 0))
|
| 67 |
+
generated.append(output)
|
| 68 |
+
self.clock.advance(0.25)
|
| 69 |
+
return output
|
| 70 |
+
|
| 71 |
+
result = self.run_generation(generate, crop_close_views=True)
|
| 72 |
+
self.assertEqual(len(calls), 11, "No extra anchor generations are permitted")
|
| 73 |
+
self.assertEqual(list(result.images), DEFAULT_KEYS)
|
| 74 |
+
self.assertEqual(len(result.timings), 11)
|
| 75 |
+
self.assertEqual(result.stop_reason, "")
|
| 76 |
+
for index, (key, call) in enumerate(zip(DEFAULT_KEYS, calls)):
|
| 77 |
+
with self.subTest(key=key):
|
| 78 |
+
self.assertEqual(len(call["image"]), 2)
|
| 79 |
+
if key in ("cowboy_front", "cowboy_back", "upper_front", "face_front"):
|
| 80 |
+
source = call["image"][0]
|
| 81 |
+
self.assertIsNot(source, self.reference)
|
| 82 |
+
self.assertEqual(source.size, (call["width"], call["height"]))
|
| 83 |
+
self.assertEqual(source.getpixel((source.width // 2, source.height // 2)),
|
| 84 |
+
(255, 0, 0), "Crop must retain original red identity reference")
|
| 85 |
+
else:
|
| 86 |
+
self.assertIs(call["image"][0], self.reference)
|
| 87 |
+
self.assertTrue(all(call["image"][0] is not output for output in generated))
|
| 88 |
+
self.assertIs(call["image"][1], self.guides[key])
|
| 89 |
+
self.assertIs(result.images[key], generated[index])
|
| 90 |
+
self.assertEqual((call["width"], call["height"]),
|
| 91 |
+
SIZES["fast"][BY_KEY[key].shape])
|
| 92 |
+
self.assertIn("Image 2", call["prompt"])
|
| 93 |
+
self.assertEqual(result.timings[index]["references"], 2)
|
| 94 |
+
|
| 95 |
+
def test_guides_can_be_disabled_without_an_extra_generation(self):
|
| 96 |
+
calls = []
|
| 97 |
+
|
| 98 |
+
def generate(**kwargs):
|
| 99 |
+
calls.append(kwargs)
|
| 100 |
+
return Image.new("RGB", (8, 8))
|
| 101 |
+
|
| 102 |
+
result = self.run_generation(generate, keys=["full_front"], guide_images=None)
|
| 103 |
+
self.assertEqual(len(calls), 1)
|
| 104 |
+
self.assertEqual(calls[0]["image"], [self.reference])
|
| 105 |
+
self.assertNotIn("Image 2", calls[0]["prompt"])
|
| 106 |
+
self.assertEqual(result.timings[0]["references"], 1)
|
| 107 |
+
|
| 108 |
+
def test_crop_is_disabled_by_default_for_all_views(self):
|
| 109 |
+
calls = []
|
| 110 |
+
|
| 111 |
+
def generate(**kwargs):
|
| 112 |
+
calls.append(kwargs)
|
| 113 |
+
return Image.new("RGB", (8, 8))
|
| 114 |
+
|
| 115 |
+
self.run_generation(generate)
|
| 116 |
+
self.assertEqual(len(calls), 11)
|
| 117 |
+
self.assertTrue(all(call["image"][0] is self.reference for call in calls))
|
| 118 |
+
|
| 119 |
+
def test_per_view_seed_stays_the_same_for_subsets_and_reordering(self):
|
| 120 |
+
def seeds_for(keys):
|
| 121 |
+
received = []
|
| 122 |
+
|
| 123 |
+
def generate(**kwargs):
|
| 124 |
+
received.append(kwargs["seed"])
|
| 125 |
+
return Image.new("RGB", (8, 8))
|
| 126 |
+
|
| 127 |
+
self.run_generation(generate, keys=keys, seed=2**31 - 3)
|
| 128 |
+
return dict(zip(keys, received))
|
| 129 |
+
|
| 130 |
+
all_seeds = seeds_for(DEFAULT_KEYS)
|
| 131 |
+
subset = ["prone_back", "full_front", "face_front"]
|
| 132 |
+
self.assertEqual(seeds_for(subset), {key: all_seeds[key] for key in subset})
|
| 133 |
+
self.assertEqual(all_seeds["full_front"], 2**31 - 3)
|
| 134 |
+
self.assertEqual(all_seeds["full_back"], 0)
|
| 135 |
+
self.assertEqual(len(set(all_seeds.values())), 11)
|
| 136 |
+
|
| 137 |
+
def test_generation_failure_keeps_completed_results(self):
|
| 138 |
+
completed = Image.new("RGB", (8, 8), "blue")
|
| 139 |
+
calls = []
|
| 140 |
+
|
| 141 |
+
def generate(**kwargs):
|
| 142 |
+
calls.append(kwargs)
|
| 143 |
+
if len(calls) == 2:
|
| 144 |
+
raise RuntimeError("simulated backend error")
|
| 145 |
+
return completed
|
| 146 |
+
|
| 147 |
+
result = self.run_generation(generate)
|
| 148 |
+
self.assertEqual(len(calls), 2)
|
| 149 |
+
self.assertEqual(list(result.images), ["full_front"])
|
| 150 |
+
self.assertIs(result.images["full_front"], completed)
|
| 151 |
+
self.assertEqual(len(result.timings), 1)
|
| 152 |
+
self.assertIn(BY_KEY["full_left"].label, result.stop_reason)
|
| 153 |
+
self.assertTrue(result.stop_reason)
|
| 154 |
+
|
| 155 |
+
def test_denoising_budget_expiry_keeps_previous_result(self):
|
| 156 |
+
calls = []
|
| 157 |
+
|
| 158 |
+
def generate(**kwargs):
|
| 159 |
+
calls.append(kwargs)
|
| 160 |
+
self.clock.advance(1 if len(calls) == 1 else 13)
|
| 161 |
+
kwargs["check_budget"]()
|
| 162 |
+
return Image.new("RGB", (8, 8))
|
| 163 |
+
|
| 164 |
+
result = self.run_generation(generate, budget_seconds=20)
|
| 165 |
+
self.assertEqual(len(calls), 2)
|
| 166 |
+
self.assertEqual(list(result.images), ["full_front"])
|
| 167 |
+
self.assertEqual(len(result.timings), 1)
|
| 168 |
+
self.assertTrue(result.stop_reason)
|
| 169 |
+
|
| 170 |
+
def test_insufficient_remaining_time_stops_before_starting_next_view(self):
|
| 171 |
+
calls = []
|
| 172 |
+
|
| 173 |
+
def generate(**kwargs):
|
| 174 |
+
calls.append(kwargs)
|
| 175 |
+
self.clock.advance(6)
|
| 176 |
+
return Image.new("RGB", (8, 8))
|
| 177 |
+
|
| 178 |
+
result = self.run_generation(generate, budget_seconds=20)
|
| 179 |
+
self.assertEqual(len(calls), 1)
|
| 180 |
+
self.assertEqual(list(result.images), ["full_front"])
|
| 181 |
+
self.assertTrue(result.stop_reason)
|
| 182 |
+
|
| 183 |
+
def test_empty_budget_does_not_start_generation(self):
|
| 184 |
+
def never_called(**kwargs):
|
| 185 |
+
self.fail("Generation must not start when the budget is exhausted")
|
| 186 |
+
|
| 187 |
+
result = self.run_generation(never_called, budget_seconds=0)
|
| 188 |
+
self.assertEqual(result.images, {})
|
| 189 |
+
self.assertTrue(result.stop_reason)
|
| 190 |
+
|
| 191 |
+
def test_requested_budget_obeys_configured_ceiling(self):
|
| 192 |
+
self.assertEqual(requested_seconds(DEFAULT_KEYS), 110)
|
| 193 |
+
self.assertEqual(requested_seconds(DEFAULT_KEYS, maximum=60), 60)
|
| 194 |
+
self.assertEqual(requested_seconds(["face_front"]), 45)
|
| 195 |
+
self.assertEqual(requested_seconds(["face_front", "face_front"]), 45)
|
| 196 |
+
|
| 197 |
+
def test_single_view_budget_allows_work_after_startup_and_decode_reserves(self):
|
| 198 |
+
# Artificial 20-second generation: a regression check, not a speed estimate.
|
| 199 |
+
# The backend reserves 15 seconds for ZeroGPU startup/result transport.
|
| 200 |
+
def generate(**kwargs):
|
| 201 |
+
self.clock.advance(20)
|
| 202 |
+
kwargs["check_budget"]()
|
| 203 |
+
return Image.new("RGB", (8, 8))
|
| 204 |
+
|
| 205 |
+
keys = ["face_front"]
|
| 206 |
+
result = self.run_generation(generate, keys=keys,
|
| 207 |
+
budget_seconds=requested_seconds(keys) - 15)
|
| 208 |
+
self.assertEqual(list(result.images), keys)
|
| 209 |
+
self.assertEqual(result.stop_reason, "")
|
| 210 |
+
|
| 211 |
+
def test_zip_contains_only_selected_completed_pngs_no_captions(self):
|
| 212 |
+
completed = {"full_front": Image.new("RGBA", (12, 16), "red"),
|
| 213 |
+
"face_front": Image.new("RGB", (16, 16), "blue"),
|
| 214 |
+
"prone_back": Image.new("RGB", (16, 12), "green")}
|
| 215 |
+
# One selected image has not been generated; one completed image is unselected.
|
| 216 |
+
path = build_zip(completed, ["face_front", "full_left", "full_front", "face_front"])
|
| 217 |
+
self.assertIsNotNone(path)
|
| 218 |
+
self.addCleanup(shutil.rmtree, Path(path).parent)
|
| 219 |
+
with zipfile.ZipFile(path) as archive:
|
| 220 |
+
self.assertEqual(archive.namelist(),
|
| 221 |
+
["dataset/08_face_front.png", "dataset/01_full_front.png"])
|
| 222 |
+
for name in archive.namelist():
|
| 223 |
+
with self.subTest(name=name), Image.open(io.BytesIO(archive.read(name))) as image:
|
| 224 |
+
image.load()
|
| 225 |
+
self.assertEqual(image.format, "PNG")
|
| 226 |
+
self.assertEqual(image.mode, "RGB")
|
| 227 |
+
self.assertEqual(image.getpixel((0, 0)),
|
| 228 |
+
(0, 0, 255) if "face_front" in name else (255, 0, 0))
|
| 229 |
+
|
| 230 |
+
def test_zip_has_no_file_when_selection_has_no_completed_images(self):
|
| 231 |
+
self.assertIsNone(build_zip({}, DEFAULT_KEYS))
|
| 232 |
+
self.assertIsNone(build_zip({"full_front": self.reference}, ["face_front"]))
|
| 233 |
+
|
| 234 |
+
def test_zip_composites_transparent_generated_pixels_on_white(self):
|
| 235 |
+
source = Image.new("RGBA", (2, 1), (255, 0, 0, 128))
|
| 236 |
+
source.putpixel((1, 0), (0, 0, 0, 0))
|
| 237 |
+
path = build_zip({"full_front": source}, ["full_front"])
|
| 238 |
+
self.addCleanup(shutil.rmtree, Path(path).parent)
|
| 239 |
+
with zipfile.ZipFile(path) as archive:
|
| 240 |
+
with Image.open(io.BytesIO(archive.read("dataset/01_full_front.png"))) as image:
|
| 241 |
+
self.assertEqual(image.mode, "RGB")
|
| 242 |
+
self.assertEqual(image.getpixel((0, 0)), (255, 127, 127))
|
| 243 |
+
self.assertEqual(image.getpixel((1, 0)), (255, 255, 255))
|
| 244 |
+
self.assertEqual(source.getpixel((1, 0)), (0, 0, 0, 0))
|
| 245 |
+
|
| 246 |
+
def test_close_view_crops_use_foreground_height_and_exclude_lower_stripes(self):
|
| 247 |
+
source = Image.new("RGB", (200, 400), (245, 245, 245))
|
| 248 |
+
draw = ImageDraw.Draw(source)
|
| 249 |
+
draw.rectangle((60, 40, 139, 359), fill=(128, 128, 128))
|
| 250 |
+
colors = {"head": (255, 0, 0), "chest": (0, 255, 0),
|
| 251 |
+
"thigh": (0, 0, 255), "feet": (255, 0, 255)}
|
| 252 |
+
for name, top, bottom in (("head", 40, 71), ("chest", 128, 143),
|
| 253 |
+
("thigh", 210, 225), ("feet", 335, 359)):
|
| 254 |
+
draw.rectangle((60, top, 139, bottom), fill=colors[name])
|
| 255 |
+
original = source.tobytes()
|
| 256 |
+
expected = {"cowboy_front": {"head", "chest", "thigh"},
|
| 257 |
+
"cowboy_back": {"head", "chest", "thigh"},
|
| 258 |
+
"upper_front": {"head", "chest"}, "face_front": {"head"}}
|
| 259 |
+
for key, included in expected.items():
|
| 260 |
+
with self.subTest(key=key):
|
| 261 |
+
cropped = conditioning_reference(source, key, 256, 256)
|
| 262 |
+
self.assertEqual(cropped.mode, "RGB")
|
| 263 |
+
self.assertEqual(cropped.size, (256, 256))
|
| 264 |
+
palette = {color for count, color in cropped.getcolors(256 * 256)}
|
| 265 |
+
for name, color in colors.items():
|
| 266 |
+
self.assertEqual(color in palette, name in included,
|
| 267 |
+
f"Unexpected {name} stripe content in {key}")
|
| 268 |
+
self.assertEqual(source.tobytes(), original)
|
| 269 |
+
self.assertEqual(source.size, (200, 400))
|
| 270 |
+
|
| 271 |
+
def test_close_view_letterboxing_preserves_shape_without_stretching(self):
|
| 272 |
+
source = Image.new("RGB", (200, 400), "white")
|
| 273 |
+
draw = ImageDraw.Draw(source)
|
| 274 |
+
draw.rectangle((80, 60, 119, 359), fill=(160, 160, 160))
|
| 275 |
+
draw.rectangle((90, 40, 109, 59), fill="black")
|
| 276 |
+
cropped = conditioning_reference(source, "face_front", 200, 100)
|
| 277 |
+
dark = cropped.convert("L").point(lambda value: 255 if value < 20 else 0)
|
| 278 |
+
left, top, right, bottom = dark.getbbox()
|
| 279 |
+
self.assertLessEqual(abs((right - left) - (bottom - top)), 1,
|
| 280 |
+
"A square marker must remain square after fitting")
|
| 281 |
+
self.assertEqual(cropped.size, (200, 100))
|
| 282 |
+
self.assertEqual(cropped.getpixel((0, 50)), (255, 255, 255))
|
| 283 |
+
self.assertGreater(top, 0, "The top of the head should retain a safe margin")
|
| 284 |
+
|
| 285 |
+
def test_other_views_keep_the_original_reference_object(self):
|
| 286 |
+
for key in ("full_front", "full_left", "full_right", "full_back",
|
| 287 |
+
"knees_front", "knees_back", "prone_back"):
|
| 288 |
+
with self.subTest(key=key):
|
| 289 |
+
self.assertIs(conditioning_reference(self.reference, key, 512, 768), self.reference)
|
| 290 |
+
|
| 291 |
+
def test_white_or_transparent_reference_can_be_cropped(self):
|
| 292 |
+
source = Image.new("RGBA", (40, 80), (0, 0, 0, 0))
|
| 293 |
+
cropped = conditioning_reference(source, "face_front", 120, 100)
|
| 294 |
+
self.assertEqual(cropped.size, (120, 100))
|
| 295 |
+
self.assertEqual(cropped.getextrema(), ((255, 255), (255, 255), (255, 255)))
|
| 296 |
+
composite = rgb_on_white(source)
|
| 297 |
+
self.assertEqual(composite.mode, "RGB")
|
| 298 |
+
self.assertEqual(source.mode, "RGBA")
|
| 299 |
+
|
| 300 |
+
def test_reference_alpha_is_composited_on_white_and_downsized(self):
|
| 301 |
+
source = Image.new("RGBA", (400, 200), (255, 0, 0, 128))
|
| 302 |
+
prepared = prepare_reference(source, 100)
|
| 303 |
+
self.assertEqual(prepared.mode, "RGB")
|
| 304 |
+
self.assertEqual(prepared.size, (100, 50))
|
| 305 |
+
self.assertEqual(prepared.getpixel((50, 25)), (255, 127, 127))
|
| 306 |
+
self.assertEqual(source.mode, "RGBA")
|
| 307 |
+
self.assertEqual(source.size, (400, 200))
|
| 308 |
+
transparent = prepare_reference(Image.new("RGBA", (2, 2), (0, 0, 0, 0)), 100)
|
| 309 |
+
self.assertEqual(transparent.getpixel((0, 0)), (255, 255, 255))
|
| 310 |
+
self.assertEqual(transparent.size, (2, 2), "Small input should not be enlarged")
|
| 311 |
+
|
| 312 |
+
def test_reference_exif_orientation_is_applied(self):
|
| 313 |
+
source = Image.new("RGB", (40, 20), "red")
|
| 314 |
+
source.getexif()[274] = 6
|
| 315 |
+
prepared = prepare_reference(source, 100)
|
| 316 |
+
self.assertEqual(prepared.size, (20, 40))
|
| 317 |
+
self.assertNotIn(274, prepared.getexif())
|
| 318 |
+
|
| 319 |
+
|
| 320 |
+
if __name__ == "__main__":
|
| 321 |
+
unittest.main()
|
views.py
CHANGED
|
@@ -1,447 +1,93 @@
|
|
| 1 |
-
"""
|
|
|
|
| 2 |
|
| 3 |
-
|
| 4 |
-
キャプションへの確定タグ注入を **すべてこのテーブルから導出** する。
|
| 5 |
-
視点を増やすときは VIEWS に行を足すだけでよい。
|
| 6 |
-
|
| 7 |
-
カメラ指定は fal/Qwen-Image-Edit-2511-Multiple-Angles-LoRA のトリガ語彙に従う:
|
| 8 |
-
<sks> {azimuth} {elevation} {distance}
|
| 9 |
-
LoRA は 4 仰角 × 8 方位 × 3 距離 = 96 カメラ位置で学習されているため、
|
| 10 |
-
下の定数以外の文字列を入れても効かない。
|
| 11 |
-
"""
|
| 12 |
-
|
| 13 |
-
from dataclasses import dataclass, field
|
| 14 |
-
from typing import Dict, List, Tuple
|
| 15 |
-
|
| 16 |
-
# --- 角度 LoRA の語彙 (この 3 つの辞書の値以外は使わないこと) ---------------
|
| 17 |
-
|
| 18 |
-
AZIMUTH = {
|
| 19 |
-
0: "front view",
|
| 20 |
-
45: "front-right quarter view",
|
| 21 |
-
90: "right side view",
|
| 22 |
-
135: "back-right quarter view",
|
| 23 |
-
180: "back view",
|
| 24 |
-
225: "back-left quarter view",
|
| 25 |
-
270: "left side view",
|
| 26 |
-
315: "front-left quarter view",
|
| 27 |
-
}
|
| 28 |
-
ELEVATION = {
|
| 29 |
-
-30: "low-angle shot",
|
| 30 |
-
0: "eye-level shot",
|
| 31 |
-
30: "elevated shot",
|
| 32 |
-
60: "high-angle shot",
|
| 33 |
-
}
|
| 34 |
-
DISTANCE = {
|
| 35 |
-
0.6: "close-up",
|
| 36 |
-
1.0: "medium shot",
|
| 37 |
-
1.8: "wide shot",
|
| 38 |
-
}
|
| 39 |
-
|
| 40 |
-
TRIGGER = "<sks>"
|
| 41 |
-
|
| 42 |
-
# 全視点に共通で入れる背景指定。背景をプロンプトで固定しつつ、キャプション側にも
|
| 43 |
-
# white background / simple background を明示的に入れることで、LoRA に背景が
|
| 44 |
-
# 「無名の前提」として焼き付くのを避ける (タグとして学習させて後で外せるようにする)。
|
| 45 |
-
BACKGROUND_PROMPT = "The background is plain white."
|
| 46 |
-
GLOBAL_TAGS = ("solo", "simple background", "white background")
|
| 47 |
-
|
| 48 |
-
# 学習バケット (kohya-ss 標準、いずれも約 1MP)
|
| 49 |
-
PORTRAIT = (832, 1216)
|
| 50 |
-
SQUARE = (1024, 1024)
|
| 51 |
-
LANDSCAPE = (1216, 832)
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
@dataclass(frozen=True)
|
| 55 |
-
class Camera:
|
| 56 |
-
azimuth: int
|
| 57 |
-
elevation: int
|
| 58 |
-
distance: float
|
| 59 |
-
|
| 60 |
-
def phrase(self) -> str:
|
| 61 |
-
return f"{TRIGGER} {AZIMUTH[self.azimuth]} {ELEVATION[self.elevation]} {DISTANCE[self.distance]}"
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
@dataclass(frozen=True)
|
| 65 |
-
class Anchor:
|
| 66 |
-
"""ポーズの基準画像。ここから各視点をカメラ移動で派生させる。"""
|
| 67 |
-
|
| 68 |
-
key: str
|
| 69 |
-
label_ja: str
|
| 70 |
-
pose_prompt: str
|
| 71 |
-
camera: Camera
|
| 72 |
-
size: Tuple[int, int]
|
| 73 |
-
# 条件付けに使う画像。"reference" はユーザーのアップロード画像、
|
| 74 |
-
# それ以外は別アンカーの key を指す。
|
| 75 |
-
source: str
|
| 76 |
|
| 77 |
|
| 78 |
@dataclass(frozen=True)
|
| 79 |
class View:
|
| 80 |
key: str
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
|
| 93 |
-
|
| 94 |
-
|
| 95 |
-
|
| 96 |
-
|
| 97 |
-
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
| 106 |
-
"
|
| 107 |
-
"
|
| 108 |
-
"The legs are positioned symmetrically with a narrow stance."
|
| 109 |
-
)
|
| 110 |
-
POSE_HUG_KNEES = (
|
| 111 |
-
"The character sits on the ground hugging both knees against the chest, with the arms "
|
| 112 |
-
"wrapped around the shins and the back slightly rounded. The feet are flat on the ground."
|
| 113 |
-
)
|
| 114 |
-
POSE_PRONE = (
|
| 115 |
-
"The character lies prone on the ground, face down on their stomach, with the legs "
|
| 116 |
-
"extended straight behind and the arms resting near the head."
|
| 117 |
-
)
|
| 118 |
-
|
| 119 |
-
# 寄り視点の指示文。実機検証で有効だった言い回しを採用している。
|
| 120 |
-
# 「何が見えるか」だけでなく「何がフレーム外か」を明示すると効きがよい。
|
| 121 |
-
FACE_TEXT = "A close-up portrait showing only the character's head and face."
|
| 122 |
-
UPPER_TEXT = (
|
| 123 |
-
"An upper body shot. Only the head, shoulders and chest are visible; "
|
| 124 |
-
"the waist and legs are out of frame."
|
| 125 |
)
|
| 126 |
-
|
| 127 |
-
|
| 128 |
-
|
| 129 |
-
)
|
| 130 |
-
|
| 131 |
-
ANCHORS: Dict[str, Anchor] = {
|
| 132 |
-
"standing": Anchor(
|
| 133 |
-
key="standing",
|
| 134 |
-
label_ja="立ち (基準)",
|
| 135 |
-
pose_prompt=POSE_STANDING,
|
| 136 |
-
camera=Camera(0, 0, 1.8),
|
| 137 |
-
size=PORTRAIT,
|
| 138 |
-
source="reference",
|
| 139 |
-
),
|
| 140 |
-
"hug_knees": Anchor(
|
| 141 |
-
key="hug_knees",
|
| 142 |
-
label_ja="膝抱え座り (基準)",
|
| 143 |
-
pose_prompt=POSE_HUG_KNEES,
|
| 144 |
-
camera=Camera(0, 0, 1.8),
|
| 145 |
-
size=PORTRAIT,
|
| 146 |
-
source="standing",
|
| 147 |
-
),
|
| 148 |
-
# うつ伏せは Tier1 では「後方・高所から」の 1 視点しか使わないため、アンカー自身を
|
| 149 |
-
# その構図で作って生成 1 回ぶんを節約する。ポーズ変更とカメラ移動を同時に要求する
|
| 150 |
-
# ぶん破綻しやすいので、app.py の詳細設定で 2 段階生成に切り替えられるようにしてある。
|
| 151 |
-
"prone": Anchor(
|
| 152 |
-
key="prone",
|
| 153 |
-
label_ja="うつ伏せ (基準)",
|
| 154 |
-
pose_prompt=POSE_PRONE,
|
| 155 |
-
camera=Camera(180, 60, 1.8),
|
| 156 |
-
size=LANDSCAPE,
|
| 157 |
-
source="standing",
|
| 158 |
-
),
|
| 159 |
}
|
| 160 |
-
|
| 161 |
-
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
| 166 |
-
|
| 167 |
-
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
|
| 171 |
-
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
|
| 178 |
-
|
| 179 |
-
|
| 180 |
-
|
| 181 |
-
|
| 182 |
-
|
| 183 |
-
|
| 184 |
-
size=PORTRAIT,
|
| 185 |
-
tags=("full body", "standing", "from side", "profile"),
|
| 186 |
-
),
|
| 187 |
-
View(
|
| 188 |
-
key="full_right",
|
| 189 |
-
label_ja="全身 右側面",
|
| 190 |
-
group_ja="全身 (三面図)",
|
| 191 |
-
anchor="standing",
|
| 192 |
-
camera=Camera(90, 0, 1.8),
|
| 193 |
-
size=PORTRAIT,
|
| 194 |
-
tags=("full body", "standing", "from side", "profile"),
|
| 195 |
-
),
|
| 196 |
-
View(
|
| 197 |
-
key="full_back",
|
| 198 |
-
label_ja="全身 背面",
|
| 199 |
-
group_ja="全身 (三面図)",
|
| 200 |
-
anchor="standing",
|
| 201 |
-
camera=Camera(180, 0, 1.8),
|
| 202 |
-
size=PORTRAIT,
|
| 203 |
-
tags=("full body", "standing", "from behind"),
|
| 204 |
-
),
|
| 205 |
-
View(
|
| 206 |
-
key="cowboy_front",
|
| 207 |
-
label_ja="カウボーイショット 正面",
|
| 208 |
-
group_ja="カウボーイショット",
|
| 209 |
-
anchor="standing",
|
| 210 |
-
camera=Camera(0, 0, 1.0),
|
| 211 |
-
size=SQUARE,
|
| 212 |
-
extra_prompt=COWBOY_TEXT,
|
| 213 |
-
tags=("cowboy shot", "standing", "looking at viewer"),
|
| 214 |
-
use_pose_prompt=False,
|
| 215 |
-
crop_kind="cowboy",
|
| 216 |
-
crop_from="full_front",
|
| 217 |
-
),
|
| 218 |
-
View(
|
| 219 |
-
key="cowboy_back",
|
| 220 |
-
label_ja="カウボーイショット 背面",
|
| 221 |
-
group_ja="カウボーイショット",
|
| 222 |
-
anchor="standing",
|
| 223 |
-
camera=Camera(180, 0, 1.0),
|
| 224 |
-
size=SQUARE,
|
| 225 |
-
extra_prompt=COWBOY_TEXT,
|
| 226 |
-
tags=("cowboy shot", "standing", "from behind"),
|
| 227 |
-
use_pose_prompt=False,
|
| 228 |
-
crop_kind="cowboy",
|
| 229 |
-
# 背面の寄りは背面の全身画像から切り出す必要がある
|
| 230 |
-
crop_from="full_back",
|
| 231 |
-
),
|
| 232 |
-
View(
|
| 233 |
-
key="upper_front",
|
| 234 |
-
label_ja="上半身 正面",
|
| 235 |
-
group_ja="寄り",
|
| 236 |
-
anchor="standing",
|
| 237 |
-
camera=Camera(0, 0, 0.6),
|
| 238 |
-
size=SQUARE,
|
| 239 |
-
extra_prompt=UPPER_TEXT,
|
| 240 |
-
tags=("upper body", "looking at viewer"),
|
| 241 |
-
use_pose_prompt=False,
|
| 242 |
-
crop_kind="upper",
|
| 243 |
-
crop_from="full_front",
|
| 244 |
-
),
|
| 245 |
-
View(
|
| 246 |
-
key="face_front",
|
| 247 |
-
label_ja="顔 正面",
|
| 248 |
-
group_ja="寄り",
|
| 249 |
-
anchor="standing",
|
| 250 |
-
camera=Camera(0, 0, 0.6),
|
| 251 |
-
size=SQUARE,
|
| 252 |
-
extra_prompt=FACE_TEXT,
|
| 253 |
-
tags=("portrait", "close-up", "looking at viewer"),
|
| 254 |
-
use_pose_prompt=False,
|
| 255 |
-
crop_kind="face",
|
| 256 |
-
crop_from="full_front",
|
| 257 |
-
),
|
| 258 |
-
View(
|
| 259 |
-
key="knees_front",
|
| 260 |
-
label_ja="膝抱え 正面",
|
| 261 |
-
group_ja="膝抱え座り",
|
| 262 |
-
anchor="hug_knees",
|
| 263 |
-
camera=Camera(0, 0, 1.8),
|
| 264 |
-
size=PORTRAIT,
|
| 265 |
-
tags=("full body", "sitting", "hugging own legs", "knees up"),
|
| 266 |
-
),
|
| 267 |
-
View(
|
| 268 |
-
key="knees_back",
|
| 269 |
-
label_ja="膝抱え 背面",
|
| 270 |
-
group_ja="膝抱え座り",
|
| 271 |
-
anchor="hug_knees",
|
| 272 |
-
camera=Camera(180, 0, 1.8),
|
| 273 |
-
size=PORTRAIT,
|
| 274 |
-
tags=("full body", "sitting", "hugging own legs", "knees up", "from behind"),
|
| 275 |
-
),
|
| 276 |
-
View(
|
| 277 |
-
key="prone_back",
|
| 278 |
-
label_ja="うつ伏せ 後方から",
|
| 279 |
-
group_ja="うつ伏せ",
|
| 280 |
-
anchor="prone",
|
| 281 |
-
camera=Camera(180, 60, 1.8),
|
| 282 |
-
size=LANDSCAPE,
|
| 283 |
-
tags=("full body", "lying", "on stomach", "from behind", "from above"),
|
| 284 |
-
),
|
| 285 |
-
]
|
| 286 |
-
|
| 287 |
-
VIEW_BY_KEY: Dict[str, View] = {v.key: v for v in VIEWS}
|
| 288 |
-
DEFAULT_SELECTION: List[str] = [v.key for v in VIEWS]
|
| 289 |
-
|
| 290 |
-
#: UI のグループ見出し順 (VIEWS の出現順を保つ)
|
| 291 |
-
GROUP_ORDER: List[str] = list(dict.fromkeys(v.group_ja for v in VIEWS))
|
| 292 |
-
|
| 293 |
-
PRESETS: Dict[str, List[str]] = {
|
| 294 |
-
"全選択 (11視点)": [v.key for v in VIEWS],
|
| 295 |
-
"三面図のみ (4視点)": ["full_front", "full_left", "full_right", "full_back"],
|
| 296 |
-
"最小構成 (2視点)": ["full_front", "face_front"],
|
| 297 |
-
}
|
| 298 |
-
|
| 299 |
-
|
| 300 |
-
# --- プロンプト組み立て -----------------------------------------------------
|
| 301 |
-
|
| 302 |
-
|
| 303 |
-
def _compose(camera: Camera, pose_prompt: str, extra_prompt: str, user_extra: str) -> str:
|
| 304 |
-
parts = [camera.phrase(), pose_prompt]
|
| 305 |
-
if extra_prompt:
|
| 306 |
-
parts.append(extra_prompt)
|
| 307 |
-
parts.append(BACKGROUND_PROMPT)
|
| 308 |
-
user_extra = (user_extra or "").strip()
|
| 309 |
-
if user_extra:
|
| 310 |
-
parts.append(user_extra)
|
| 311 |
-
return " ".join(p.strip() for p in parts if p and p.strip())
|
| 312 |
-
|
| 313 |
-
|
| 314 |
-
def anchor_prompt(anchor: Anchor, user_extra: str = "", camera: Camera = None) -> str:
|
| 315 |
-
return _compose(camera or anchor.camera, anchor.pose_prompt, "", user_extra)
|
| 316 |
-
|
| 317 |
-
|
| 318 |
-
def view_prompt(view: View, user_extra: str = "") -> str:
|
| 319 |
-
pose = ANCHORS[view.anchor].pose_prompt if view.use_pose_prompt else ""
|
| 320 |
-
return _compose(view.camera, pose, view.extra_prompt, user_extra)
|
| 321 |
-
|
| 322 |
-
|
| 323 |
-
def caption_tags(view: View) -> Tuple[str, ...]:
|
| 324 |
-
"""タガー出力とマージする前の、構図に由来する確定タグ。"""
|
| 325 |
-
return tuple(GLOBAL_TAGS) + view.tags
|
| 326 |
-
|
| 327 |
-
|
| 328 |
-
# --- 依存解決 / 生成計画 ----------------------------------------------------
|
| 329 |
-
|
| 330 |
-
|
| 331 |
-
@dataclass(frozen=True)
|
| 332 |
-
class Step:
|
| 333 |
-
"""1 回の pipe() 呼び出し。"""
|
| 334 |
-
|
| 335 |
-
key: str #: 生成物の識別子 (視点 key か "anchor:<name>")
|
| 336 |
-
kind: str #: "anchor" | "view"
|
| 337 |
-
label_ja: str
|
| 338 |
-
prompt_of: object #: Anchor または View
|
| 339 |
-
source: str #: 条件付け画像の識別子 ("reference" | "anchor:<name>" | 視点 key)
|
| 340 |
-
size: Tuple[int, int]
|
| 341 |
-
view_key: str = "" #: このステップが直接生み出す視点 (あれば)
|
| 342 |
-
crop_kind: str = "" #: 条件付け画像を切り出す種別 (framing.CROP_FRACTION のキー)
|
| 343 |
-
#: ユーザーが選んだ視点ではなく、寄りの切り出し元として必要になっただけの中間生成か
|
| 344 |
-
intermediate: bool = False
|
| 345 |
-
|
| 346 |
-
|
| 347 |
-
def _anchor_id(key: str) -> str:
|
| 348 |
-
return f"anchor:{key}"
|
| 349 |
-
|
| 350 |
-
|
| 351 |
-
def build_plan(selected_keys: List[str], two_stage_prone: bool = False) -> List[Step]:
|
| 352 |
-
"""選択された視点を生成するために必要な pipe() 呼び出しを、依存順に並べて返す。
|
| 353 |
-
|
| 354 |
-
依存は 2 種類ある:
|
| 355 |
-
- ポーズアンカー (立ち → 膝抱え / うつ伏せ)
|
| 356 |
-
- 寄りの切り出し元となる別の視点 (背面カウボーイ ← 背面全身)
|
| 357 |
-
アンカーのカメラと一致し追加指示のない視点は、アンカー生成で兼ねて 1 回省く。
|
| 358 |
-
"""
|
| 359 |
-
requested = [k for k in selected_keys if k in VIEW_BY_KEY]
|
| 360 |
-
if not requested:
|
| 361 |
-
return []
|
| 362 |
-
|
| 363 |
-
# --- 1. 必要な視点の閉包を取る (寄りの切り出し元をたどる) ---
|
| 364 |
-
needed_views: List[str] = []
|
| 365 |
-
|
| 366 |
-
def require_view(key: str) -> None:
|
| 367 |
-
if key in needed_views:
|
| 368 |
-
return
|
| 369 |
-
view = VIEW_BY_KEY[key]
|
| 370 |
-
if view.crop_from:
|
| 371 |
-
require_view(view.crop_from)
|
| 372 |
-
needed_views.append(key)
|
| 373 |
-
|
| 374 |
-
for k in requested:
|
| 375 |
-
require_view(k)
|
| 376 |
-
|
| 377 |
-
# --- 2. 必要なアンカーの閉包を取る ---
|
| 378 |
-
anchors_needed: List[str] = []
|
| 379 |
-
|
| 380 |
-
def require_anchor(name: str) -> None:
|
| 381 |
-
if name in anchors_needed:
|
| 382 |
-
return
|
| 383 |
-
src = ANCHORS[name].source
|
| 384 |
-
if src != "reference":
|
| 385 |
-
require_anchor(src)
|
| 386 |
-
anchors_needed.append(name)
|
| 387 |
-
|
| 388 |
-
for k in needed_views:
|
| 389 |
-
require_anchor(VIEW_BY_KEY[k].anchor)
|
| 390 |
-
|
| 391 |
-
# --- 3. アンカーを依存順に並べる ---
|
| 392 |
-
steps: List[Step] = []
|
| 393 |
-
anchor_serves: Dict[str, str] = {}
|
| 394 |
-
|
| 395 |
-
for name in anchors_needed:
|
| 396 |
-
base = ANCHORS[name]
|
| 397 |
-
camera = PRONE_TWO_STAGE_CAMERA if (name == "prone" and two_stage_prone) else base.camera
|
| 398 |
-
anchor = Anchor(
|
| 399 |
-
key=base.key,
|
| 400 |
-
label_ja=base.label_ja,
|
| 401 |
-
pose_prompt=base.pose_prompt,
|
| 402 |
-
camera=camera,
|
| 403 |
-
size=base.size,
|
| 404 |
-
source=base.source,
|
| 405 |
)
|
| 406 |
-
|
| 407 |
-
|
| 408 |
-
|
| 409 |
-
|
| 410 |
-
|
| 411 |
-
|
| 412 |
-
|
| 413 |
-
anchor_serves[name] = served
|
| 414 |
-
steps.append(
|
| 415 |
-
Step(
|
| 416 |
-
key=_anchor_id(name),
|
| 417 |
-
kind="anchor",
|
| 418 |
-
label_ja=base.label_ja,
|
| 419 |
-
prompt_of=anchor,
|
| 420 |
-
source="reference" if base.source == "reference" else _anchor_id(base.source),
|
| 421 |
-
size=VIEW_BY_KEY[served].size if served else anchor.size,
|
| 422 |
-
view_key=served,
|
| 423 |
-
intermediate=bool(served) and served not in requested,
|
| 424 |
-
)
|
| 425 |
)
|
| 426 |
-
|
| 427 |
-
|
| 428 |
-
|
| 429 |
-
|
| 430 |
-
|
| 431 |
-
|
| 432 |
-
|
| 433 |
-
|
| 434 |
-
|
| 435 |
-
|
| 436 |
-
|
| 437 |
-
|
| 438 |
-
prompt_of=v,
|
| 439 |
-
source=source,
|
| 440 |
-
size=v.size,
|
| 441 |
-
view_key=v.key,
|
| 442 |
-
crop_kind=v.crop_kind,
|
| 443 |
-
intermediate=k not in requested,
|
| 444 |
-
)
|
| 445 |
)
|
| 446 |
-
|
| 447 |
-
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Eleven views; no taggers or training-caption generation."""
|
| 2 |
+
from dataclasses import dataclass
|
| 3 |
|
| 4 |
+
PROMPT_VERSION = "pose-transfer-v2"
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
|
| 6 |
|
| 7 |
@dataclass(frozen=True)
|
| 8 |
class View:
|
| 9 |
key: str
|
| 10 |
+
label: str
|
| 11 |
+
camera: str
|
| 12 |
+
pose: str
|
| 13 |
+
frame: str
|
| 14 |
+
shape: str = "portrait"
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
STAND = "Stand upright in a neutral relaxed A-pose, arms lowered, legs narrowly spaced."
|
| 18 |
+
SIT = "Sit on the ground hugging both knees against the chest, arms around the shins, feet on the floor."
|
| 19 |
+
PRONE = "Lie face down on the stomach, legs straight, arms bent resting near the head."
|
| 20 |
+
FULL = "Show the entire body including the top of the head and both feet."
|
| 21 |
+
COWBOY = "Frame from the top of the head to mid-thigh; the knees and feet are outside the frame."
|
| 22 |
+
|
| 23 |
+
VIEWS = (
|
| 24 |
+
View("full_front", "全身 正面", "front view, eye-level shot", STAND, FULL),
|
| 25 |
+
View("full_left", "全身 左側面", "left side view, eye-level shot", STAND, FULL),
|
| 26 |
+
View("full_right", "全身 右側面", "right side view, eye-level shot", STAND, FULL),
|
| 27 |
+
View("full_back", "全身 背面", "back view, eye-level shot", STAND, FULL),
|
| 28 |
+
View("cowboy_front", "腿上 正面", "front view, eye-level shot", "", COWBOY, "square"),
|
| 29 |
+
View("cowboy_back", "腿上 背面", "back view, eye-level shot", "", COWBOY, "square"),
|
| 30 |
+
View("upper_front", "上半身 正面", "front view, eye-level shot", "",
|
| 31 |
+
"Show only the head, shoulders and chest; waist and legs are outside the frame.", "square"),
|
| 32 |
+
View("face_front", "顔 正面", "front view, eye-level shot", "",
|
| 33 |
+
"Close-up portrait showing the head and face, with only the top of the shoulders visible.", "square"),
|
| 34 |
+
View("knees_front", "膝抱え 正面", "front view, eye-level shot", SIT, FULL),
|
| 35 |
+
View("knees_back", "膝抱え 背面", "back view, eye-level shot", SIT, FULL),
|
| 36 |
+
View("prone_back", "うつ伏せ 後方・俯瞰", "back view, high-angle shot", PRONE, FULL, "landscape"),
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 37 |
)
|
| 38 |
+
BY_KEY = {view.key: view for view in VIEWS}
|
| 39 |
+
DEFAULT_KEYS = list(BY_KEY)
|
| 40 |
+
SIZES = {
|
| 41 |
+
"fast": {"portrait": (512, 768), "square": (640, 640), "landscape": (768, 512)},
|
| 42 |
+
"standard": {"portrait": (832, 1216), "square": (1024, 1024), "landscape": (1216, 832)},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 43 |
}
|
| 44 |
+
SIZES["balanced"] = SIZES["standard"]
|
| 45 |
+
REFERENCE_RESOLUTION = {"fast": 640, "balanced": 640, "standard": 1024}
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
def validate_keys(keys):
|
| 49 |
+
if not keys:
|
| 50 |
+
raise ValueError("視点を1つ以上選択してください。")
|
| 51 |
+
if any(key not in BY_KEY for key in keys):
|
| 52 |
+
raise ValueError("不明な視点が含まれています。")
|
| 53 |
+
return list(dict.fromkeys(keys))
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
def make_prompt(view, extra="", pose_guide=True, angles=False):
|
| 57 |
+
parts = []
|
| 58 |
+
if angles:
|
| 59 |
+
# Qwen 2.1 adapter grammar; the 2511 <sks> grammar is NOT used.
|
| 60 |
+
parts.append("<mva> " + view.camera + (" close-up" if view.key in ("face_front", "upper_front") else ""))
|
| 61 |
+
if pose_guide:
|
| 62 |
+
parts.append(
|
| 63 |
+
"Edit Image 2: replace its grey mannequin with the character from Image 1. "
|
| 64 |
+
"Keep Image 2's pose, body orientation, camera, crop and placement in the frame. "
|
| 65 |
+
"Image 1 supplies only the character design, outfit, hair and rendering style; "
|
| 66 |
+
"do not preserve Image 1's pose, camera direction or framing. "
|
| 67 |
+
"Render the character's normal skin and clothing, with no mannequin joints or grey material."
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 68 |
)
|
| 69 |
+
else:
|
| 70 |
+
parts.append("Reshoot the character in Image 1 from the requested camera and framing.")
|
| 71 |
+
if view.key in ("full_back", "cowboy_back", "knees_back"):
|
| 72 |
+
parts.append(
|
| 73 |
+
"Strict rear view. The character faces away from the viewer. "
|
| 74 |
+
"Show the back of the head, back of the hair and back of the clothing. "
|
| 75 |
+
"The face, eyes and front of the chest are hidden."
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 76 |
)
|
| 77 |
+
elif view.key == "full_left":
|
| 78 |
+
parts.append("Strict profile, with the nose pointing to the RIGHT edge of the image.")
|
| 79 |
+
elif view.key == "full_right":
|
| 80 |
+
parts.append("Strict profile, with the nose pointing to the LEFT edge of the image.")
|
| 81 |
+
elif view.key == "prone_back":
|
| 82 |
+
parts.append(
|
| 83 |
+
"Look down at the character's back while they lie face down on the floor. "
|
| 84 |
+
"Their chest and face point toward the floor, not toward the camera. "
|
| 85 |
+
"Place the head at the RIGHT of the image and feet at the LEFT, matching Image 2."
|
| 86 |
+
if pose_guide else
|
| 87 |
+
"Look down at the character's back while they lie face down on the floor. "
|
| 88 |
+
"Their chest and face point toward the floor, not toward the camera."
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 89 |
)
|
| 90 |
+
parts.extend(["Camera: " + view.camera + ".", view.pose, view.frame,
|
| 91 |
+
"Preserve the identity, hair, outfit details, colors and visual style from Image 1. "
|
| 92 |
+
"Use a plain white background. One character, no text, no collage.", extra.strip()])
|
| 93 |
+
return " ".join(part for part in parts if part)
|