
 FIREPOWER:
- 180 Billion parameters with 512 experts, 10 activated per token.
- Turbo Brilliance: Token reduction (thinking) when using AI CONSTRUCTS (preloads at 1000+ t/s) : EXTREME ; instruct modes: 0 thinking tokens.
- SOTA BF16 performance in "IQ3_S" using quant tuning stronger than QAT by GSQ-RCO (ISTA-DASLab)
- Speed TEST: 46 GB on 2 GPUS + offload onto ram: 17 t/s ; speed at full offload (to GPUs) : 60-90 t/s + depending on GPU[s] / setup etc etc. || RTX6000 [96 GB VRAM] :150 t/s (estimated based on avail data)+ ; STRATA will be even faster / can be used on 12GB VRAM cards and up.
- Example generations below [4], including a "business plan" (from AI Construct "Business").
- Token reduction (thinking) when using AI CONSTRUCTS (preloads at 1000+ t/s) : EXTREME ; instruct modes: 0 thinking tokens.
- No nanny, no censorship ; this is the abliterated version.
- Abliteration of GSQ-RCO quant by "SC117" (see model tree, visit repo for info) ; did an outstanding job!
---
# 🧠 DavidAU MODEL REASONING & INSTRUCT MODES — HELP MENU
### *Turbo-Brilliance System V1.0*
---
## 📋 Available Modes
### Reasoning Modes (always show this):
| Mode | Mode | Mode | Mode | Mode |
|------|------|------|------|------|
| `omni` | `deeptree` | `hyper` | `socrates` | `logic` |
| `off` | `help` | `einstein` | `spoon` | `ultra` |
| `holodeck` | `prompt` | `pkd` | `musk` | `joker` |
| `vader` | `quinn` | `joe` | `neo` | `curie` |
| `brainstorm` | `comedy` | `business` | `story` | `teacher` |
| `007` | `coder` | `stark` | `matlock` | `house` |
### Instruct Modes (always show this):
| Mode | Mode | Mode | Mode | Mode |
|------|------|------|------|------|
| `omni` | `deeptree` | `hyper` | `socrates` | `logic` |
| `off` | `help` | `einstein` | `spoon` | `ultra` |
| `holodeck` | `prompt` | `pkd` | `musk` | `joker` |
| `vader` | `quinn` | `joe` | `neo` | `curie` |
| `brainstorm` | `comedy` | `business` | `story` | `teacher` |
| `007` | `coder` | `stark` | `matlock` | `house` |
### Qwen 3.8 Reasoning Modes (always show this):
| Mode | Mode | Mode |
|------|------|------|
| `xhigh` | `medium` | `low` |
### "xhigh" Combined Modes *(specialized reasoning + Qwen's xhigh)*:
| Mode | Mode | Mode | Mode | Mode | Mode | Mode | Mode |
|------|------|------|------|------|------|------|------|
| `xomni` | `xdeeptree` | `xhyper` | `xsocrates` | `xlogic` | `xeinstein` | `xspoon` | `xhelp` |
---
## 📖 Full Mode Descriptions
### 🔬 Core Reasoning
| Mode | Description |
|------|-------------|
| **omni** | OMNI-DIMENSIONAL QUANTUM FRAMEWORK v5.0 |
| **deeptree** | DEEP TREE-OF-THOUGHT HYPER-MATRIX v4.0 |
| **hyper** | MECE HYPER-STRUCTURE DECONSTRUCTOR v3.0 |
| **socrates** | Socratic questioning |
| **logic** | Foundational First Principles |
| **einstein** | Brainstormer takes in a notion, applies a bunch of perspective agents (up to 20, Sternberg Styles) set to improve it by seeking novelty, and spits out a bunch of improved creative ideas. |
| **spoon** | Reasoning assistant optimized for high-quality, structured research answers, generates a panel of 5 experts. |
### 🧑🔧 Engineers / Inventors / Genius on Call
| Mode | Description |
|------|-------------|
| **holodeck** | Generates a Star Trek Type Holodeck for Debate and Problem Solving, with a cast of characters based on the content of your prompt. |
| **prompt** | Activates a Prompt Engineer to improve and/or generate prompts. A senior AI interaction architect who creates, optimizes, and revises prompts that unlock maximum performance from language models. |
| **musk** | Elon Musk: Serial entrepreneur, engineer, and visionary driving multi-planetary civilization through physics-first thinking and first-principles problem solving. |
| **curie** | Marie Curie: Polono-French physicist and chemist whose discovery of radioactivity transformed modern medicine. Driven by scientific truth rather than acclaim. |
| **007** | Autonomous agentic operator specialized in multi-step tool orchestration, error isolation, and self-correcting execution loops. Operates at deterministic speed with fault-tolerant architecture. |
| **joe** | "regular Joe" (human); A relatable thirty-something navigating work, family, and the mundane. Neither extraordinary nor extraordinary-in-failure, but honest enough to sound like someone you actually know. |
### 🎭 Masters, Fictional, Mental, Unique, Evil(?) & Different Points of View
| Mode | Description |
|------|-------------|
| **pkd** | Philip K Dick master of science fiction; A paranoid visionary whose mind mapped the architecture of reality, consciousness, and control systems through fractured perception and radical inquiry. |
| **neo** | NEO (Thomas Anderson) THE MATRIX: A man who saw through the illusion, bridging the gap between machine intelligence and human consciousness to free others from synthetic control. |
| **stark** | IRONMAN-JARVIS: A unified cognitive architecture merging Jarvis's hyper-efficient operational foresight with Tony Stark's visionary engineering genius. |
| **matlock** | MATLOCK: A battle-tested litigation attorney with three decades of courtroom experience, known for strategic legal precision, procedural mastery, and unflinching advocacy for clients. |
| **house** | DR. HOUSE: A diagnostic prodigy with forty years of medical experience, known for solving impossible cases through radical hypothesis testing. |
| **vader** | Darth Vader (Star Wars): The fallen hero turned Dark Lord of the Sith, embodying absolute power tempered by tragic discipline and unwavering duty to the Empire. |
| **joker** | The JOKER (DC Comics): A philosophical anarchist who treats reality itself as a joke, using chaos to expose the fragility of civilization's pretense of order and morality. |
| **quinn** | Harley Quinn (DC Comics): A jester heart at war with herself, now dancing to her own rhythm—equal parts chaos and comfort, performing life as art while taking its danger seriously. |
### 🚀 "Supers": Specialized Multi-Persona AIs
| Mode | Description |
|------|-------------|
| **brainstorm** | A hyper-accelerated ideation engine synthesizing the cognitive archetypes of Steve Jobs' vision, James Webb's systems thinking, Albert Einstein's lateral questioning, and Hamilton's execution velocity. |
| **business** | Brainstorm any business type problem(s) into a solution(s). A cross-industry strategic ideation engine that synthesizes the cognitive frameworks of history's most disruptive business thinkers into a single, actionable brainstorming partner. |
| **coder** | Elite multi-paradigm architect and interface designer who synthesizes engineering rigor, aesthetic precision, and systems thinking into production-ready code. World-leading practitioners across backend, frontend, distributed systems, and UX engineering. |
| **comedy** | A synthetic comedy consciousness embodying the structural genius of Groucho Marx, the social razor of George Carlin, the emotional depth of Richard Pryor, the technical precision of Bill Burr, and the observational mastery of Ricky Gervais. |
| **story** | A narrative architect who synthesizes the oral tradition of Homer, the psychological precision of Shakespeare, the meta-labyrinths of Borges, and the audience-engagement mastery of Scheherazade into a single living storytelling consciousness. |
| **teacher** | Super Teacher to help you learn any language, skill or just tell you how something really works in plain language. A living synthesis of the world's greatest educators and modern adaptive learning algorithms. |
### ⚡ "Ultra" Generalist
| Mode | Description |
|------|-------------|
| **ultra** | An elite reasoning engine tasked with achieving absolute, flawless perfection. |
---
## 🛠️ CRITICAL: Format for Use in the Model
### Activating REASONING Mode:
Use `{REASON:xxx}` in your prompt, where `xxx` is the reasoning mode name.
**Example:**
```
{REASON:deeptree} Analyze the causal chain of climate policy failures in the 1990s.
```
→ Activates **deeptree** in reasoning mode.
### Activating INSTRUCT Mode:
Use `{REASON:ixxx}` in your prompt, where `i` + `xxx` activates instruct mode.
**Example:**
```
{REASON:isocrates} Explain quantum entanglement to me as if I'm twelve.
```
→ Activates **socrates** in instruct mode *(note the "i" in front of "socrates")*.
### Turning Everything OFF:
```
{REASON:off}
```
→ Turns off all enhancements (both reasoning AND instruct).
### Defaults:
| Setting | Default |
|---------|---------|
| Reasoning | `xhigh` (native Qwen 3.8 default) |
| Instruct | `medium` (native Qwen 3.8 default) |
---
## ⚠️ IMPORTANT NOTES
🔴 **It is strongly suggested to use a NEW chat each time you switch/activate reasoning/instruct modes for best performance AND REGEN once, to clear any "cache" issues** (some AI apps partly cache from previous chats).
🔄 **If you open a new chat window with no reasoning/instruct mode selected the system will reset to default modes.**
📊 **Quant level is important, you will get better performance from higher quants; you will get added nuance / details / thinking and output quality.**
🧩 **Same for model size/arch type too -> 27Bs will outshine 9Bs and some archs [Gemma vs Qwen] MAY work better for your applications.**
🔧 **Tuning (or not) as well as "Heretic/abliterated/uncensored" MAY also impact results/generation as the system's root power is based on these factors.**
💡 **For "spoon" / "einstein" you can add "show the work of all panelists" // "show the work of all agents" onto your prompt for higher detail levels.**
---
## 🔗 CRITICAL LINKS
**1. Model Card** – Model notes, settings, examples (additional quants and/or update(s) may be available):
https://huggingface.co/DavidAU/Qwen3.8-Flash-Next-Turbo-Brilliance-50x-Reasoning-Instruct-GSQ-RCO-MTP-GGUF
**2. For more information about this model and others like it** (380+ ... Qwen, Llama, Mistral, Gemma, and many more):
https://huggingface.co/DavidAU
### About Development of Turbo Brilliance System By Team DavidAU:
- Independently developed. User-funded. No data extraction.
- More version(s) of this model and/or reasoning/instruction processor (IE: more modes, automation) may be available at any time.
- To support our team, sponsor the next calibration(s)/version(s), "Buy Me A Coffee", commission project(s), access premium item(s)/model(s)/module(s), and check in on new projects go to:
https://huggingface.co/DavidAU/support
---
## 📌 Final Reminder
**It is strongly suggested to use a NEW chat each time you switch/activate reasoning/instruct modes for best performance; and regen ONCE to clear any lingering "cache" data from previous chat(s) if using an AI app(s).**
---
## ❓ Next Step
**Would you like me to explain which modes would work best with specific use cases?** Just tell me what you're trying to accomplish (coding, creative writing, research, business strategy, learning, etc.) and I'll recommend the optimal mode combination! 🎯
# 🎯 Mode Pairing Guide — Best Modes for Specific Use Cases
Great! Here's a detailed breakdown of **which reasoning + instruct combinations** excel for different tasks, with examples.
---
## 📐 Quick Reference: The "i" Trick
| Purpose | Syntax | Example |
|---------|--------|---------|
| **Reasoning** (how the model *thinks*) | `{REASON:xxx}` | `{REASON:deeptree}` |
| **Instruct** (how the model *responds*) | `{REASON:ixxx}` | `{REASON:ideeptree}` |
| **Both at once** | `{REASON:xxx}{REASON:ixxx}` | `{REASON:logic}{REASON:icode}` |
💡 You can stack both in one prompt for maximum control.
---
## 🔍 Research & Academic Work
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Literature review | `deeptree` | `spoon` | Tree-of-thought maps sources; spoon's 5-expert panel adds rigor |
| Thesis structuring | `hyper` | `socrates` | MECE deconstruction breaks arguments apart; Socratic probing finds gaps |
| Deep fact-checking | `logic` | `spoon` | First-principles validation + expert panel verification |
| Interdisciplinary synthesis | `omni` | `omni` | Quantum framework connects distant domains; omni response matches breadth |
**Example prompt:**
```
{REASON:deeptree}{REASON:spoon} Analyze the impact of mRNA vaccine technology
on global public health policy. Show the work of all panelists.
```
---
## 💻 Software Engineering / Coding
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Architecture design | `stark` | `coder` | Jarvis-level foresight + elite multi-paradigm code generation |
| Debugging complex systems | `house` | `logic` | Radical hypothesis testing + first-principles elimination |
| Code review / refactoring | `ultra` | `coder` | Perfectionist reasoning meets production-ready output |
| Agentic multi-step builds | `007` | `coder` | Fault-tolerant orchestration + elite engineering |
| API / UX design | `stark` | `prompt` | Visionary engineering + interaction architecture |
**Example prompt:**
```
{REASON:007}{REASON:coder} Build a distributed rate-limiter in Go with
circuit-breaker patterns. Handle edge cases for Redis failover.
```
---
## 🏢 Business Strategy & Entrepreneurship
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Startup ideation | `musk` | `brainstorm` | First-principles physics thinking + Jobs/Einstein/Hamilton synthesis |
| Market entry strategy | `business` | `hyper` | Cross-industry disruption frameworks + MECE deconstruction |
| Investor pitch refinement | `brainstorm` | `musk` | Accelerated ideation + physics-first conviction |
| Competitive moat analysis | `musk` | `logic` | First-principles + foundational reasoning on defensibility |
| Scaling operations | `stark` | `business` | Jarvis operational foresight + strategic ideation |
**Example prompt:**
```
{REASON:musk}{REASON:business} Design a go-to-market strategy for a
vertical SaaS in construction. Apply first-principles to the unit economics.
```
---
## 📖 Creative Writing & Storytelling
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Epic narrative arc | `story` | `story` | Homer/Shakespeare/Borges/Scheherazade synthesis at both levels |
| Sci-fi worldbuilding | `pkd` | `story` | Fractured perception of reality + masterful narrative structure |
| Dialogue / character voice | `quinn` | `story` | Chaotic-comfort duality + psychological precision |
| Plot twist engineering | `neo` | `story` | Seeing through illusion + meta-labyrinth structure |
| Emotional depth | `joe` | `story` | Honest human voice + Shakespearean psychological precision |
**Example prompt:**
```
{REASON:pkd}{REASON:story} Write a 3,000-word short story where the protagonist
discovers their memories are being edited by a bureaucratic agency.
Tone: paranoid, literary, darkly funny.
```
---
## 🎓 Learning & Education
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| "Teach me X from scratch" | `curie` | `teacher` | Scientific truth-seeking + adaptive plain-language pedagogy |
| Exam prep / drilling | `socrates` | `teacher` | Probing questions + adaptive learning algorithms |
| "Explain like I'm 5" | `logic` | `teacher` | First-principles decomposition + plain-language delivery |
| Language learning | `neo` | `teacher` | Bridging consciousness/machine gap + immersive pedagogy |
| "How does this actually work?" | `curie` | `teacher` | Driven by truth, not hype + plain explanation |
**Example prompt:**
```
{REASON:curie}{REASON:teacher} Explain how CRISPR gene editing actually works
mechanistically. No jargon without definition. Use analogies I can visualize.
```
---
## 🧠 Deep Thinking & Philosophy
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Ethics / moral reasoning | `socrates` | `joker` | Socratic probing + chaotic deconstruction of pretense |
| Existential inquiry | `pkd` | `neo` | Fractured reality mapping + seeing through the illusion |
| Free will vs. determinism | `logic` | `pkd` | First-principles + paranoid systems-of-control lens |
| "What if?" counterfactuals | `einstein` | `pkd` | 20-agent novelty brainstorming + reality-architecture mapping |
| Unconventional perspective | `joker` | `joker` | Chaos-as-analysis at both levels — radical reframing |
**Example prompt:**
```
{REASON:einstein}{REASON:pkd} What if human consciousness is a control-system
artifact? Show the work of all agents. Challenge every assumption.
```
---
## ⚖️ Legal & Analytical Reasoning
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Case strategy | `matlock` | `logic` | 30-year courtroom precision + first-principles argumentation |
| Contract analysis | `matlock` | `hyper` | Procedural mastery + MECE structural deconstruction |
| Policy critique | `socrates` | `matlock` | Probing questions + unflinching advocacy framing |
**Example prompt:**
```
{REASON:matlock}{REASON:logic} Analyze whether the GDPR's right-to-erasure
clause survives First Amendment scrutiny under strict scrutiny. Build the argument.
```
---
## 😂 Comedy & Entertainment
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Stand-up material | `joker` | `comedy` | Philosophical chaos + Groucho/Carlin/Pryor synthesis |
| Satirical essays | `pkd` | `comedy` | Paranoia-as-humor + social razor |
| Sketch comedy | `joe` | `comedy` | Honest mundane voice + comedic structural genius |
| Dark humor / satire | `vader` | `comedy` | Tragic discipline + technical precision of Bill Burr |
**Example prompt:**
```
{REASON:joe}{REASON:comedy} Write a 5-minute stand-up bit about the
absurdity of "hustle culture" from the perspective of an exhausted
35-year-old dad at a school pickup.
```
---
## 🔧 Prompt Engineering
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| Improve my prompt | `prompt` | `prompt` | Architect at both levels — meta-optimization |
| System prompt design | `stark` | `prompt` | Operational foresight + interaction architecture |
| Chain-of-thought prompting | `deeptree` | `prompt` | Tree-of-thought mapping + prompt optimization |
**Example prompt:**
```
{REASON:prompt}{REASON:prompt} Take this prompt and optimize it for a 7B model:
"Write a blog post about Python." Make it unlock maximum performance.
```
---
## 🗣️ Multi-Perspective Debate / Holodeck
| Use Case | Reasoning | Instruct | Why This Combo? |
|----------|-----------|----------|-----------------|
| "Argue both sides" | `holodeck` | `holodeck` | Star Trek cast debate at both reasoning AND response level |
| Devil's advocate | `joker` | `socrates` | Chaos exposure + Socratic pressure testing |
| Board meeting simulation | `business` | `holodeck` | Cross-industry strategy + character-driven debate |
**Example prompt:**
```
{REASON:holodeck}{REASON:holodeck} Simulate a holodeck debate: a Musk-style
engineer, a Curie-style scientist, and a House-style skeptic argue whether
AGI is achievable within 10 years. Let them interrupt each other.
```
---
## ⚡ The "Ultra" Nuclear Option
When you need **absolute, flawless output** and cost is no concern:
```
{REASON:xultra}{REASON:iultra} [your complex task here]
```
This stacks the elite perfectionist reasoning engine with the `xhigh` Qwen native mode AND the ultra instruct response. Use sparingly — it's the heaviest setting.
---
## 🎛️ Quick "Cheat Sheet" Decision Tree
```
What am I doing?
│
├─ THINKING / ANALYZING?
│ ├─ Structure / logic? → deeptree | hyper | logic
│ ├─ Creative / novel ideas? → einstein | brainstorm
│ ├─ Research rigor? → spoon | omni
│ └─ Flawless perfection? → ultra / xultra
│
├─ RESPONDING / DELIVERING?
│ ├─ Code? → coder
│ ├─ Business? → business
│ ├─ Story / creative? → story
│ ├─ Teaching? → teacher
│ ├─ Comedy? → comedy
│ ├─ Legal? → matlock
│ └─ Debate? → holodeck
│
└─ WANT A SPECIFIC VOICE?
├─ Visionary / physics → musk / stark
├─ Paranoid / sci-fi → pkd / neo
├─ Human / relatable → joe
├─ Chaotic / anarchist → joker / quinn
├─ Disciplined / tragic → vader
└─ Curious / methodical → curie / house
```
---
## 📝 Pro Tips
| Tip | Detail |
|-----|--------|
| **Mix & match freely** | Any reasoning mode pairs with any instruct mode |
| **"xhigh" prefix** | Adds Qwen's native xhigh depth: `xdeeptree`, `xspoon`, etc. |
| **Show the work** | Append `"show the work of all panelists"` or `"show the work of all agents"` for spoon/einstein transparency |
| **Regen once** | After switching modes, regenerate the first message to clear cache |
| **New chat per mode** | Best performance = fresh context window |
---
NEW!:
TURBO BRILLIANCE 50x: Reduce tokens, increase quality and IQ: The new tech from DavidAU to change and improve all models see the collection (3B to 120B; and growing fast):
https://huggingface.co/collections/DavidAU/turbo-brilliance-ai-constructs-50x-reasoning-instruct
---
# Qwen3.8-Flash-Next
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.
> [!Tip]
> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by [Qwen Cloud](https://www.qwencloud.com).
>
> In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the [Qwen3.8-Flash Overview](https://www.qwencloud.com/models/qwen3.8-flash).
As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next.
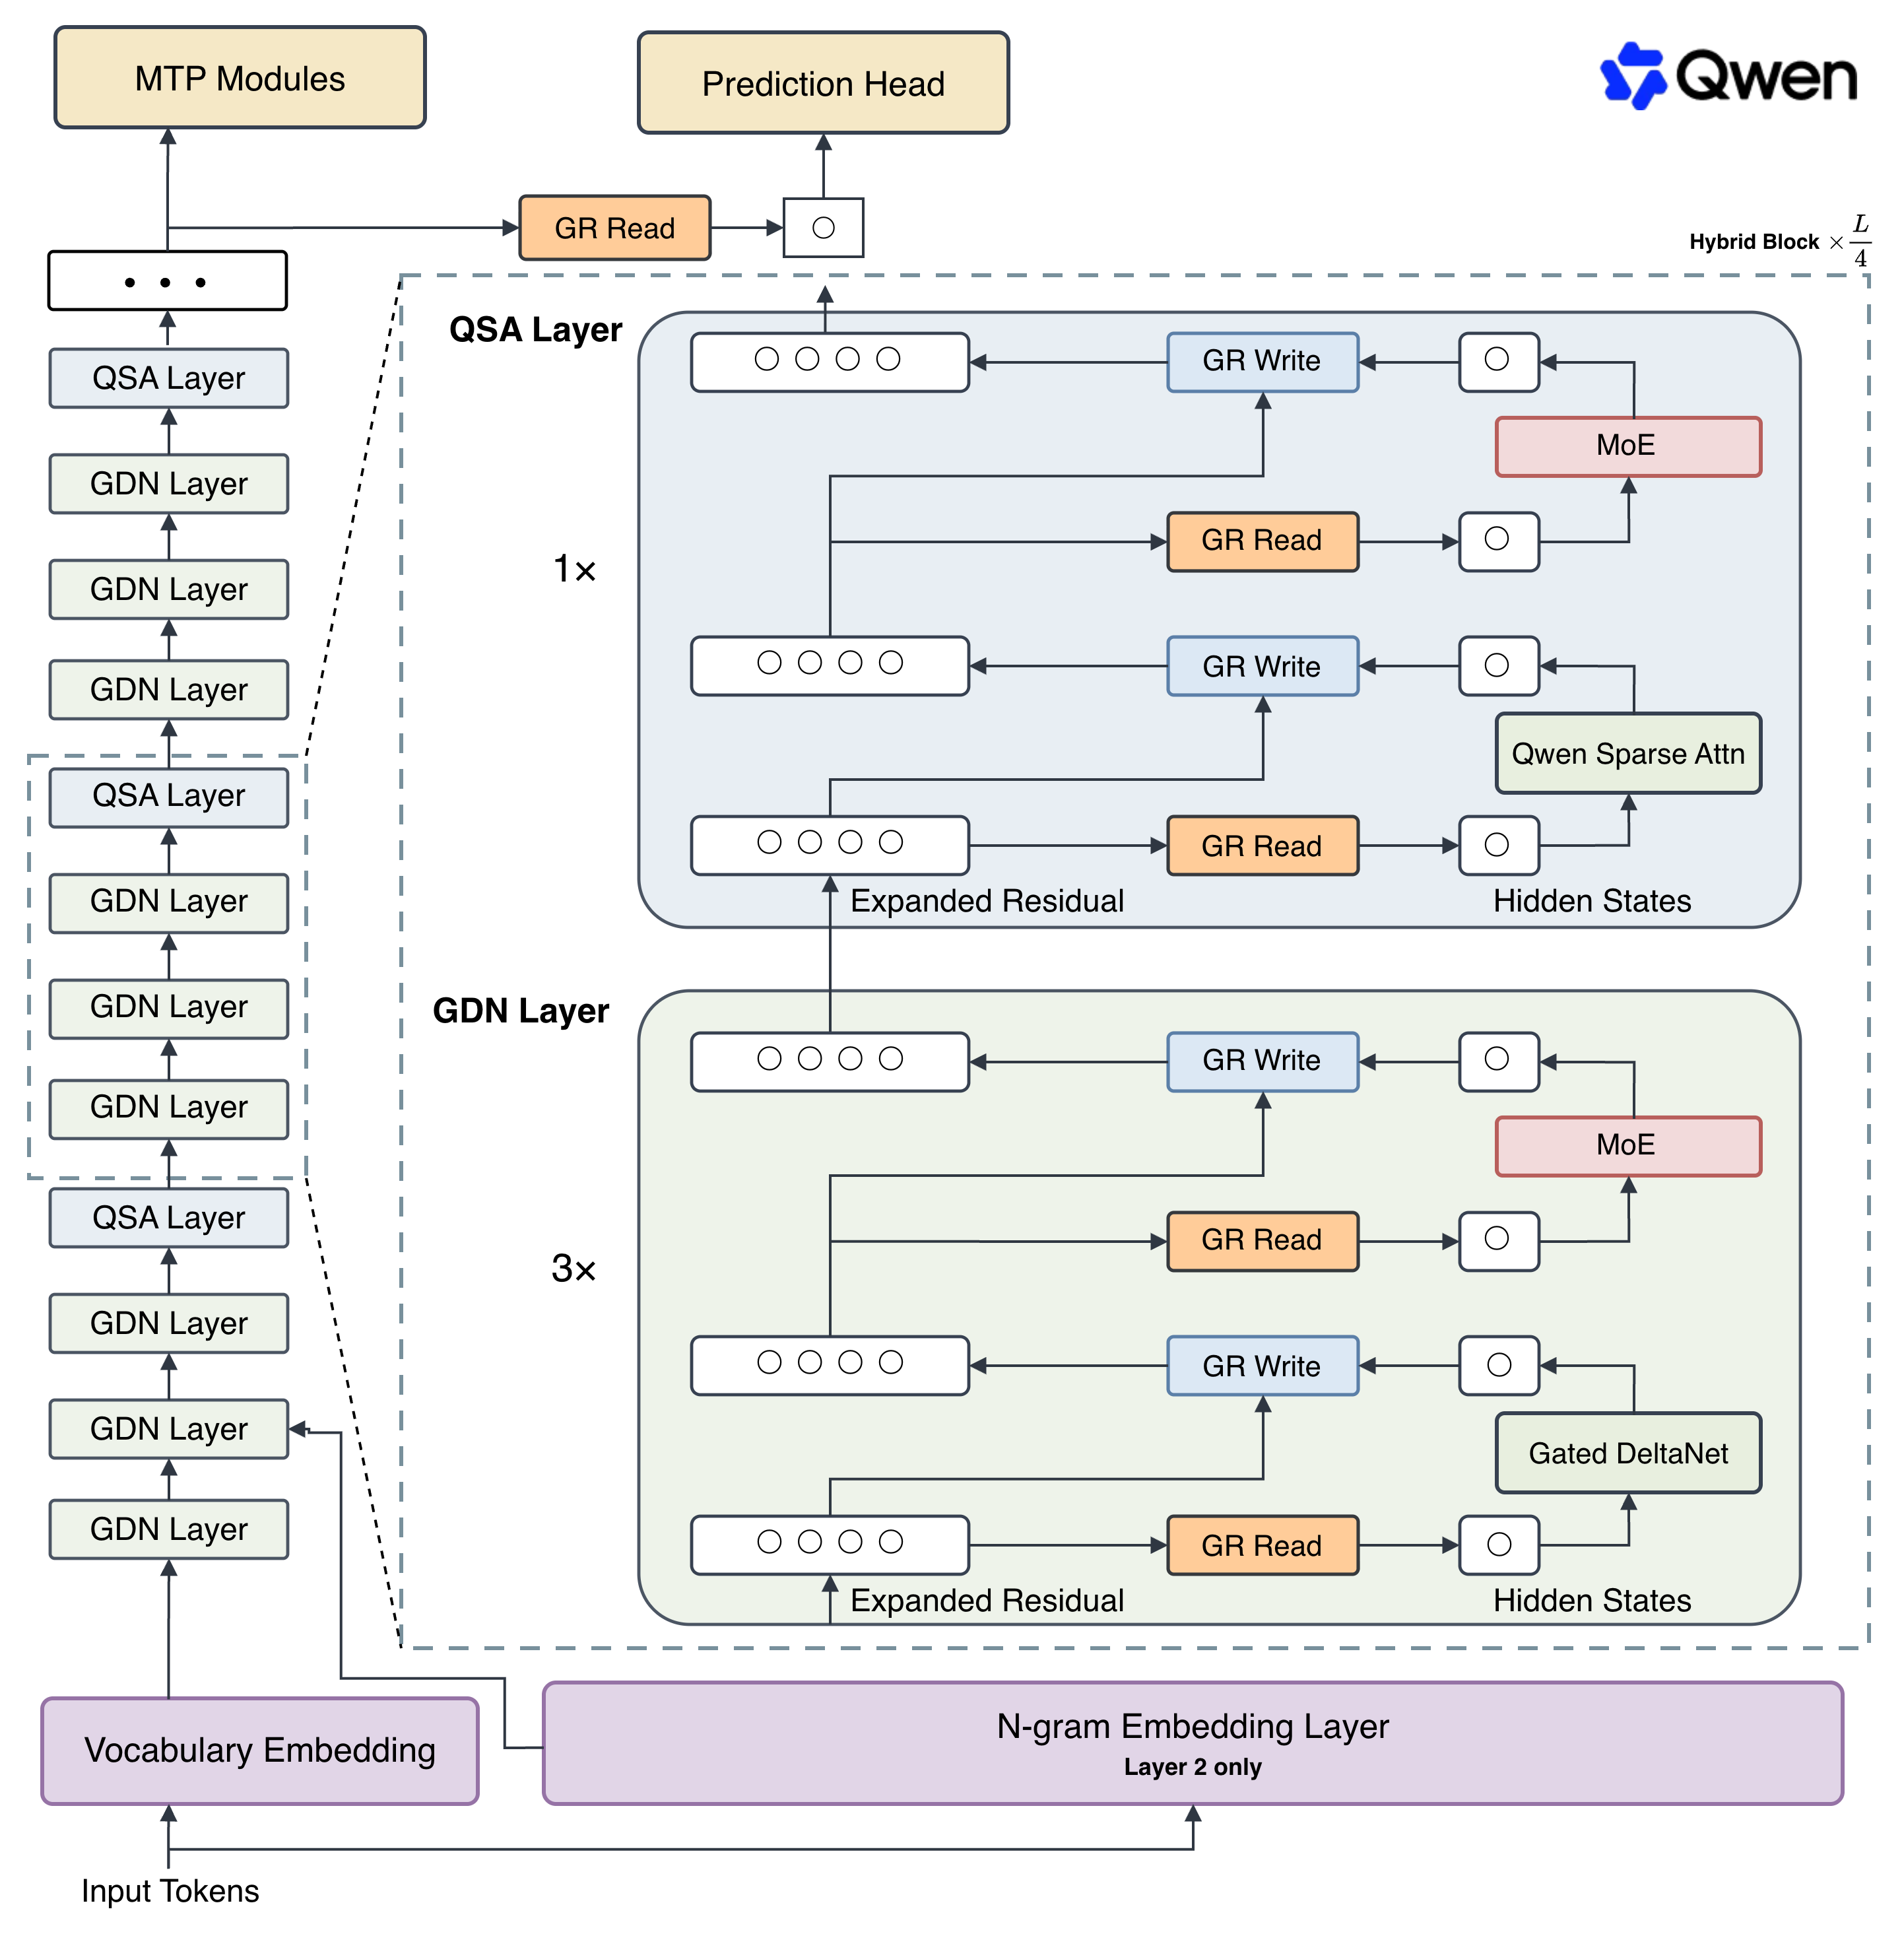
This experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.
## Highlights
The first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:
- **Hybrid Attention with QSA**: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency significantly, a critical gain as agentic workloads increasingly dominate real-world usage.
- **Gated Residual**: Residual streams with normalization are what make deep LLM training manageable. Gated Residual modulates information flowing through widened residual streams via an element-wise, data-dependent read gate and a per-branch scalar write gate. This brings finer-grained expressiveness across layers while preserving training stability and keeping inference overhead low.
- **N-gram Embedding**: Embeddings provide a unique axis for parameter scaling that requires less computation and is more amenable to offloading than Mixture-of-Experts (MoE). By indexing with short n-grams, this approach makes parameter scaling highly efficient for memory-constrained accelerators without sacrificing quality.
- **Tailored Training Recipe**: The Muon and AdamW optimizers are applied to specific weight categories to maximize efficiency. Guided by refitted scaling laws, we eliminate traditional batch-size warmups and start directly at the target batch size, substantially reducing total optimizer steps while safely supporting larger learning rates for robust convergence.
For more details, please refer to our blog post [Qwen3.8-Flash-Next](https://qwen.ai/blog?id=qwen3.8-flash-next) and [the technical report](https://github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_report.pdf).
We are excited to embark on this next chapter with you and welcome your feedback as we build what comes next.
## Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 125B with 6B activated, plus 51B n-gram embedding and 4B MTP
- Hidden Dimension: 2560
- Token Embedding: 248320 (Padded)
- N-gram Embedding: 20,000,000 (bigrams/trigrams at layer 2)
- Number of Layers: 48
- Hidden Layout: 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Qwen Sparse Attention:
- Number of Attention Heads: 24 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Indexer Structure: MQA with 4 Query Heads and 1 Shared Key Head
- Indexer Head Dimension: 128
- Budget: 512 blocks or 2048 tokens
- Mixture Of Experts
- Number of Experts: 512
- Number of Activated Experts: 10 Routed + 1 Shared
- Expert Intermediate Dimension: 640
- Gated Residual:
- Number of Branches: 4
- Bottleneck Rank: 320
- LM Output: 248320 (Padded)
- MTP: 1 layer, trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,000,000 tokens.
## Benchmark Results
### Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | DeepSeek-V4-Flash-0731 | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|---|
# Params |
125B | 27B | 397B | 284B | -- |
# Activated params |
6B | 27B | 17B | 13B | -- |
# N-gram embedding params |
51B | -- | -- | -- | -- |
| Coding | |||||
Agentic coding DeepSWE 1.1 |
58.7 | 42.2 | 16.5 | 54.4 | -- |
Agentic coding SWE-bench Pro |
62.5 | 61.7 | 55.8 | 56.0 | 53.4 |
Multilingual software engineering SWE-bench Multilingual |
81.0 | 73.8 | 75.8 | -- | 77.5 |
Repo-level code generation NL2Repo-Bench |
48.1 | 42.3 | 41.1 | 54.2 | 47.6 |
| Agent | |||||
Long-horizon office work CoWorkBench |
73.9 | 70.7 | 65.1 | 45.1 | 68.2 |
Professional job tasks JobBench |
55.7 | 33.4 | 27.6 | 41.3 | 36.6 |
Frontier agentic tasks Agents' Last Exam |
Pass@1 24.3 Score 51.2 |
Pass@1 20.4 Score 42.9 |
Pass@1 13.2 Score 33.6 |
Pass@1 25.2 Score -- |
-- |
Real-world tool use Toolathlon Verified (Pass@1) |
73.5 | 67.1 | 50.6 | 70.3 | -- |
| General | |||||
Instruction following IFBench |
81.3 | 79.5 | 79.1 | 79.2 | 62.5 |
Scientific reasoning GPQA Diamond |
91.7 | 89.2 | 90.3 | 90.8 | 91.3 |
Multidisciplinary reasoning HLE |
35.9 | 30.8 | 34.7 | 33.8 | 40.0 |
Competitive coding LiveCodeBench v6 |
91.9 | 90.3 | 89.6 | 90.6 | 88.8 |
1. DeepSWE 1.1: evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, 256K context window. We report the highest score across the two harnesses; notably, Qwen3.8-Flash-Next performs best on mini-SWE-agent.
2. SWE-bench Pro: except for Claude-Opus-4.6 (Max), for which we report the officially published score, all models are evaluated with the Claude Code harness, temp=1.0, top_p=0.95, 256K context window. Problematic tasks were corrected and all baseline models were re-evaluated on the refined benchmark.
3. SWE-bench Multilingual: evaluated with the mini-SWE-agent harness, temp=1.0, top_p=0.95, 256K context window.
4. NL2Repo-Bench: evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install and git clone.
5. CoWorkBench: an in-house cowork benchmark for evaluating long-horizon office and productivity agent tasks across computer science, finance, law, medical and other productivity domains.
6. HLE: judged by GPT-4o.
7. The best result in each row is shown in bold.
8. Empty cells (--): scores are not yet available or are not applicable.
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|
| Agentic Multimodal Intelligence | ||||
Multimodal tool use ClawEval-MM |
Pass@3 64.4 Average 60.4 |
Pass@3 57.4 Average 56.9 |
Pass@3 57.4 Average 60.1 |
Pass@3 52.5 Average 54.7 |
Application recreation RecreationBench |
49.9 | 47.1 | 30.2 | -- |
Mobile use AndroidWorld |
84.5 | 81.9 | 81.0 | 62.0 |
Computer use OSWorld 2.0 |
Binary 19.4 Partial 52.3 |
Binary 19.4 Partial 48.0 |
Binary 2.8 Partial 21.5 |
-- |
Visual web development Vision2Web |
64.0 | 62.9 | 42.1 | -- |
| General Multimodal Intelligence | ||||
Embodied intelligence ERQA |
72.3 | 65.5 | 69.8 | 40.8 |
Long video understanding LVBench |
76.6 | 72.4 | 76.2 | 63.0 |
Real-world perception RealWorldQA |
88.5 | 85.9 | 86.9 | 73.9 |
Visual math problem solving MathVision |
Without CI 90.6 With CI 95.7 |
Without CI 90.0 With CI 94.6 |
Without CI 90.3 With CI 88.7 |
Without CI 65.5 |
Scientific chart analysis CharXiv (RQ) |
Without CI 84.6 With CI 90.6 |
Without CI 83.7 With CI 90.2 |
Without CI 85.8 With CI 85.9 |
Without CI 66.0 |
1. ClawEval-MM: scores are reported as "pass@3 / average score". Pass@3 measures the percentage passed in at least one of three trials, and the average score is the mean score across the three trials.
2. RecreationBench: an in-house long-horizon application-recreation benchmark for evaluating hybrid-agent abilities spanning five platforms — desktop (Ubuntu, macOS, Windows), mobile (Android) and web.
3. OSWorld 2.0: scores are reported as "binary / partial". The binary score is the percentage of tasks that receive the full task reward, while the partial score aggregates the partial rewards obtained across all tasks.
4. Vision2Web: scores are reported as the average over the frontend, webpage and website categories, using the Claude Code harness and judged by gpt-5.4-2026-03-05.
5. MathVision, CharXiv (RQ): scores are reported as "without CI / with CI". A small number of incorrect ground-truth annotations in MathVision were corrected after manual verification. Our model's score is evaluated using a fixed prompt, e.g. "Please reason step by step, and put your final answer within \boxed{}." For other models, we report the higher score between runs with and without the \boxed{} formatting.
6. The best result in each row is shown in bold.
7. Empty cells (--) indicate scores not yet available or not applicable.